Well, it’s back! I recently won an eBay auction for an external Gotek and Amiga 500 drive selector, and that gave me the nudge I needed to make a video!
I had some great advice from Compton Harry about spontaneity and getting comfortable while being filmed. This is a continuation of that advice (Thanks man!).
Filming things that don’t really matter is great practice for the things that do.
In this post, I will cover some key concepts for those less familiar with 90s Commodore hardware, explain what happened during filming and then leave you with the finished video. Watch me flailing with drives and chips for 20 minutes!
Let’s begin with some explanations.
Some Key Concepts
Before jumping into the video, it’s worth covering the hardware and installation steps involved.
About Goteks
The Gotek floppy emulator was originally developed by Gotek System, based in Shenzhen, China, primarily for the industrial sector.
A Gotek PCB
Original Gotek Design
The Gotek was originally designed to replace 3.5-inch floppy drives in legacy hardware such as CNC machines, aviation devices and musical workstations. Many of these machines depend on floppy disks for data input, making them difficult to operate as working floppy disks become harder to find.
The Gotek functions as a hardware bridge by emulating the electronic signals of a mechanical floppy drive. Instead of using physical disks, the emulator reads digital disk images from a standard USB flash drive. USB drives can store and manage multiple virtual disks, offering modern storage reliability without requiring invasive modifications to the host machine’s internal components.
Basic Gotek with three-digit navigation display & file selection buttons
Over the years, several Gotek models have been released. Current hardware options often include usability enhancements like OLED screens for clearer file navigation, rotary encoders for quick file scrolling and built-in speakers that mimic the seek sounds of traditional drives.
Modern Gotek with OLED navigation display and file selection rotary dial
About Drive Selectors
An Amiga drive selector is a device that switches the signals between the internal floppy drive and an external drive.
Why Are Drive Selectors Needed?
In the Amiga architecture, the internal floppy drive is designated as DF0, while external daisy-chained drives are assigned as DF1, DF2 and DF3. This hierarchy is fundamentally tied to how the hardware and software interact.
The earliest Amiga 500 models used Kickstart 1.3, which has no user-accessible way to select an alternative boot drive. Later Kickstart versions, starting with 2.0, introduced the option to select a boot drive through the early boot menu:
However, a significant issue remained: the software itself. A lot of classic Amiga software used custom trackloaders. These were low-level routines that bypassed AmigaDOS and read physical disk tracks directly. Developers used them to improve loading speed, reduce memory use and add copy protection.
By bypassing AmigaDOS, these NDOS (Non-DOS) disks could:
Load faster by reducing drive head movement.
Conserve memory by not loading the full OS disk-reading library.
Prevent piracy through non-standard disk formatting.
The downside was that many of these disks were hard-coded to expect DF0. Even if a program was launched from DF1, it might still look for files or data on DF0. If DF0 was empty, the Amiga would crash or simply hang.
That is where a drive selector becomes useful. Rather than changing the software, the selector changes the hardware’s view of the drives.
To understand how a drive selector works, one must look at the 8520 CIA (Complex Interface Adapter) chips on the Amiga motherboard. Specifically, CIA-A (located at address $BFE001) is responsible for handling the floppy disk interface signals, including the Drive Select lines.
An Even CIA Chip
Upon boot, the Amiga identifies which drive to talk to using four active-low Select signals: _SEL0, _SEL1, _SEL2, and _SEL3.
_SEL0 triggers the internal drive DF0.
_SEL1 triggers the first external drive port DF1.
A drive selector sits between the CIA-A chip and its socket. It intercepts the relevant traces and swaps the logic lines when activated:
The _SEL0 signal coming from the CIA is routed to the motherboard’s DF1 circuitry.
The _SEL1 signal is routed to the internal DF0 circuitry.
Because this happens electrically before the signal reaches the drive cables, the Amiga does not know anything has changed. It still believes it is talking to the internal drive, but the signal is actually being redirected to the external Gotek.
That gives a level of compatibility that software-based drive remappers cannot always match. Even persistent trackloader-based software will treat the Gotek as if it were an internal drive.
A fitted drive selector and switch
Video
Here’s the full video walkthrough of the install – droppages, shark noises and all!
Video Summary
In the video, I open my 1991 Amiga 500 Plus and install a drive selector PCB. I took a fairly quick-and-dirty approach and worked around the internal components, but in hindsight I should have removed the floppy drive entirely to give myself more room.
The installation involves carefully removing the Even CIA chip from its socket on the motherboard. I then connect the drive selector PCB to the original 40-pin socket and place the chip into the selector.
After that, I test the setup with an Amiga Test Kit floppy disk and a Cannon Fodder ADF. The selector successfully redirects the DF0 boot signal to the external Gotek, letting me boot from USB while keeping the original internal floppy drive fully functional.
This is not presented as the optimal method – retro hardware can be unpredictable, and a cleaner approach would involve removing more components before starting.
Video Chapters
If you prefer, you can jump to specific sections using the chapters below.
20:05 – Final Demo: Loading Cannon Fodder from the Gotek
Technical Errata & Clarifications
02:08 – I called it a “Godrive,” I meant Gotek.
09:25 / 10:11 – I mentioned “bent chips” – I meant the metal pins/legs!
11:14 – Confirming: The 8375 Agnus is the 2MB Chip RAM version. Standard A500 Agnuses (8370/71/72) only support 512KB or 1MB.
17:15 – The Guru Meditation was likely a seating issue with the CIA adapter. If the pins aren’t making perfect contact, the CPU will throw this error immediately.
17:53 – The ticking sound is the stepper motor resetting to track 0. It has nothing to do with the drive heads.
Plus I erroneously call it a ‘Drive Switcher’ throughout. Oops.
Summary
In this post, I installed a drive selector in my Amiga 500 Plus, letting it boot from USBs and a Gotek instead of floppy disks.
I had fun with this! Which was the point! It was a chance to work on something familiar in a cosy space, and get more comfortable on camera while doing it. This and the recent Kubernetes lab reminded me why I like retro projects so much: they are practical, technical and just unpredictable enough to keep things interesting.
Like this post? Click the button below for links to contact, socials, projects and sessions:
This year, I plan to take the Certified Kubernetes Administrator (CKA) exam. I’m familiar with tech certifications, having earned my first one in 2019. However, the CKA differs from these exams in that it is a performance-based test that requires completing multiple tasks from the command line with Kubernetes.
I’ve been using Mumshad Mannambeth’s Udemy course, and while it includes several labs I also want to get some extra practice. So I started looking into setting up a Kubernetes lab, and found that I already had access to several devices capable of running one! I have since successfully created my lab, and this post examines how I got there.
I’ll begin by explaining my decision to use the 2011 PC for my Kubernetes lab over other available options, as well as the repairs it needed to get going. Next, I’ll describe the process I followed to select a suitable operating system. Finally, I’ll outline the steps taken to test the PC and install the necessary lab components.
Hardware Selection
In this section, I explain why I chose the 2011 PC for my Kubernetes lab over other available options. While this may seem redundant given the blog title, I wanted to share my considerations and thought processes.
I considered three options:
Raspberry Pi Cluster
Amazon EC2 Instances
A 2011 PC
Raspberry Pi Cluster
The Raspberry Pi is a compact single-board computer widely used for building low-power projects and clusters. It enables users to run Linux and explore different architectures, providing an efficient way to learn about distributed systems without the energy costs of traditional servers.
While the humble Pi may not be the most obvious choice for a Kubernetes lab, a Kubernetes Up & Running appendix covers building a Kubernetes cluster on Raspberry Pi. So it was worth considering!
Raspberry Pi Cluster Pros
No Virtualisation Overhead: Running Kubernetes on bare-metal Raspberry Pis removes the need for a hypervisor, allowing all ARM processor cycles and RAM to be fully dedicated to the lab.
True High Availability Testing: A Raspberry Pi cluster uses a “shared-nothing” architecture. Unplugging a node forces the cluster to demonstrate its real-time self-healing capabilities.
Energy Efficiency: While an old PC draws 60W–100W, a 3-node Pi cluster runs on under 15W. This makes 24/7 operation significantly cheaper.
Raspberry Pi Cluster Cons
High Capital Expense: A starter kit with nodes, reliable power supplies and network gear easily exceeds £100 in 2026. I already own a Pi 4, but I’d still need everything else.
Component Rigidity: Unlike a desktop PC with swappable RAM, Pi memory is soldered in place. Increasing a Pi’s RAM requires a complete hardware refresh, which limits the lab’s long-term lifecycle.
Storage Fragility: Constant logging in Kubernetes can degrade standard microSD cards within months. Reliable operation usually requires booting from USB SSDs, which increases both cost and physical clutter.
EC2 Instances
Amazon EC2 is a standard service for on-demand virtual servers that lets users rent computing capacity in AWS data centres. It operates on a “pay-as-you-go” model, allowing users to launch and terminate instances with the required CPU and RAM as needed.
Note that Amazon also provides Elastic Kubernetes Service (EKS). However, EKS is a managed service and I want to practise the manual Kubernetes setup process.
EC2 Pros:
Production Parity: EC2 offers a realistic environment with the same features and specs as a professional enterprise deployment.
On-Demand Scalability: Complex node architectures can be quickly created or deleted, enabling the testing of scenarios that would take hours to set up on physical hardware.
No Hardware Maintenance: The cloud provider manages the entire bare-metal abstraction. Users are not responsible for managing the hypervisor, physical cooling or local network switching.
EC2 Cons:
Ongoing Costs: Even small t3.micro instances accumulate costs quickly. A three-node lab running 24/7 would eventually cost more than the other options.
Reduced Learning Opportunities: AWS manages most of the backend networking. This limits opportunities to learn about topics such as network bridges, VLANs or physical NIC teaming.
Internet Dependency: The lab’s reliability depends on my home internet connection. If it drops, the entire cluster is unreachable.
On the back are four of the PC’s six USB 2.0 ports (none of your fancy USB 3.0 here), three audio ports, VGA and DVI outputs (no HDMI) and the Ethernet port:
So how does it stack up?
HP Pavilion Pros:
No Capital Expense: Turning existing hardware into a learning tool prevents e-waste and incurs no cost.
Full Hardware Control: The PC provides full access to the hardware BIOS, the physical network stack and the hypervisor kernel. This offers an in-depth understanding of how the lab works.
Expandability: The PC allows for modular upgrades, making it easy to add more RAM, replace a hard drive or install new network and graphics cards. In contrast, these upgrades can be challenging or even impossible with a cluster of Raspberry Pis.
HP Pavilion Cons:
Power Inefficiency: The PC must stay on while the lab operates. This will use more power than the other options, and the power supply, which is from 2011, may be less efficient than modern ones.
Legacy Components: The ageing processor, RAM, and ports mean that using the PC will not offer as smooth an experience as a group of Raspberry Pis or EC2 instances. It will lack speed, portability, and hardware redundancy.
Repairs Needed: So this leans into why I have this PC in the first place. It do be poorly!
Its biggest problem is the hard drive, which currently boots to an imminent failure warning before failing entirely:
The WiFi card is also unreliable. This wasn’t a major issue in the past because it was positioned next to the router and had a constant Ethernet connection. However, this limited its placement options, and it poses a problem now.
Hardware Decision
So why, with all these negatives, did the PC win? It came down to control, simplicity and cost.
Infrastructure Control
With a single physical device, I have complete control over every layer of the stack. I can customise the storage, upgrade the RAM or change the internals whenever necessary. This is impossible with a Pi cluster and limited with EC2 instances.
Minimal Operational Complexity
A PC simplifies everything by combining all components into one device, eliminating the need to manage multiple setups. This way, I can focus on learning Kubernetes instead of juggling cables and managing security groups.
Cost Efficiency
Using a PC lets me avoid the high capital expenditure costs of a Raspberry Pi cluster or the ongoing operational expenses of EC2. Instead, I can invest in repairs and upgrades for the PC and eventually replace it when it fails.
Next, let’s get onto those repairs!
Repairing The PC
If this 2011 PC is going to run Kubernetes, it needs some repairs! In this section, I’ll triage the PC and attempt to fix its issues. For clarity, those issues are prioritised in the following order:
Dead hard drive
Low RAM
Questionable WiFi card
Hard Drive Replacement
Addressing the biggest problem first, that knackered hard drive must go! While fixing hard drives isn’t impossible, it needs specialised skills and is labour-intensive. And in this case, it’s not worth the effort. There’s nothing valuable on the drive, and due to its age it could fail at any moment. That makes this a replacement job!
Thankfully, I made this decision a while ago – well before the current hard drive cost spike! I realised I needed neither an SSD’s speed nor a terabyte of storage. So I bought a Seagate Barracuda ESA-3502 500 GB HDD as it reviewed well and came in at a bargain price of £19.99 (as opposed to the current £35.99 asking price!)
RAM Upgrade
Next, let’s talk about RAM. Although Kubernetes can operate with just 4GB of memory, the virtual machines and the PC also require some memory to function properly. Having such a low memory limit will lead to various problems. The VMs may become too slow, and the PC itself might encounter performance issues.
Over the years, I’ve owned many computers. And like many people in the IT profession, I have various cables, heat sinks, and parts salvaged from computers that were destined for the scrap heap!
Among these items, I found two 8GB DDR3 RAM sticks which I swapped for the PC’s two 2GB sticks. Now this may not work, as the PC’s specs specify that each slot’s maximum memory capacity is 4GB. No harm in trying though, eh?
Internet Access
Finally, let’s discuss the WiFi situation. The WiFi card is already known to have issues, and the PC is on a different floor from my home router so I can’t use Ethernet. This won’t affect the operating system installation, as both the USB ports and the optical drive work. But I won’t then be able to download any updates, firmware or the various Kubernetes components.
Enter my Raspberry Pi 4! This is fully capable of connecting to my WiFi and sharing that connection with my PC. It acts as a NAT (Network Address Translation) router, managing the communication between its wireless interface (wlan0) and its wired Ethernet interface (eth0). This setup is similar to how a home router shares a single public IP address among multiple devices.
Here is what happens at the network layer:
The Pi connects to the WiFi network via wlan0 and receives an IP address from the router (e.g. 192.168.1.12). The router sees the Pi as another wireless client.
The Pi assigns itself a static IP on eth0 in a separate subnet (e.g. 10.0.0.1) and runs a small DHCP server on that interface via dnsmasq. The PC will use this network.
The Pi and PC’s Ethernet ports are then wired together.
When the PC sends traffic intended for the internet, it is routed to the Raspberry Pi, which serves as its default gateway.
The Raspberry Pi modifies the packet’s source IP address to match its own wlan0 address before forwarding it upstream. This process is known as NAT Masquerading.
Incoming replies are received by the Raspberry Pi, which translates the IP addresses back to their original format and then forwards them to the PC.
That’s everything! The PC should now boot. But boot what?
OS Selection
As I’m replacing the PC’s hard drive, I can also upgrade the operating system. Since I plan to run virtual machines on the 2011 PC for my Kubernetes nodes, the host OS will act as a hypervisor.
It will handle three critical tasks:
Resource Management: Allocating CPU and RAM for each VM.
Storage: Managing how the VMs access the physical hard drive.
Networking: Creating a bridge so VMs can talk to each other and the internet.
Keep in mind that the OS selections for the 2011 PC and for the Kubernetes VMs are independent choices and needn’t be the same. For instance, Windows can run WSL, and a Debian host can run Ubuntu VMs. The decision on the VM OS will be made after the host OS has been determined.
Let’s start with the traditional players. Which, it turns out, aren’t all that suitable…
Windows
Windows is the most widely used desktop OS and provides a professional-grade virtualisation platform through Hyper-V. While it is a strong option for running enterprise mixed-OS environments, its architecture is poorly suited for a dedicated Linux-based lab on legacy hardware.
Tooling Incompatibility: The standard open-source orchestration stack, including virt-manager, cloud-init, and virsh, is designed for the Linux/KVM ecosystem. Managing a Windows host on the 2011 PC needs a distinct set of PowerShell tools, adding unhelpful complexity to the learning process.
Resource Inefficiency: A Windows host uses a significant amount of RAM and CPU cycles to operate its GUI and background telemetry. On a dual-core i3-2120 with 4GB of RAM, this operational overhead leaves less room for the guest VMs.
Storage Latency: The NTFS file system, along with Windows’ aggressive background indexing and telemetry, creates significant disk contention. This latency becomes more pronounced on older mechanical drives, leading to slower boot times and reduced responsiveness for virtual disk images.
macOS
macOS is well known for providing an exceptional developer experience and is the primary OS used by many in the DevOps community. However, its kernel is optimised for use as an interactive workstation rather than as a persistent, headless hypervisor host.
Kernel Abstraction: macOS does not have a built-in hypervisor compatible with Linux, so tools like Docker Desktop or Lima must run a helper VM to create a Linux environment. This results in nested virtualisation, where one VM runs inside another, complicating networking and reducing performance.
Architecture Mismatch: Most production Kubernetes clusters are designed for amd64 architecture. Running amd64 nodes on an Apple Silicon Mac involves using QEMU for emulation. This method reduces performance and can introduce subtle behavioural bugs in low-level networking and storage drivers that don’t appear on native hardware.
Hardware Inflexibility: macOS is optimised for interactive power management. When used as a persistent, headless server, the OS often deprioritises background tasks or enters sleep states. This can disrupt the high-availability heartbeats needed by a Kubernetes cluster.
Linux
Linux is the industry standard for virtualisation. KVM (Kernel-based Virtual Machine) is built directly into the Linux kernel, making virtualisation a primary feature rather than an additional component. Linux also spotlights the key components used by both hypervisors and Kubernetes: namespaces, cgroups, and network bridges, without the licensing issues of proprietary operating systems.
Linux has many distributions, each with its own package manager, default software and design philosophy. I considered the following Linux distros:
Alpine is designed for minimal-footprint environments where reducing attack surface and efficient resource use is crucial. It serves as the base image for many public Docker containers and is employed in embedded systems and security-focused infrastructure, where any unnecessary package can pose a risk.
Alpine Pros
Extreme Resource Efficiency: Alpine generally uses 50-80 MB of RAM while idle. This optimisation reduces host-level overhead on older hardware, maximising resources for guest VMs.
Reduced Attack Surface: Alpine minimises potential attack vectors by removing unnecessary binaries and packages.
Lightweight Init System: It uses OpenRC instead of systemd, resulting in quicker boot sequences and service management through transparent shell scripts.
Alpine Cons
GNU Toolchain Friction: Alpine replaces the standard GNU utilities with BusyBox. However, resources such as the KVM documentation assume GNU, so commands must be translated for BusyBox.
Standard Library Divergence: The use of musl libc instead of glibc can lead to silent failures and unexpected problems with precompiled binaries or certain kernel modules.
Manual Configuration: In Alpine, certain administrative tasks that are automated in other distributions, such as kernel module persistence and complex network bridging, require manual intervention.
Debian Linux
Debian is designed for stable, long-term server infrastructure, prioritising predictability over having the latest software. It serves as the foundation for several distros, including Ubuntu and Raspberry Pi OS, and has built a reputation based on a careful release process that emphasises reliability.
Debian Pros
Predictable Performance: A minimal Debian installation uses less than 200MB of RAM. Its lack of unnecessary background processes reduces disk I/O contention on mechanical hard drives, which is vital when multiple VMs are swapping.
Streamlined Architecture: Debian avoids using the snapd daemon and its loop-device overhead. This method keeps the host’s kernel routing table and mount points organised, simplifying the troubleshooting of VM network bridges.
Universal Binary Compatibility: Debian uses the standard glibc library. This compatibility allows enterprise virtualisation tools and guest agents to run natively without extra layers. As a result, Debian can use Ubuntu’s software ecosystem while minimising the associated service overhead.
Debian Cons
Manual Installation: Debian’s installer requires careful decisions about partitioning and mirror selection, as misconfigurations can cause issues.
Firmware Hurdles: Although hardware detection has improved, proprietary firmware for older network and WiFi cards may still need to be manually included from the “non-free” repository during initial setup (although from Debian 12 onwards this is less of a problem than it used to be).
Conservative Packaging: Debian prioritises stability over the latest software versions. Accessing the latest QEMU or libvirt features occasionally require the use of the backports repository.
Ubuntu Linux
Ubuntu is the most popular Linux distribution used in cloud and server environments. It is often the default choice referenced in DevOps and Kubernetes documentation. Commercially supported by Canonical, Ubuntu has a regular release schedule and offers long-term support versions suitable for both enterprise and home users.
Ubuntu Pros
Native Documentation Sync: Most KVM and libvirt guides are written with Ubuntu in mind. File paths and package names at the host level will closely align with the most common reference materials.
Extensive Driver Support: Ubuntu’s Hardware Enablement (HWE) stack includes proprietary drivers by default. This guarantees that niche hardware components on older PCs will work right away, eliminating the need for manual troubleshooting.
Commercial Maturity: Ubuntu provides a regular release schedule and strong community support for troubleshooting complex virtualisation scenarios such as GPU passthrough and nested virtualisation.
Ubuntu Cons
Service Overhead: The inclusion of snapd, cloud-init and automated update daemons result in an idle footprint of 300–400 MB. On hardware with low RAM, this consumes vital memory before a single VM starts.
Network Abstraction: Ubuntu uses the Netplan abstraction for network configuration. This adds a layer of YAML complexity as opposed to the direct control of the traditional /etc/network/interfaces file.
I/O Latency: Background services like unattended-upgrades can trigger sudden changes in disk activity. On older mechanical drives, this can cause guest VMs to experience latency spikes during high-load operations.
OS Decision
For my 2011 PC Kubernetes lab, Debian is the optimal choice. While Alpine is leaner and Ubuntu is more automated, Debian provides the best performance-to-stability ratio for a 2011-era PC acting as a VM host.
CPU and I/O Contention
Debian offers a more stable environment with fewer background processes compared to Ubuntu. This is particularly useful for a PC with an Intel i3-2120 dual-core processor, as it reduces the number of running daemons and minimises disk activity. This will improve VM performance and Kubernetes cluster stability.
Fastest Success Path
Debian occupies a sweet spot between Ubuntu’s excess and Alpine’s frugality, letting me set up a Kubernetes lab quickly without making significant changes to the OS.
Hypervisor Consistency
A hypervisor host functions best on a reliable foundation. Debian’s stable release offers fixed package versions and a cautious update policy, ensuring that the KVM toolchain, network bridge drivers and configurations stay consistent. This stability prevents version drift that could disrupt networking or storage for the guest VMs.
Testing Old PC
In this section, I conduct a smoke test of the 2011 PC and Debian to check that my repairs were successful and that the system is stable enough for virtualisation and Kubernetes.
Hard Drive Test
The first test is the simplest. When activated, the PC immediately detects the replacement hard drive. It then uses my Debian USB to run the installer, progressing through each stage without issue.
I’m installing Debian 13 – the most recent version, released on 9 August 2025. For those curious, this video shows a typical Debian 13 installation:
I mentioned earlier that the installer requires some careful decisions. One of these is the choice of Debian desktop environment:
There are several choices here that control how minimal or feature-rich the desktop is. Many guides recommended the bare minimum SSH server to maximise the resources available for Kubernetes. I chose to install Xfce – a lightweight GUI designed for older or limited-resource hardware. This will let me see the various Debian backend files and folders in a familiar Windows-like environment, helping me understand Kubernetes’ inner workings.
This video explores several Debian desktop environments, including Xfce:
RAM Test
Next, let’s assess the RAM. This was partially verified during the hard drive test, as faulty RAM would have either caused issues during the Debian installation or prevented the PC from booting outright. But how much RAM is actually available?
With a successful Debian install, I can run free -h to find out! This shows 15GB memory with 14GB free:
This is…interesting given the PC’s stated maximum of 8GB! Indeed, running dmidecode to query the BIOS states that the maximum capacity is 8GB:
Having researched, there are two main reasons for this:
Outdated BIOS Info: The motherboard’s DMI table, which dmidecode uses for information, was created when 4GB sticks were the known maximum limit, and HP never updated it.
Ambiguous Definition: Sometimes “Max Capacity” refers to the per-slot maximum rather than the entireboard‘s total. And there are two devices (slots), so 2x 8GB is 16GB.
In any case, free -h can be trusted so I do indeed have 16GB RAM!
I can also use lscpu to verify how many cores the PC has. The Intel Core i3-2120 is a dual-core processor with two physical cores. It features Intel Hyper-Threading, allowing each core to present two threads (logical processors) to the OS, resulting in a total of four threads.
Internet Test
Finally, let’s test the internet. Running ping -c 4 8.8.8.8 in the terminal returned packets successfully, and running sudo apt update fetched the latest package list:
With everything set up, there’s just one step remaining to convert my 2011 PC into a Kubernetes lab.
Configure Virtualisation
In this section, I outline the steps taken to install the software needed for the 2011 PC to function as a hypervisor in my Kubernetes lab. Please note that I do not claim this to be the definitive or best approach; it simply reflects my process for getting everything up and running on this occasion.
Installing Libraries
It’s now time to equip Debian with the necessary tools for virtualisation. This resulted in a fairly large install command, with each component contributing to my lab’s stability and manageability.
So, what is all this actually doing? Let’s examine in stages.
Core Components
qemu-kvm: This forms the core of the entire system. KVM is a Linux kernel module that lets a CPU run VMs at speeds nearly matching those of physical hardware. QEMU manages the rest of the hardware emulation, providing the virtual motherboard, disk controllers and network cards that the guest OS recognises as genuine. Together, these components turn a PC into a platform capable of hosting multiple VMs.
bridge-utils: While VMs are isolated by default, bridge-utils creates a virtual switch that links them directly to a physical network. This is crucial for a Kubernetes lab, as it allows each node to obtain its own IP address and route traffic through the Raspberry Pi bridge. By using the host’s Ethernet connection in this way, the VMs gain the stable internet access required for cluster orchestration and updates.
Lifecycle & Control
libvirt-daemon-system: This package operates as a daemon responsible for managing VM lifecycles. It monitors active nodes, controls startup and shutdown processes, and ensures that a VM crash does not impact the entire system.
libvirt-clients: This provides the command-line tools needed to interact with libvirt-daemon-system, most notably including virsh – an industry-standard utility for managing VMs via the terminal. It can check statuses, modify configurations and reboot nodes from the terminal.
Provisioning & Optimisation
virtinst: This package yields virt-install, a command-line tool for creating VMs. Instead of going through a wizard multiple times, one command now specifies the CPU, RAM, and disk for multiple nodes. This makes setting up Kubernetes nodes quick and repeatable.
libosinfo-bin: Virtualisation works best when the host has detailed knowledge of the guest OS. This tool serves as a database that guides the hypervisor in using appropriate high-performance drivers for each VM. This technique allows the main CPU to conserve its cycles by reducing reliance on inefficient hardware emulation.
Monitoring & Troubleshooting
virt-manager: Although the primary goal is to manage the VMs through the terminal, I also want a GUI as I familiarise myself with the system. Virt-manager offers a graphical interface to monitor CPU and RAM usage in real time.
virt-viewer: If a VM fails to boot or loses its network connection, SSH access is impossible. This package opens a window that displays the VM’s console, allowing users to troubleshoot the boot process or fix a broken config file as if accessing it directly.
Testing Virtualisation
Having installed everything, I now need to test that the hypervisor works. On Debian, installing the packages doesn’t always mean the services are active and ready to run. So firstly I need to start the virtualisation daemon manually:
Bash
sudosystemctlenable--nowlibvirtd
And then check virtualisation is running:
Bash
sudosystemctlstatuslibvirtd--no-pager
It should show a green active (running) status. But…uh oh.
This error means virtualisation isn’t enabled. And that means a trip to the PC’s BIOS settings!
With VTx enabled and a reboot later, the libvirtd service is now active:
Running kvm-ok (installed via cpu-checker)also shows the PC can now host hardware-accelerated KVM virtual machines. I can now run virt-manager to load the GUI:
This loads the Virtual Machine Manager, from which I can create and interact with my VMs via a GUI:
My 2011 PC can now spin up some Kubernetes nodes!
In terms of next steps, I’ll use the Kubernetes documentation to turn the 2011 PC into a multi-node cluster. The CKA is open-book, and getting familiar with the documentation will be a massive help during the exam!
Summary
In this post, I documented the journey of resurrecting a dusty old 2011 PC into a functional Kubernetes lab to prepare for my CKA exam.
This experience was a nice blend of familiar and new. While I’ve worked extensively with Linux, I’ve not gone into the weeds with various distros before. Nor have I built my own NAT router! Ultimately, this was a fun and engaging project and I’m looking forward to kicking the tyres of my new lab!
Like this post? Click the button below for links to contact, socials, projects and sessions:
Earlier this month, AWS launched new CloudFormation features for importing existing AWS resources:
AWS CloudFormation launches a new feature that makes it easy to generate AWS CloudFormation templates and AWS CDK apps for existing AWS resources that are managed outside CloudFormation.
You can use the generated templates and apps to import resources into CloudFormation and CDK or replicate resources in a new AWS Region or account.
An announcement from AWS Ray Of Sunshine Matheus Guimaraes followed this:
I’ve suggested something like this to AWS before, so I was very keen to try IaC Generator with my recently created WordPress data pipeline resources!
Firstly, I’ll explain some of the fundamental concepts of CloudFormation and the IaC Generator. Next, I’ll run the generator on my AWS account and see what comes back. Finally, I’ll run some tests and give my findings and thoughts.
Services Primer
This section introduces AWS CloudFormation and the IaC Generator, and explains what they’re for.
AWS CloudFormation
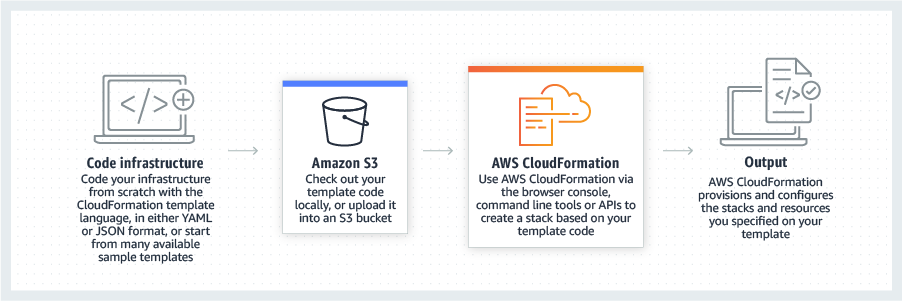
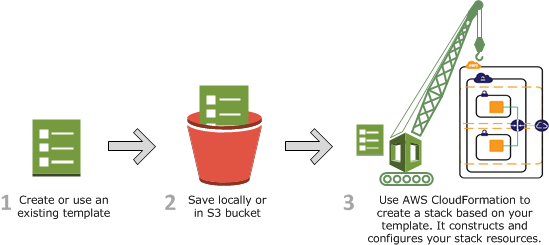
AWS CloudFormation is an infrastructure as code (IaC) service that manages and provisions AWS resources using code and automation instead of manual processes. It can configure resources, handle dependencies and estimate costs as part of a reproducible version-controlled CI/CD pipeline.
CloudFormation has extensive functionality. For this post, the two concepts I’m most interested in are:
CloudFormation Templates: JSON or YAML formatted text files which serve as blueprints for building AWS resources. Templates form the basis of CloudFormation Stacks.
CloudFormation Stacks: Collections of AWS resources that are managed as a single unit. Creating, updating or deleting a stack directly influences the related resources. Stacks can represent constructs like serverless applications, web servers and event-driven architectures.
The CloudFormation User Guide has further reading with sample code.
CloudFormation IaC Generator
The IaC Generator is a CloudFormation feature designed for use with manually provisioned resources:
With the AWS CloudFormation IaC generator (infrastructure as code generator), you can generate a template using AWS resources provisioned in your account that are not already managed by CloudFormation. Use the template to import resources into CloudFormation or replicate resources in a new account or Region.
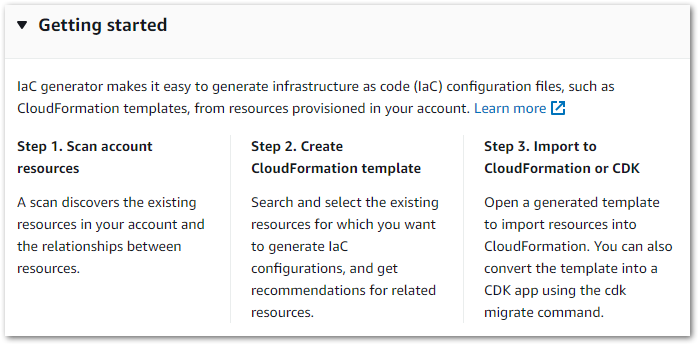
In this section, I have an IaC Generator hands-on using CloudFormation’s console. Let’s start with an account scan.
Account Scan
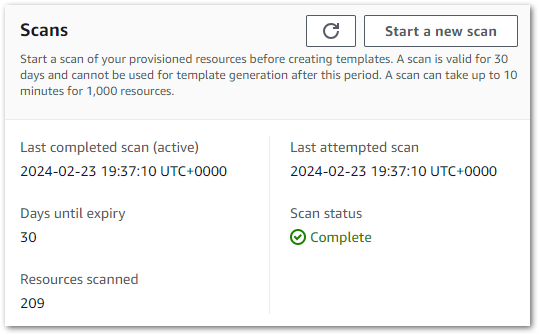
Firstly, IaC Generator needs to know about my AWS account’s resources. The generator then uses a completed scan to create a resource inventory which is valid for 30 days.
IaC Generator scans are limited per day. Accounts with under 10,000 resources can perform 3 daily scans, while larger accounts can perform a single daily scan. Like CloudFormation, IaC Generator is a regional service that scans resources in the selected region. Avoid wasted scans and unintended confusion by checking the selected region is correct before starting the scan!
In my account, IaC Generator found 209 resources in my main region in about two minutes.
I then ran a second scan in a different region to see what would happen. It found 71 resources, so a clear difference. Interestingly, resources from global services like S3 and IAM were included in both scans while regional services like Lambda and CloudWatch resources weren’t. So pay attention to the selected region!
With a successful scan, I can now make a template.
Template Generation
There are three steps to making an IaC Generator template:
Specify template details
Add scanned resources
Add related resources
Template Details
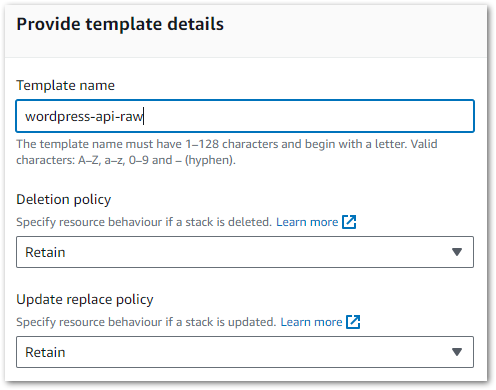
Firstly, the generator asks if it’s creating a new template or updating an existing one. Selecting the latter displays that region’s CloudFormation stacks, but I don’t have any yet so let’s move on.
These are important decisions, so let’s clarify what they mean and why they default to Retain.
The DeletionPolicy attribute controls what happens to resources when a stack is deleted. It has two options:
Delete: CloudFormation deletes the stack and the resources. Nothing is kept.
Retail: CloudFormation deletes the stack and keeps the resources and their data.
The UpdateReplacePolicy attribute controls what happens to a resource that must be changed during a stack update. For example, upgrading an EC2 instance or a Lambda function.
It has three options:
Delete: CloudFormation makes new resources and then deletes the old ones.
Retain: CloudFormation makes new resources and keeps the existing ones. The old resources are then removed from CloudFormation’s scope.
Snapshot: For resources that support snapshots like RDS and EBS, CloudFormation creates a snapshot for the resource before deleting it.
The Retain default for both policies ensures that no unintended resource deletions happen while using the generator. When using Retain, remember that CloudFormation-created resources cost the same as their manual counterparts and can get expensive if forgotten about!
The IaC Generator applies these attributes to every resource in the template. After creation, they can be changed for specific resources if needed.
Adding Resources
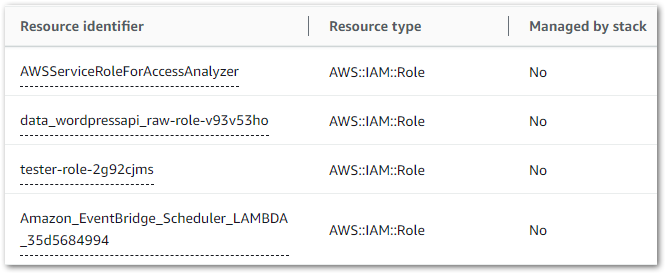
Next, IaC Generator shows the resources found in the most recent scan. For example:
This can be a big list, and can be filtered by:
Resource Type
Tag Key
Tag Value
Resource Identifier
So, filtering on Resource Type = bucket returns S3 buckets and S3 bucket policies, while Resource Identifier = rtb returns VPC route tables. Desired resources can then be selected, appearing in a list under the scan results.
Next, IaC Generator checks my selections and recommends related resources that enable service interactions or belong to the same workload. Here, it suggested two IAM roles for my Lambda function and EventBridge scheduler that I’d missed. This is great, as that would have caused big problems down the line!
Finally, IaC Generator summarises the selections and creates a CloudFormation template.
IaC Generator Outputs
In this section, I examine the template and notifications provided by IaC Generator following my hands-on.
Summary
After IaC Generator has created a template, three tabs are presented:
Template Definition: The IaC Generator template in YAML and JSON, with options to download it, copy it and import it to a CloudFormation stack.
Template Resources: A list of the template’s resource types, each resource’s CloudFormation Logical ID (which can be changed) and each resource’s status within the template. Resources can be added to the template and resynced if they’ve changed since the initial scan.
AWS CDK: A two-step process to generate a CDK application for the template using the cdk migrate command. This is out of scope for this post, but this is the generated Python command:
The full template comes in at 500 lines! So I’ll pull out some sections and take a closer look instead of going through the whole thing. Firstly, one of my SNS topics. I’ve highlighted the FIFO setting, subscription protocol and topic name:
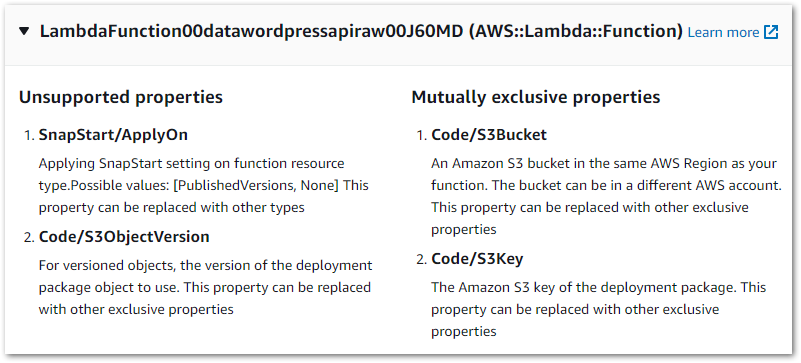
The IaC Generator cannot determine which set of exclusive properties was applied to the resource during creation. For example, you can provide the code for a AWS::Lambda::Function using one of these sets of properties.
Code/S3Bucket, Code/S3Key, and optionally Code/S3ObjectVersion
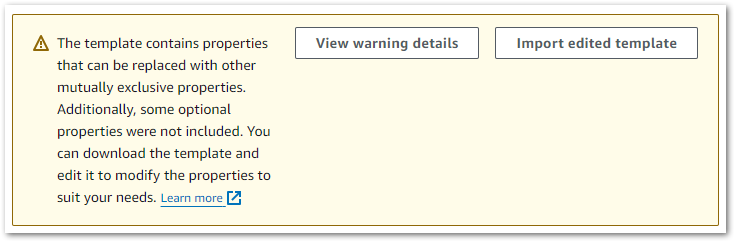
The generator doesn’t know how the function code was provided, and can’t guess. So these warnings are included by design to stop IaC Generator from using the wrong function code:
When a generated template contains AWS::Lambda::Function resources, then warnings are generated stating that Code/S3Bucket and Code/S3Key properties are identified as MUTUALLY_EXCLUSIVE_PROPERTIES. In addition, the Code/S3ObjectVersion property receives a UNSUPPORTED_PROPERTIES warning.
Those don’t look like any S3 resources in my account, so what are they? To begin to answer that question, let’s take a look at one of Bytescale’s example CloudFormation Lambda templates:
This is simple to break down, with a clear bucket name and object key. The big difference is the lack of Ref in the sample code block. So what’s it doing in my template?
CloudFormation’s Ref is an intrinsic function that returns the value of a specified parameter or resource. Here, both Ref functions point to CloudFormation Parameters defined earlier in the template:
YAML
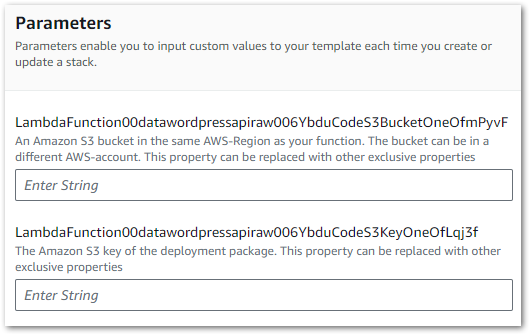
Parameters:LambdaFunction00datawordpressapiraw006YbduCodeS3KeyOneOfLqj3f:NoEcho: "true"Type: "String"Description: "The Amazon S3 key of the deployment package.\nThis property can\\ be replaced with other exclusive properties"LambdaFunction00datawordpressapiraw006YbduCodeS3BucketOneOfmPyvF:NoEcho: "true"Type: "String"Description: "An Amazon S3 bucket in the same AWS-Region as your function. The\\ bucket can be in a different AWS-account.\nThis property can be replaced with\\ other exclusive properties"
Now we’re getting somewhere! These parameters clearly reference an S3 key and an S3 bucket.
When this template is imported into a stack, CloudFormation will use these parameters to request the function code’s S3 location. The parameter values will then be passed to the Lambda code block when creating the function. The template can be manually updated with these values, but I’ll use the template as-is to see how the standard process unfolds.
This is a good time to talk about IaC Generator’s other limitations.
Limitations
CloudFormation has several operations, not all of which support every AWS resource. These operations are:
Drift detection: finding differences between a stack’s expected and actual configurations.
The AWS CloudFormation User Guide has a table of operations supported by resource types. This is a substantial table, so let’s focus on my template’s resources.
Firstly, there’s currently no IaC Generator support for the AWS::Lambda::EventInvokeConfig resource that handles Lambda Destinations. My template will deploy the Destination SNS topic, but will not configure the destination’s parameters.
Additionally, IaC Generator doesn’t currently support the AWS::SSM::Parameter resource. This is great from a security angle (no plain text credentials!) but adds an important manual step when using the stack.
Everything else is fully supported, so let’s try using the template.
Testing
In this section, I import the template from my IaC Generator Hands-On into a CloudFormation stack and see what happens.
CloudFormation Designer
A good way to check the template’s contents is to import it to CloudFormation Designer – an AWS tool for visually creating, viewing, and modifying CloudFormation templates.
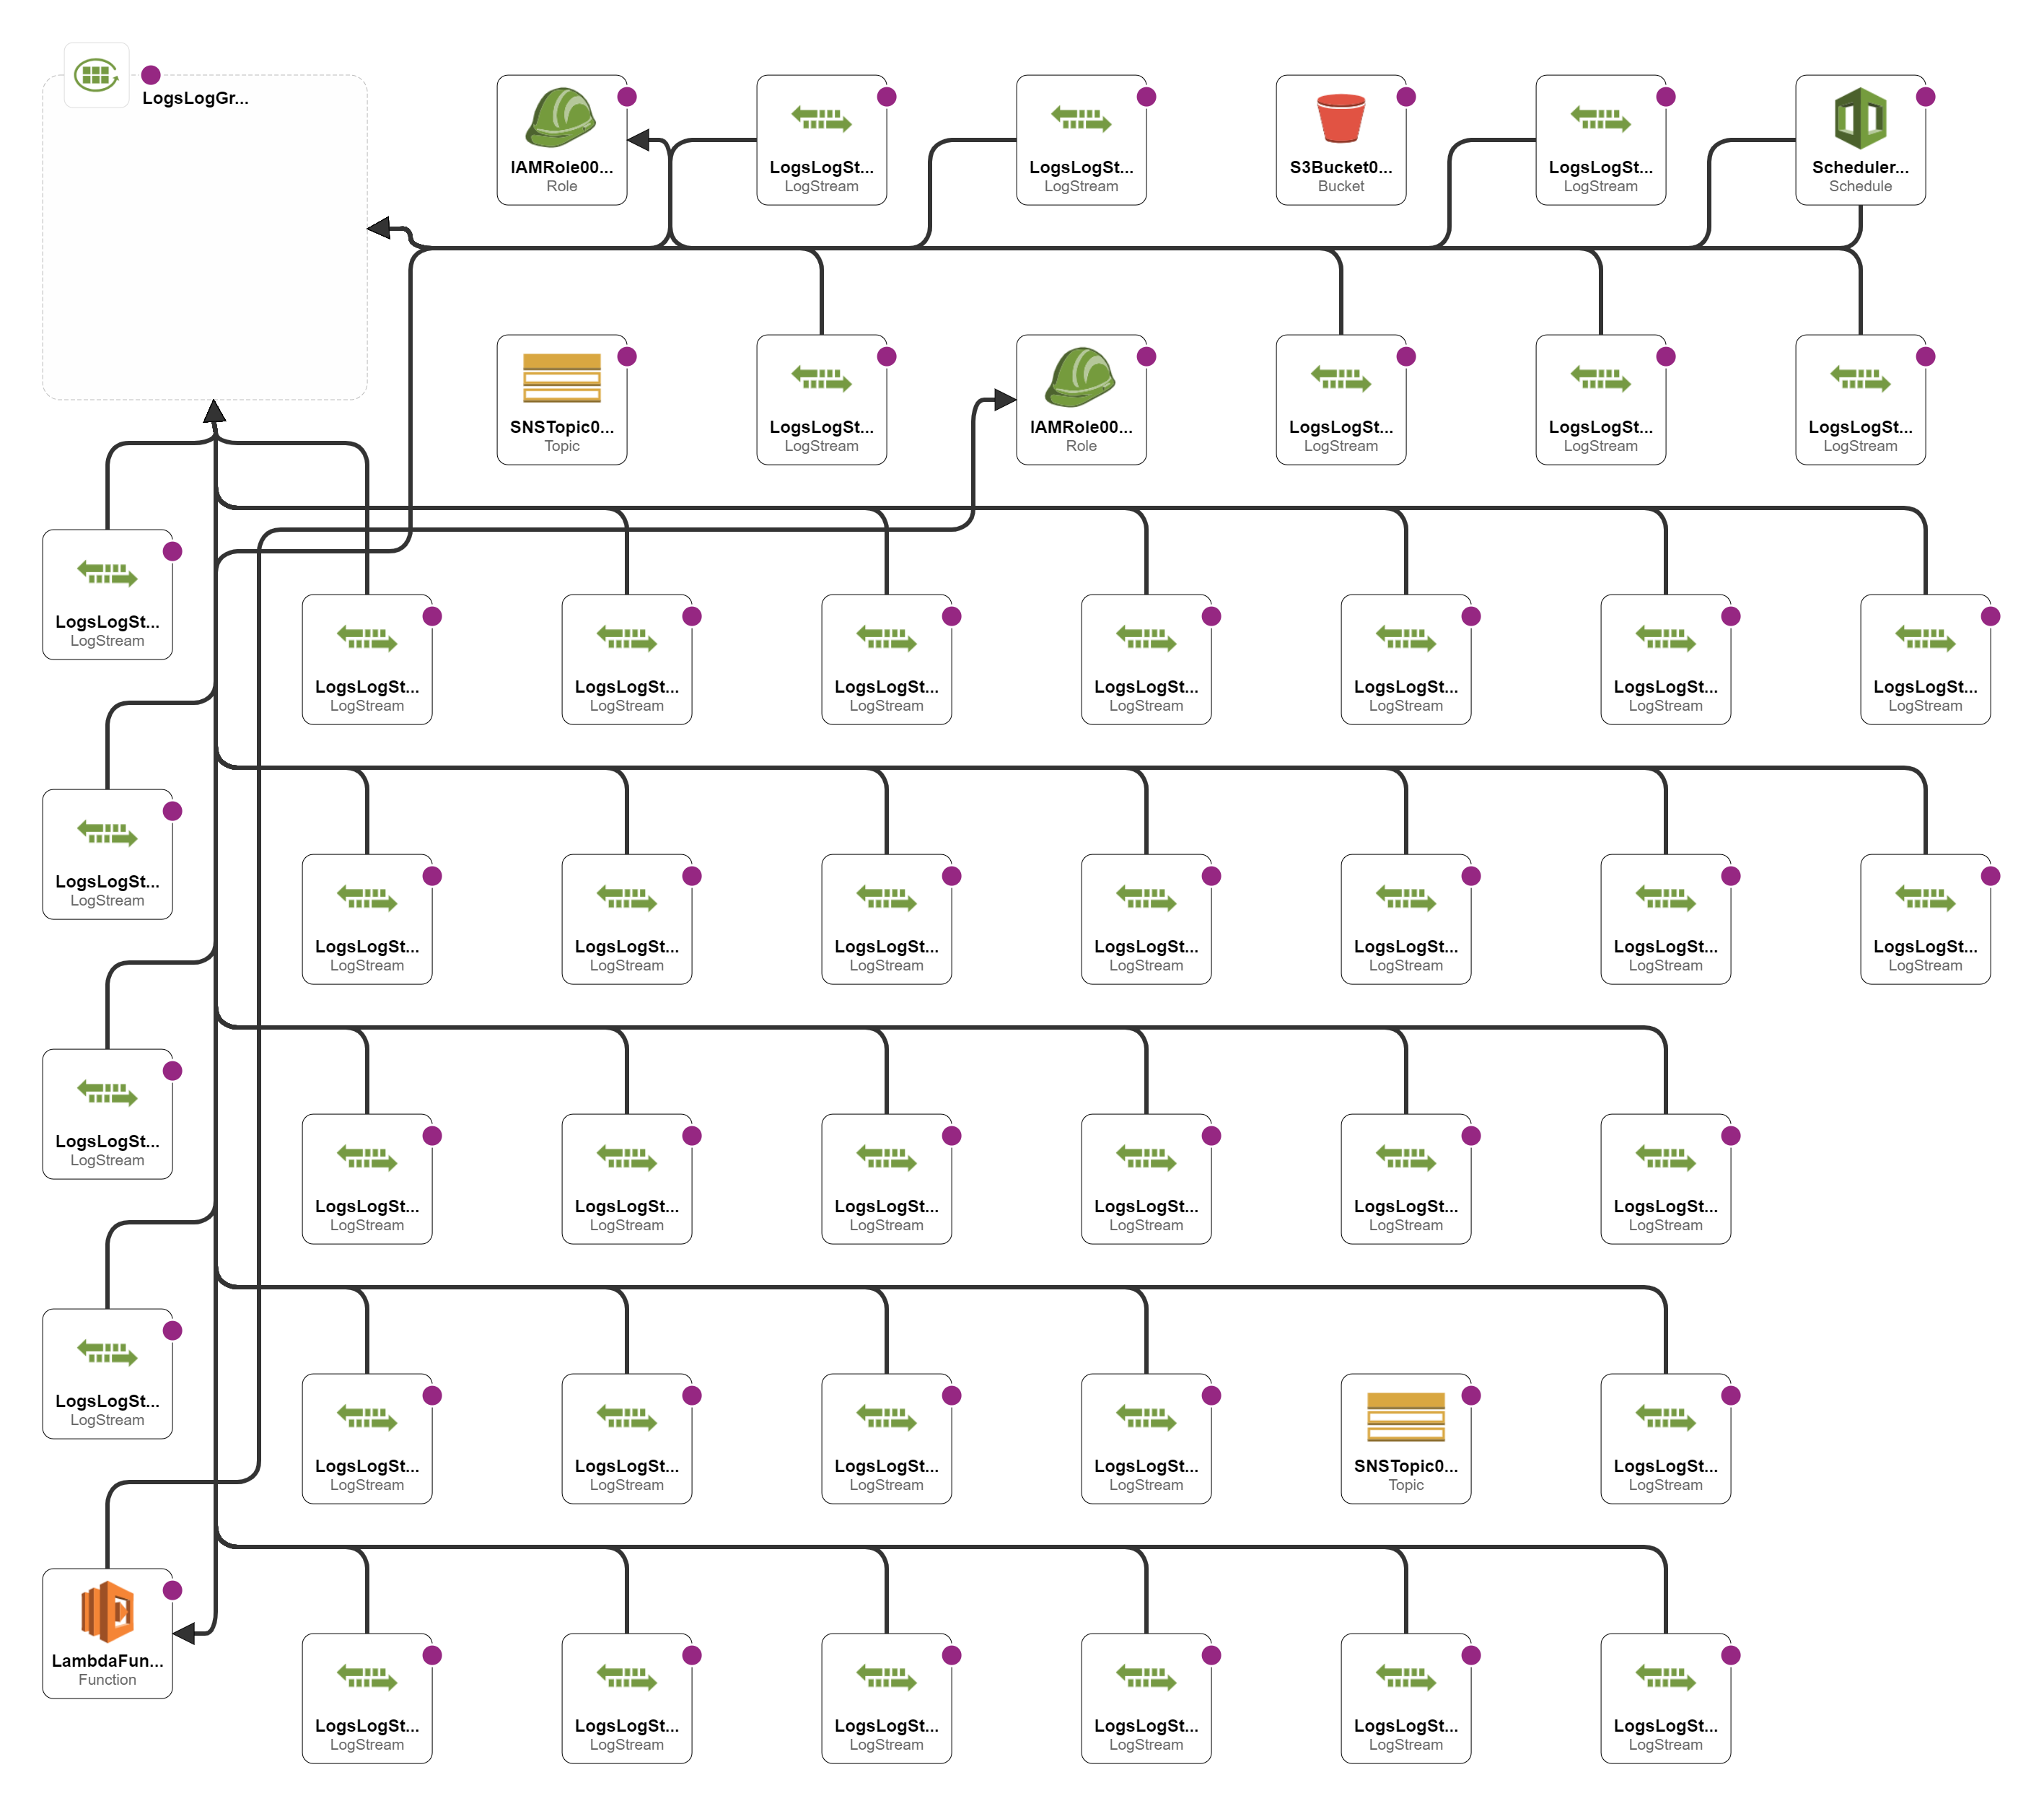
This is Designer’s first diagram using IaC Generator’s template:
Eek!
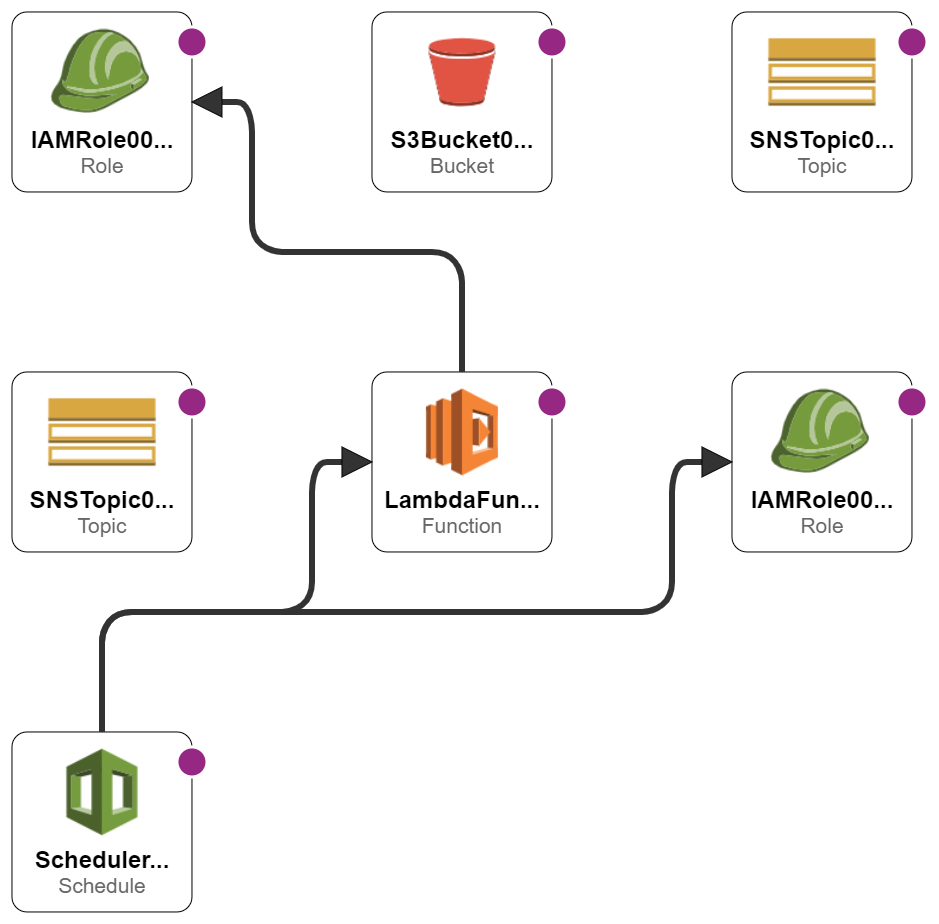
Here, Designer is visualising all the CloudWatch resources. It looks fine on a big screen but isn’t great here, so I made a second template with no CloudWatch resources and imported that:
Much clearer! My EventBridge schedule and Lambda function are mapped to their respective IAM roles, and the SNS and S3 resources are present. As discussed, no Parameter Store resources or SNS destinations appear because these are not currently supported.
Now, I can add the missing resources to the generated template myself. However, because I want to see how the standard template behaves in testing I’ll be using it as-is.
Stack Import
A stack import is the process of transforming a template into a CloudFormation Stack. The stack is then used to provision AWS resources.
Stack imports are triggered in the IaC Generator’s Template Definition tab. After choosing the stack’s name, the Lambda parameters are requested:
These values are then assigned to the Lambda code block’s S3Bucket and S3Key parameters.
Next, some basic admin. The stack needs an IAM role for all operations performed. IaC Generator then checks for any resource changes resulting from the stack’s creation. This is a completely new stack so this doesn’t apply.
With these details, CloudFormation starts creating the stack, which can then be deployed as usual.
Thoughts
So what do I think after my IaC Generator Hands-On? Well, there are some quality of life improvements that I think would make IaC Generator even more useful:
Direct Links To Scanned Resources
When browsing the scanned resources while making a template, I’d love to have direct links to the resources in the same way that I can see the EBS volumes attached to an EC2 instance and a Lambda function’s CloudWatch Log Stream.
While some resources have fairly friendly Resource Identifier names, others appear with names like aclassoc-0295235ac2e7c7e98 and rtb-0f28bd9a05e4ea696. Having a direct link to these resources from the selection screen would be massively helpful.
Simpler Errors
If IaC Generator is intended for people with little or no CloudFormation experience, then the Lambda and API Gateway warnings could be simpler.
I had some theoretical CloudFormation knowledge and have no qualms about reading documentation, so I got by. But users completely new to CloudFormation could easily see those warnings, assume they made a mistake and forget the whole thing.
Improved Reproducibility
When I deployed the template to my preferred region everything went fine. But when I tried to deploy it in a different AWS region it failed and threw CREATE_FAILED errors:
Resource handler returned message: "Resource of type 'AWS::SNS::Topic' with identifier 'data-lakehouse-raw' already exists." (RequestToken: e71fe163-af5e-bc59-4fd3-95dce19c9494, HandlerErrorCode: AlreadyExists)
Resource handler returned message: "Resource of type 'AWS::SNS::Topic' with identifier 'lambda-general-failure' already exists." (RequestToken: f6e9722f-0f01-8c54-353a-cf62f4f266f4, HandlerErrorCode: AlreadyExists)
For now, this can be resolved by using the generator’s template as a starting point for further templates. However, generating templates that can be immediately deployed in other regions would be very helpful.
Fewer Missing Resources
Finally, it would be good to see fewer missing resource types over time. Some of them will present AWS with some challenges, but hopefully others are just a matter of dev time.
For example, Lambda Destinations are already on the automated AWS SAM templates that can be generated from the Lambda console:
YAML
#***# indicates that sections have been removed.AWSTemplateFormatVersion: '2010-09-09'Transform: AWS::Serverless-2016-10-31Resources:datawordpressapiraw:Type: AWS::Serverless::FunctionProperties:#***#EventInvokeConfig:DestinationConfig:OnFailure:Destination: arn:aws:sns:eu-west-1:REDACTED:lambda-general-failureType: SNSMaximumEventAgeInSeconds: 21600MaximumRetryAttempts: 0#***#
Summary
In this post, I had a hands-on with AWS CloudFormation’s new IaC Generator feature. I think it’s really impressive! It makes CloudFormation more accessible than it was before, and I’m excited to see how it develops over time.
If this post has been useful, the button below has links for contact, socials, projects and sessions: