In this post, I document the journey of resurrecting a dusty old 2011 PC into a functional Kubernetes lab to prepare for my CKA exam.
Introduction
This year, I plan to take the Certified Kubernetes Administrator (CKA) exam. I’m familiar with tech certifications, having earned my first one in 2019. However, the CKA differs from these exams in that it is a performance-based test that requires completing multiple tasks from the command line with Kubernetes.
I’ve been using Mumshad Mannambeth’s Udemy course, and while it includes several labs I also want to get some extra practice. So I started looking into setting up a Kubernetes lab, and found that I already had access to several devices capable of running one! I have since successfully created my lab, and this post examines how I got there.
I’ll begin by explaining my decision to use the 2011 PC for my Kubernetes lab over other available options, as well as the repairs it needed to get going. Next, I’ll describe the process I followed to select a suitable operating system. Finally, I’ll outline the steps taken to test the PC and install the necessary lab components.
Hardware Selection
In this section, I explain why I chose the 2011 PC for my Kubernetes lab over other available options. While this may seem redundant given the blog title, I wanted to share my considerations and thought processes.
I considered three options:
- Raspberry Pi Cluster
- Amazon EC2 Instances
- A 2011 PC
Raspberry Pi Cluster
The Raspberry Pi is a compact single-board computer widely used for building low-power projects and clusters. It enables users to run Linux and explore different architectures, providing an efficient way to learn about distributed systems without the energy costs of traditional servers.
While the humble Pi may not be the most obvious choice for a Kubernetes lab, a Kubernetes Up & Running appendix covers building a Kubernetes cluster on Raspberry Pi. So it was worth considering!
Raspberry Pi Cluster Pros
- No Virtualisation Overhead: Running Kubernetes on bare-metal Raspberry Pis removes the need for a hypervisor, allowing all ARM processor cycles and RAM to be fully dedicated to the lab.
- True High Availability Testing: A Raspberry Pi cluster uses a “shared-nothing” architecture. Unplugging a node forces the cluster to demonstrate its real-time self-healing capabilities.
- Energy Efficiency: While an old PC draws 60W–100W, a 3-node Pi cluster runs on under 15W. This makes 24/7 operation significantly cheaper.
Raspberry Pi Cluster Cons
- High Capital Expense: A starter kit with nodes, reliable power supplies and network gear easily exceeds £100 in 2026. I already own a Pi 4, but I’d still need everything else.
- Component Rigidity: Unlike a desktop PC with swappable RAM, Pi memory is soldered in place. Increasing a Pi’s RAM requires a complete hardware refresh, which limits the lab’s long-term lifecycle.
- Storage Fragility: Constant logging in Kubernetes can degrade standard microSD cards within months. Reliable operation usually requires booting from USB SSDs, which increases both cost and physical clutter.
EC2 Instances
Amazon EC2 is a standard service for on-demand virtual servers that lets users rent computing capacity in AWS data centres. It operates on a “pay-as-you-go” model, allowing users to launch and terminate instances with the required CPU and RAM as needed.
Note that Amazon also provides Elastic Kubernetes Service (EKS). However, EKS is a managed service and I want to practise the manual Kubernetes setup process.
EC2 Pros:
- Production Parity: EC2 offers a realistic environment with the same features and specs as a professional enterprise deployment.
- On-Demand Scalability: Complex node architectures can be quickly created or deleted, enabling the testing of scenarios that would take hours to set up on physical hardware.
- No Hardware Maintenance: The cloud provider manages the entire bare-metal abstraction. Users are not responsible for managing the hypervisor, physical cooling or local network switching.
EC2 Cons:
- Ongoing Costs: Even small
t3.microinstances accumulate costs quickly. A three-node lab running 24/7 would eventually cost more than the other options. - Reduced Learning Opportunities: AWS manages most of the backend networking. This limits opportunities to learn about topics such as network bridges, VLANs or physical NIC teaming.
- Internet Dependency: The lab’s reliability depends on my home internet connection. If it drops, the entire cluster is unreachable.
A 2011 PC
The time has come. Meet the HP Pavilion p6-2022uk:

This BEAST originally shipped in 2011 with specs including:
- Processor: Intel Core i3-2120 (3.3 GHz, Sandy Bridge)
- Memory: 4 GB DDR3-SDRAM (1333 MHz), 2 slots
- Storage: 1 TB HDD (typically 7200 RPM)
- Operating System: Windows 7 Home Premium 64-bit

On the back are four of the PC’s six USB 2.0 ports (none of your fancy USB 3.0 here), three audio ports, VGA and DVI outputs (no HDMI) and the Ethernet port:

So how does it stack up?
HP Pavilion Pros:
- No Capital Expense: Turning existing hardware into a learning tool prevents e-waste and incurs no cost.
- Full Hardware Control: The PC provides full access to the hardware BIOS, the physical network stack and the hypervisor kernel. This offers an in-depth understanding of how the lab works.
- Expandability: The PC allows for modular upgrades, making it easy to add more RAM, replace a hard drive or install new network and graphics cards. In contrast, these upgrades can be challenging or even impossible with a cluster of Raspberry Pis.
HP Pavilion Cons:
- Power Inefficiency: The PC must stay on while the lab operates. This will use more power than the other options, and the power supply, which is from 2011, may be less efficient than modern ones.
- Legacy Components: The ageing processor, RAM, and ports mean that using the PC will not offer as smooth an experience as a group of Raspberry Pis or EC2 instances. It will lack speed, portability, and hardware redundancy.
- Repairs Needed: So this leans into why I have this PC in the first place. It do be poorly!
Its biggest problem is the hard drive, which currently boots to an imminent failure warning before failing entirely:

The WiFi card is also unreliable. This wasn’t a major issue in the past because it was positioned next to the router and had a constant Ethernet connection. However, this limited its placement options, and it poses a problem now.
Hardware Decision
So why, with all these negatives, did the PC win? It came down to control, simplicity and cost.
Infrastructure Control
With a single physical device, I have complete control over every layer of the stack. I can customise the storage, upgrade the RAM or change the internals whenever necessary. This is impossible with a Pi cluster and limited with EC2 instances.
Minimal Operational Complexity
A PC simplifies everything by combining all components into one device, eliminating the need to manage multiple setups. This way, I can focus on learning Kubernetes instead of juggling cables and managing security groups.
Cost Efficiency
Using a PC lets me avoid the high capital expenditure costs of a Raspberry Pi cluster or the ongoing operational expenses of EC2. Instead, I can invest in repairs and upgrades for the PC and eventually replace it when it fails.
Next, let’s get onto those repairs!
Repairing The PC
If this 2011 PC is going to run Kubernetes, it needs some repairs! In this section, I’ll triage the PC and attempt to fix its issues. For clarity, those issues are prioritised in the following order:
- Dead hard drive
- Low RAM
- Questionable WiFi card
Hard Drive Replacement
Addressing the biggest problem first, that knackered hard drive must go! While fixing hard drives isn’t impossible, it needs specialised skills and is labour-intensive. And in this case, it’s not worth the effort. There’s nothing valuable on the drive, and due to its age it could fail at any moment. That makes this a replacement job!
Thankfully, I made this decision a while ago – well before the current hard drive cost spike! I realised I needed neither an SSD’s speed nor a terabyte of storage. So I bought a Seagate Barracuda ESA-3502 500 GB HDD as it reviewed well and came in at a bargain price of £19.99 (as opposed to the current £35.99 asking price!)
RAM Upgrade
Next, let’s talk about RAM. Although Kubernetes can operate with just 4GB of memory, the virtual machines and the PC also require some memory to function properly. Having such a low memory limit will lead to various problems. The VMs may become too slow, and the PC itself might encounter performance issues.
Over the years, I’ve owned many computers. And like many people in the IT profession, I have various cables, heat sinks, and parts salvaged from computers that were destined for the scrap heap!
Among these items, I found two 8GB DDR3 RAM sticks which I swapped for the PC’s two 2GB sticks. Now this may not work, as the PC’s specs specify that each slot’s maximum memory capacity is 4GB. No harm in trying though, eh?
Internet Access
Finally, let’s discuss the WiFi situation. The WiFi card is already known to have issues, and the PC is on a different floor from my home router so I can’t use Ethernet. This won’t affect the operating system installation, as both the USB ports and the optical drive work. But I won’t then be able to download any updates, firmware or the various Kubernetes components.
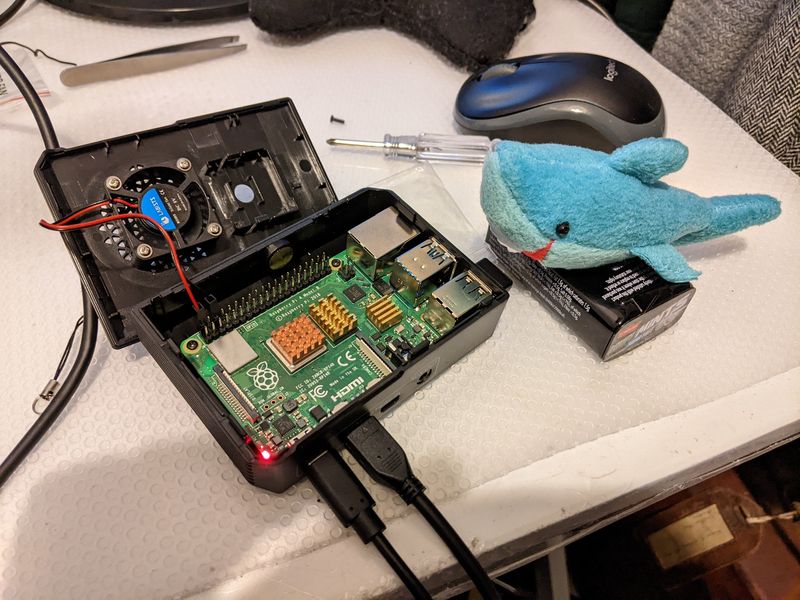
Enter my Raspberry Pi 4! This is fully capable of connecting to my WiFi and sharing that connection with my PC. It acts as a NAT (Network Address Translation) router, managing the communication between its wireless interface (wlan0) and its wired Ethernet interface (eth0). This setup is similar to how a home router shares a single public IP address among multiple devices.
Here is what happens at the network layer:
- The Pi connects to the WiFi network via
wlan0and receives an IP address from the router (e.g. 192.168.1.12). The router sees the Pi as another wireless client. - The Pi assigns itself a static IP on
eth0in a separate subnet (e.g. 10.0.0.1) and runs a small DHCP server on that interface viadnsmasq. The PC will use this network. - The Pi and PC’s Ethernet ports are then wired together.
- When the PC sends traffic intended for the internet, it is routed to the Raspberry Pi, which serves as its default gateway.
- The Raspberry Pi modifies the packet’s source IP address to match its own
wlan0address before forwarding it upstream. This process is known as NAT Masquerading. - Incoming replies are received by the Raspberry Pi, which translates the IP addresses back to their original format and then forwards them to the PC.

That’s everything! The PC should now boot. But boot what?
OS Selection
As I’m replacing the PC’s hard drive, I can also upgrade the operating system. Since I plan to run virtual machines on the 2011 PC for my Kubernetes nodes, the host OS will act as a hypervisor.
It will handle three critical tasks:
- Resource Management: Allocating CPU and RAM for each VM.
- Storage: Managing how the VMs access the physical hard drive.
- Networking: Creating a bridge so VMs can talk to each other and the internet.
Keep in mind that the OS selections for the 2011 PC and for the Kubernetes VMs are independent choices and needn’t be the same. For instance, Windows can run WSL, and a Debian host can run Ubuntu VMs. The decision on the VM OS will be made after the host OS has been determined.
Let’s start with the traditional players. Which, it turns out, aren’t all that suitable…
Windows
Windows is the most widely used desktop OS and provides a professional-grade virtualisation platform through Hyper-V. While it is a strong option for running enterprise mixed-OS environments, its architecture is poorly suited for a dedicated Linux-based lab on legacy hardware.
- Tooling Incompatibility: The standard open-source orchestration stack, including
virt-manager,cloud-init, andvirsh, is designed for the Linux/KVM ecosystem. Managing a Windows host on the 2011 PC needs a distinct set of PowerShell tools, adding unhelpful complexity to the learning process. - Resource Inefficiency: A Windows host uses a significant amount of RAM and CPU cycles to operate its GUI and background telemetry. On a dual-core i3-2120 with 4GB of RAM, this operational overhead leaves less room for the guest VMs.
- Storage Latency: The NTFS file system, along with Windows’ aggressive background indexing and telemetry, creates significant disk contention. This latency becomes more pronounced on older mechanical drives, leading to slower boot times and reduced responsiveness for virtual disk images.
macOS
macOS is well known for providing an exceptional developer experience and is the primary OS used by many in the DevOps community. However, its kernel is optimised for use as an interactive workstation rather than as a persistent, headless hypervisor host.
- Kernel Abstraction: macOS does not have a built-in hypervisor compatible with Linux, so tools like Docker Desktop or Lima must run a helper VM to create a Linux environment. This results in nested virtualisation, where one VM runs inside another, complicating networking and reducing performance.
- Architecture Mismatch: Most production Kubernetes clusters are designed for amd64 architecture. Running amd64 nodes on an Apple Silicon Mac involves using QEMU for emulation. This method reduces performance and can introduce subtle behavioural bugs in low-level networking and storage drivers that don’t appear on native hardware.
- Hardware Inflexibility: macOS is optimised for interactive power management. When used as a persistent, headless server, the OS often deprioritises background tasks or enters sleep states. This can disrupt the high-availability heartbeats needed by a Kubernetes cluster.
Linux
Linux is the industry standard for virtualisation. KVM (Kernel-based Virtual Machine) is built directly into the Linux kernel, making virtualisation a primary feature rather than an additional component. Linux also spotlights the key components used by both hypervisors and Kubernetes: namespaces, cgroups, and network bridges, without the licensing issues of proprietary operating systems.
Linux has many distributions, each with its own package manager, default software and design philosophy. I considered the following Linux distros:
Alpine Linux
Alpine is designed for minimal-footprint environments where reducing attack surface and efficient resource use is crucial. It serves as the base image for many public Docker containers and is employed in embedded systems and security-focused infrastructure, where any unnecessary package can pose a risk.
Alpine Pros
- Extreme Resource Efficiency: Alpine generally uses 50-80 MB of RAM while idle. This optimisation reduces host-level overhead on older hardware, maximising resources for guest VMs.
- Reduced Attack Surface: Alpine minimises potential attack vectors by removing unnecessary binaries and packages.
- Lightweight Init System: It uses
OpenRCinstead ofsystemd, resulting in quicker boot sequences and service management through transparent shell scripts.
Alpine Cons
- GNU Toolchain Friction: Alpine replaces the standard GNU utilities with BusyBox. However, resources such as the KVM documentation assume GNU, so commands must be translated for BusyBox.
- Standard Library Divergence: The use of
musl libcinstead ofglibccan lead to silent failures and unexpected problems with precompiled binaries or certain kernel modules. - Manual Configuration: In Alpine, certain administrative tasks that are automated in other distributions, such as kernel module persistence and complex network bridging, require manual intervention.
Debian Linux
Debian is designed for stable, long-term server infrastructure, prioritising predictability over having the latest software. It serves as the foundation for several distros, including Ubuntu and Raspberry Pi OS, and has built a reputation based on a careful release process that emphasises reliability.
Debian Pros
- Predictable Performance: A minimal Debian installation uses less than 200MB of RAM. Its lack of unnecessary background processes reduces disk I/O contention on mechanical hard drives, which is vital when multiple VMs are swapping.
- Streamlined Architecture: Debian avoids using the
snapddaemon and its loop-device overhead. This method keeps the host’s kernel routing table and mount points organised, simplifying the troubleshooting of VM network bridges. - Universal Binary Compatibility: Debian uses the standard
glibclibrary. This compatibility allows enterprise virtualisation tools and guest agents to run natively without extra layers. As a result, Debian can use Ubuntu’s software ecosystem while minimising the associated service overhead.
Debian Cons
- Manual Installation: Debian’s installer requires careful decisions about partitioning and mirror selection, as misconfigurations can cause issues.
- Firmware Hurdles: Although hardware detection has improved, proprietary firmware for older network and WiFi cards may still need to be manually included from the “non-free” repository during initial setup (although from Debian 12 onwards this is less of a problem than it used to be).
- Conservative Packaging: Debian prioritises stability over the latest software versions. Accessing the latest
QEMUorlibvirtfeatures occasionally require the use of thebackportsrepository.
Ubuntu Linux
Ubuntu is the most popular Linux distribution used in cloud and server environments. It is often the default choice referenced in DevOps and Kubernetes documentation. Commercially supported by Canonical, Ubuntu has a regular release schedule and offers long-term support versions suitable for both enterprise and home users.
Ubuntu Pros
- Native Documentation Sync: Most KVM and
libvirtguides are written with Ubuntu in mind. File paths and package names at the host level will closely align with the most common reference materials. - Extensive Driver Support: Ubuntu’s Hardware Enablement (HWE) stack includes proprietary drivers by default. This guarantees that niche hardware components on older PCs will work right away, eliminating the need for manual troubleshooting.
- Commercial Maturity: Ubuntu provides a regular release schedule and strong community support for troubleshooting complex virtualisation scenarios such as GPU passthrough and nested virtualisation.
Ubuntu Cons
- Service Overhead: The inclusion of
snapd,cloud-initand automated update daemons result in an idle footprint of 300–400 MB. On hardware with low RAM, this consumes vital memory before a single VM starts. - Network Abstraction: Ubuntu uses the Netplan abstraction for network configuration. This adds a layer of YAML complexity as opposed to the direct control of the traditional
/etc/network/interfacesfile. - I/O Latency: Background services like
unattended-upgradescan trigger sudden changes in disk activity. On older mechanical drives, this can cause guest VMs to experience latency spikes during high-load operations.
OS Decision
For my 2011 PC Kubernetes lab, Debian is the optimal choice. While Alpine is leaner and Ubuntu is more automated, Debian provides the best performance-to-stability ratio for a 2011-era PC acting as a VM host.
CPU and I/O Contention
Debian offers a more stable environment with fewer background processes compared to Ubuntu. This is particularly useful for a PC with an Intel i3-2120 dual-core processor, as it reduces the number of running daemons and minimises disk activity. This will improve VM performance and Kubernetes cluster stability.
Fastest Success Path
Debian occupies a sweet spot between Ubuntu’s excess and Alpine’s frugality, letting me set up a Kubernetes lab quickly without making significant changes to the OS.
Hypervisor Consistency
A hypervisor host functions best on a reliable foundation. Debian’s stable release offers fixed package versions and a cautious update policy, ensuring that the KVM toolchain, network bridge drivers and configurations stay consistent. This stability prevents version drift that could disrupt networking or storage for the guest VMs.
Testing Old PC
In this section, I conduct a smoke test of the 2011 PC and Debian to check that my repairs were successful and that the system is stable enough for virtualisation and Kubernetes.
Hard Drive Test
The first test is the simplest. When activated, the PC immediately detects the replacement hard drive. It then uses my Debian USB to run the installer, progressing through each stage without issue.
I’m installing Debian 13 – the most recent version, released on 9 August 2025. For those curious, this video shows a typical Debian 13 installation:
I mentioned earlier that the installer requires some careful decisions. One of these is the choice of Debian desktop environment:

There are several choices here that control how minimal or feature-rich the desktop is. Many guides recommended the bare minimum SSH server to maximise the resources available for Kubernetes. I chose to install Xfce – a lightweight GUI designed for older or limited-resource hardware. This will let me see the various Debian backend files and folders in a familiar Windows-like environment, helping me understand Kubernetes’ inner workings.
This video explores several Debian desktop environments, including Xfce:
RAM Test
Next, let’s assess the RAM. This was partially verified during the hard drive test, as faulty RAM would have either caused issues during the Debian installation or prevented the PC from booting outright. But how much RAM is actually available?
With a successful Debian install, I can run free -h to find out! This shows 15GB memory with 14GB free:

This is…interesting given the PC’s stated maximum of 8GB! Indeed, running dmidecode to query the BIOS states that the maximum capacity is 8GB:

Having researched, there are two main reasons for this:
- Outdated BIOS Info: The motherboard’s DMI table, which
dmidecodeuses for information, was created when 4GB sticks were the known maximum limit, and HP never updated it. - Ambiguous Definition: Sometimes “Max Capacity” refers to the per-slot maximum rather than the entire board‘s total. And there are two devices (slots), so 2x 8GB is 16GB.
In any case, free -h can be trusted so I do indeed have 16GB RAM!
I can also use lscpu to verify how many cores the PC has. The Intel Core i3-2120 is a dual-core processor with two physical cores. It features Intel Hyper-Threading, allowing each core to present two threads (logical processors) to the OS, resulting in a total of four threads.

Internet Test
Finally, let’s test the internet. Running ping -c 4 8.8.8.8 in the terminal returned packets successfully, and running sudo apt update fetched the latest package list:

With everything set up, there’s just one step remaining to convert my 2011 PC into a Kubernetes lab.
Configure Virtualisation
In this section, I outline the steps taken to install the software needed for the 2011 PC to function as a hypervisor in my Kubernetes lab. Please note that I do not claim this to be the definitive or best approach; it simply reflects my process for getting everything up and running on this occasion.
Installing Libraries
It’s now time to equip Debian with the necessary tools for virtualisation. This resulted in a fairly large install command, with each component contributing to my lab’s stability and manageability.
sudo apt install -y \
  qemu-kvm \
  bridge-utils \
  libvirt-daemon-system \
  libvirt-clients \
  virtinst \
  libosinfo-bin \
  virt-manager \
virt-viewerSo, what is all this actually doing? Let’s examine in stages.
Core Components
qemu-kvm: This forms the core of the entire system. KVM is a Linux kernel module that lets a CPU run VMs at speeds nearly matching those of physical hardware. QEMU manages the rest of the hardware emulation, providing the virtual motherboard, disk controllers and network cards that the guest OS recognises as genuine. Together, these components turn a PC into a platform capable of hosting multiple VMs.
bridge-utils: While VMs are isolated by default, bridge-utils creates a virtual switch that links them directly to a physical network. This is crucial for a Kubernetes lab, as it allows each node to obtain its own IP address and route traffic through the Raspberry Pi bridge. By using the host’s Ethernet connection in this way, the VMs gain the stable internet access required for cluster orchestration and updates.
Lifecycle & Control
libvirt-daemon-system: This package operates as a daemon responsible for managing VM lifecycles. It monitors active nodes, controls startup and shutdown processes, and ensures that a VM crash does not impact the entire system.
libvirt-clients: This provides the command-line tools needed to interact with libvirt-daemon-system, most notably including virsh – an industry-standard utility for managing VMs via the terminal. It can check statuses, modify configurations and reboot nodes from the terminal.
Provisioning & Optimisation
virtinst: This package yields virt-install, a command-line tool for creating VMs. Instead of going through a wizard multiple times, one command now specifies the CPU, RAM, and disk for multiple nodes. This makes setting up Kubernetes nodes quick and repeatable.
libosinfo-bin: Virtualisation works best when the host has detailed knowledge of the guest OS. This tool serves as a database that guides the hypervisor in using appropriate high-performance drivers for each VM. This technique allows the main CPU to conserve its cycles by reducing reliance on inefficient hardware emulation.
Monitoring & Troubleshooting
virt-manager: Although the primary goal is to manage the VMs through the terminal, I also want a GUI as I familiarise myself with the system. Virt-manager offers a graphical interface to monitor CPU and RAM usage in real time.
virt-viewer: If a VM fails to boot or loses its network connection, SSH access is impossible. This package opens a window that displays the VM’s console, allowing users to troubleshoot the boot process or fix a broken config file as if accessing it directly.
Testing Virtualisation
Having installed everything, I now need to test that the hypervisor works. On Debian, installing the packages doesn’t always mean the services are active and ready to run. So firstly I need to start the virtualisation daemon manually:
sudo systemctl enable --now libvirtdAnd then check virtualisation is running:
sudo systemctl status libvirtd --no-pagerIt should show a green active (running) status. But…uh oh.

This error means virtualisation isn’t enabled. And that means a trip to the PC’s BIOS settings!

With VTx enabled and a reboot later, the libvirtd service is now active:

Running kvm-ok (installed via cpu-checker)also shows the PC can now host hardware-accelerated KVM virtual machines. I can now run virt-manager to load the GUI:

This loads the Virtual Machine Manager, from which I can create and interact with my VMs via a GUI:

My 2011 PC can now spin up some Kubernetes nodes!
In terms of next steps, I’ll use the Kubernetes documentation to turn the 2011 PC into a multi-node cluster. The CKA is open-book, and getting familiar with the documentation will be a massive help during the exam!
Summary
In this post, I documented the journey of resurrecting a dusty old 2011 PC into a functional Kubernetes lab to prepare for my CKA exam.
This experience was a nice blend of familiar and new. While I’ve worked extensively with Linux, I’ve not gone into the weeds with various distros before. Nor have I built my own NAT router! Ultimately, this was a fun and engaging project and I’m looking forward to kicking the tyres of my new lab!
Like this post? Click the button below for links to contact, socials, projects and sessions:
Thanks for reading ~~^~~