Categories
Data & Analytics

Building A Basic Amazon Bedrock Structured Data Knowledge Base

In this post, I create a structured data knowledge base using Amazon Bedrock and test it by allowing it to query a database directly. Here’s what worked, what didn’t, and what it cost.

Introduction

In my last post, I built an unstructured Bedrock knowledge base using an S3-backed vector store. I now want to see how Bedrock behaves when it can use structured, relational data instead.

2025 12 25 KBCreate

A Bedrock structured knowledge base doesn’t use embeddings or vector search. Instead, it relies on the database schema. Bedrock generates SQL queries from natural language prompts, executes them directly against the data source and then formats the results into a user response.

While researching November’s post, I checked the query engine options for a Bedrock structured data knowledge base out of curiosity. I was greeted by a choice of…Redshift:

2025 12 25 KBQueryEngine

So fair enough – Redshift it is!

In this post, I will first load curated Parquet data into Redshift Serverless via S3. Next, I’ll create a Bedrock structured data knowledge base and synchronise it with my data.

Then I’ll pose increasingly challenging questions to the knowledge base, ranging from simple counts to complex aggregations. I’ll assess Bedrock’s strengths, analyse any misconceptions, and examine how prompt phrasing can affect results. Finally, I’ll review the costs associated with both Bedrock and Redshift.

To manage expectations, this post is essentially a POC. As such, the following are out of scope:

  • Benchmarking SQL or model performance.
  • Evaluating general model accuracy.
  • Production hardening.

Now, let’s get some data into AWS.

Data Preparation

In this section, I’ll create a minimal data pipeline using Parquet, S3 and Redshift Serverless.

Dataset Context

Let’s begin by talking about the data.

The data is sourced from my personal iTunes library and represents a snapshot of track-level metadata at a specific time. Each row corresponds to a single track, with columns capturing both standard attributes and user events.

Some columns mentioned later should be explicitly defined:

  • mtg_artist – The artist associated with the track.
  • mtg_publisher – The record label or publisher associated with the track.
  • my_rating – A personal track rating assigned in iTunes, on a fixed numeric scale.
  • plays – The total number of times each track was played on iTunes at the time of the snapshot.

File Creation

This process starts by creating a Parquet file. Parquet has been an industry standard for a while now, has many benefits and is ideal for this use case.

Now – full disclosure: this process is currently a bit hacky and uses an ad-hoc local Python script. I will write a proper ETL process as part of Project Wolfie. For now, it’s a combination of pandas .join and .to_parquet functions.

As for the data itself, I did mention it briefly in my February 2025 and May 2025 posts, but admittedly not in much depth. Project Wolfie’s Roadmap does include data dictionaries for all data sources, so they will exist – they just don’t currently. That said, the absence of data dictionaries won’t significantly impact this post, as my main focus is on how the Bedrock knowledge base interacts with the structured data.

S3 Setup

Next, let’s create an S3 bucket. I’ve created a temporary new bedrock-test general-purpose bucket for this post with default config. I then created an iTunesTest folder and uploaded my curated_data.parquet file. The names of the folders and buckets aren’t mega important here; what matters most is knowing the S3 path, as I’ll need it soon.

With the S3 bucket taken care of, it’s time to sort out Redshift. But which Redshift?

Redshift Provisioned Vs Redshift Serverless

There are currently two Redshift offerings, each with its own implementation.

Redshift Provisioned is the original deployment model, in which users create and manage a fixed-size cluster with specific node types. Capacity is chosen upfront, and the cluster is always available.

Redshift Provisioned is ideal for steady workloads that need consistent performance and precise control. However, it requires capacity planning and incurs charges even when not in use, making it less suitable for small or irregular workloads.

Redshift Serverless removes the need for cluster management by automatically adjusting compute capacity in response to demand. It mostly behaves like a standard Redshift endpoint, while AWS oversees the underlying infrastructure.

Redshift Serverless is ideal for low-volume or infrequent workloads, as you only pay for the compute power you consume and don’t need to manage capacity. However, it offers less control than provisioned clusters, and costs may exceed those of provisioned clusters if usage goes beyond a certain threshold.

Here, I’m using Redshift Serverless because:

  • Intermittent Workload: The data will be queried infrequently, so an always-on cluster is unnecessary.
  • Operational Simplicity: I want to focus on the AI POC, not on managing and sizing infrastructure.
  • Free Trial: Redshift Serverless offers a free trial for new users. It’d be rude not to…

Decision made. Next, let’s configure Redshift Serverless.

Redshift Serverless Setup

One of Redshift’s Serverless perks is its simple setup. Instead of explaining this myself, I’ll refer to two AWS videos. The first focuses mainly on the settings:

And the second explores Redshift’s Query Editor:

Here, I use the defaults again. I end up with a workgroup for controlling resources, scaling and execution prioritisation, and a namespace for holding tables, workgroups, and other database resources:

2025 12 25 RedshiftCreationDec25

Next, I need to put my Parquet data into a Redshift table. I’ll be using Redshift’s COPY command for this, but as the target table must already exist in the database, I need to write a Data Definition Language (DDL) command first.

To make the process as painless as possible, I write a quick pandas Python script to get the curated_data.parquet file schema:

Python
import pandas as pd

# Use .read_parquet to capture the data in a DataFrame
df = pd.read_parquet("curated_data.parquet")

# Use .dtypes to get the schema
print(df.dtypes)
Plaintext
Name object
Artist object
Album object
Work object
Genre object
Size int64
Time int64
...

And then pass the output to Amazon Q Developer to write a DDL statement for Redshift:

Convert this Parquet schema into a Redshift DDL statement:

Name object
Artist object
Album object
Work object
Genre object
Size int64
Time int64

…

Plaintext
Here's the Redshift DDL statement for your Parquet schema:

CREATE TABLE itunes_data(
    Name VARCHAR(500),
    Artist VARCHAR(500),
    Album VARCHAR(500),
    Work VARCHAR(500),
    Genre VARCHAR(100),
    Size BIGINT,
    Time BIGINT
    ...

Key mappings:

int32 → INTEGER
int64 → BIGINT
float64 → DOUBLE PRECISION
datetime64 → TIMESTAMP
object → VARCHAR(500) (adjust size as needed for your data)

I then run this script in Redshift to create an empty itunes_data table. COPY now has everything it needs to put the data into Redshift:

SQL
COPY dev.public.itunes_data
FROM 's3://bedrock-test/iTunesTest/curated_data.parquet'
IAM_ROLE 'arn:aws:iam::XXXXXXXXXX:role/service-role/AmazonRedshift-CommandsAccessRole-20251225T125455'
PARQUET

In this command:

  • COPY is the name of the target Redshift table.
  • FROM is the path to the S3 objects containing my data.
  • IAM_ROLE is the method the cluster uses to authenticate with, in this case, S3. This role was created during the Redshift Serverless default setup process.
  • PARQUET tells Redshift what format the data is in.

Full documentation is at the COPY from Amazon S3 page. The end result is a Redshift table containing the Parquet data:

2026 01 16 22 19 03 ReshiftResults

I have now prepared my data. Now I can start on the knowledge base!

Knowledge Base Build

In this section, I’ll build a Bedrock structured data knowledge base. Firstly, I’ll set up my query engine and permissions. Next, I’ll create a Bedrock knowledge base and connect it to my Redshift structured data store. Finally, I’ll synchronise the Rdshift structured data store with the Bedrock knowledge base to enable querying.

Knowledge Base Setup

Configuring a Bedrock structured data knowledge base starts out very similarly to my recent unstructured one, albeit with one noticeable difference at the start:

Selecting a structured knowledge base.

This leads to the Query Engine selection screen shown earlier. After selecting Redshift and either creating or selecting an IAM service role for Bedrock, I must then configure the connection options for my chosen Redshift offering:

2025 12 25 KBQueryEngineConnection

The next step identifies where the structured data is stored. In this case, my itunes_data table is located in the dev database’s pubic schema, so I select dev from the database list:

2025 12 25 KBQueryEngineStorageRS

I must now give authentication information to connect to my Redshift database. I can choose between the IAM role created in the previous step and AWS Secrets Manager credentials for authentication.

With this completed, the knowledge base has been created. The next step is the synchronisation process.

Data Store Sync

Currently, Bedrock has visibility into the schema but not into the data itself. As with an unstructured data knowledge base, I must synchronise the Redshift structured data with my Bedrock knowledge base to make the data queryable:

2025 12 25 KBSync

If the credentials are incorrect or lack proper database permissions, the sync will fail:

2025 12 25 KBSyncFail

Bedrock logs issues for review. Typically, IAM updates and/or SQL grants are needed to resolve them.. Here, my Bedrock Execution Role needed access to the public Redshift schema:

SQL
GRANT USAGE ON SCHEMA public TO "IAMR:AmazonBedrockExecutionRoleForKnowledgeBase";

GRANT SELECT ON ALL TABLES IN SCHEMA public TO "IAMR:AmazonBedrockExecutionRoleForKnowledgeBase";

With this done, my sync succeeds and I can start testing my knowledge base.

Knowledge Base Testing

In this section, I will evaluate the Bedrock knowledge base by asking increasingly complex queries. I will start with simple retrievals and then introduce complexity and analytical challenges through ranking, filtering, and aggregation. My goal is to assess comprehension, schema understanding and SQL correctness.

Bedrock isn’t just suggesting SQL here. Instead, it generates and executes SQL directly in Redshift using the knowledge base’s execution role. The queries presented are part of an active execution path rather than just illustrative pseudocode. If the SQL generated is invalid or poorly structured, the query will fail just as it would if I ran it myself.

For each query, I will provide the question I submitted to Bedrock, the SQL that Bedrock generated, and a screenshot of the results. The SQL here is formatted by the excellent CodeBeautify SQL Formatter.

Initial Config

Before I can give queries to the knowledge base, I must configure two settings. Firstly, I must identify the type of response I want:

2025 12 25 KBTestOptions

I’ll use Retrieval and Generation since it returns both the response and the generated SQL. I also need to select a model for Bedrock to use for response generation. In this case, Nova Lite is a suitable option:

2025 12 25 KBTestOptionsModels

The knowledge base can now respond to queries.

Simple Queries

Let’s start by asking about the data as a whole:

How many tracks are in the collection?

Bedrock handles this easily. It generates a straightforward COUNT(*) query and gets the correct number:

SQL
SELECT 
  COUNT(*) AS "total_tracks" 
FROM 
  public.itunes_data;
2025 12 26 22 32 22 QuestionTracks

Next, let’s dig a little deeper. This time I ask about a specific record label:

How many tracks are produced by Anjunabeats?

This should be in the hundreds, but Bedrock returns a far different number:

SQL
SELECT 
  COUNT(*) AS "track_count" 
FROM 
  public.itunes_data 
WHERE 
  artist = 'Anjunabeats';
2025 12 26 22 33 34 QuestionAnjunaWrong

This isn’t a problem with Bedrock. Rather, this is ambiguity within my data. The first Anjunabeats release was Anjunabeats – Volume One, meaning this track and its remixes have both an artist and a publisher of Anjunabeats.

ANJ003
Yes ok this is ANJ003 but the cover is nicer – Ed

Here, Bedrock interprets ‘produced’ in the artist sense and queries on the artist column. Instead, it should use the mtg-publisher column, but it has no way to know that. In response, I change the prompt to use ‘published’ instead of ‘produced’ and try again.

How many tracks are published by Anjunabeats?

This time, Bedrock uses my signposting and gets the correct answer by querying mtg-publisher:

SQL
SELECT 
  COUNT(*) AS "track_count" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats';
2025 12 26 22 35 45 QuestionAnjunaRight

So the first issue I encountered wasn’t related to SQL at all; it was the ambiguity in how Bedrock interpreted my prompt. There are more effective ways to address this ambiguity that I will explore later in this section.

Multi-Constraint Queries

Now let’s try some more demanding questions. I’m still asking about Anjunabeats releases, but I’m also now asking about track ratings:

What are the highest-rated tracks published by Anjunabeats?

Bedrock correctly selects the name and my_rating columns, and also decides to order the results despite not being asked to – nice touch!

Unfortunately, Bedrock then slips back into old habits and, despite my prompt continuing to use published, assumes I’m asking about Anjunabeats – Volume One again and queries one of the artist columns:

SQL
SELECT 
  "name", 
  "my_rating" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-albumartist" = 'Anjunabeats' 
ORDER BY 
  "my_rating" DESC 
LIMIT 10;

So Bedrock tells me about the various Volume One remixes I own:

2025 12 26 22 41 01 QUestionRateWrong

Ok – let’s try changing the prompt. Now, I’m asking firstly about the record label, and then the ratings:

What are the tracks published by Anjunabeats with the highest rating?

This time Bedrock queries on mtg-publisher and the results are correct:

SQL
SELECT 
  "name", 
  "my_rating" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
ORDER BY 
  "my_rating" DESC 
LIMIT 10;
2025 12 29 TracksAnjHighRating

My collection has many top-rated Anjunabeats tracks, so let’s narrow it down by asking about play counts:

Tell me about the tracks published by Anjunabeats with the highest rating. I want to know which tracks have the most plays. Give me the artist, title and year.

Bedrock modifies its query. The artist, title and year columns are all correctly selected, and it makes sense to remove my_rating since the tracks I’m asking about all have the same rating value. The query also now has i aliases – not much use for this query but helpful for joins and window functions.

Unfortunately, although I asked for tracks in the plural, Bedrock returns only 1 result:

SQL
SELECT 
  i.artist, 
  i.name, 
  i.year 
FROM 
  public.itunes_data i 
WHERE 
  i."mtg-publisher" = 'Anjunabeats' 
ORDER BY 
  i.my_rating DESC, 
  i.plays DESC 
LIMIT 1;
2025 12 29 HighRatingMostPlaysLimit1

Why? No idea. To prevent this from happening again, I request five tracks along with some additional fields.

Tell me about the tracks published by Anjunabeats with the highest rating. I want to know the 5 tracks with the most plays. Give me the artist, title, year, initial key and BPM for each track.

Bedrock responds by…talking about Volume One again:

SQL
SELECT 
  "artist", 
  "name", 
  "mtg-year", 
  "mtg-initialkey", 
  "mtg-bpm" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-albumartist" = 'Anjunabeats' 
ORDER BY 
  "plays" DESC 
LIMIT 5;
2025 12 29 1602 FiveTracksMostPlayed

This is definitely something to consider for the future. Anjunabeats isn’t the only Artist/Publisher combo in this dataset! And while I love me some Volume One, it’s not this query’s focus.

So I spell it out in the prompt’s first line:

Tell me about the tracks where the publisher is Anjunabeats. I want to know the 5 tracks with the highest rating and the most plays. Give me the artist, title, year, initial key, BPM and play count for each track.

Success!

SQL
SELECT 
  "artist", 
  "name", 
  "mtg-year", 
  "mtg-initialkey", 
  "mtg-bpm", 
  "plays" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
ORDER BY 
  "my_rating" DESC, 
  "plays" DESC 
LIMIT 5;
2025 12 29 1607 FIveTracksMostPlayedRight

(If these play counts seem low for two-decade-old tracks, all I can say is that record decks don’t collect metadata – Ed)

Complex Query

Let’s see how far we can go! For the last test, I started with a fairly hefty prompt:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– An overall total of tracks

– Totals for each initial key, ordered by initial key

– Totals for each decade (eg 2000 to 2009, 2010 to 2019 etc)

And, well, I broke it:

2025 12 29 1615 QueryFail

Bedrock gave it a good go, but the SQL it sent to Redshift was invalid:

SQL
SELECT 
  COUNT(*) AS "Total Tracks", 
  COUNT(DISTINCT "mtg-initialkey") AS "Total Tracks with Initial Key", 
  COUNT(
    CASE WHEN "mtg-publisher" = 'Anjunabeats' THEN 1 END
  ) AS "Total Anjunabeats Tracks", 
  COUNT(
    CASE WHEN "mtg-publisher" = 'Anjunabeats' 
    AND my_rating IS NOT NULL THEN 1 END
  ) AS "Total Anjunabeats Tracks with Rating", 
  (
    SELECT 
      MAX(my_rating) 
    FROM 
      public.itunes_data 
    WHERE 
      "mtg-publisher" = 'Anjunabeats' 
      AND my_rating IS NOT NULL
  ) AS "Highest Rated Anjunabeats Track", 
  SUM(
    CASE WHEN "mtg-publisher" = 'Anjunabeats' 
    AND my_rating IS NOT NULL THEN 1 ELSE 0 END
  ) OVER (
    PARTITION BY FLOOR("mtg-year" / 10)
  ) AS "Totals by Decade" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
  AND my_rating IS NOT NULL 
ORDER BY 
  "mtg-initialkey";
Plaintext
Redshift query execution failed with error: 
ERROR: column "itunes_data."mtg-publisher"" must appear 
in the GROUP BY clause or be used in an aggregate function.

Fair enough. I would probably break this into multiple queries as well. Let’s ease the pressure a bit by splitting the prompt.

Complex Query: Totals

Firstly, let’s request the overall total of tracks published by Anjunabeats with the highest rating:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– An overall total of tracks

This is a COUNT(*) like the initial query. Bedrock also adds a subquery to get the Anjunabeats MAX(my_rating) value instead of the dataset MAX(my_rating) value:

SQL
SELECT 
  COUNT(*) AS "Total Tracks" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
  AND my_rating = (
    SELECT 
      MAX(my_rating) 
    FROM 
      public.itunes_data 
    WHERE 
      "mtg-publisher" = 'Anjunabeats'
  );

This is sensible. While the MAX(my_rating) value is 100 for both the Anjunabeats record label and the whole dataset, this isn’t true for other labels in the dataset. This version of the query is easier to reuse.

The answer is correct, and I have my baseline value for the other queries – 44 tracks:

2025 12 29 1619 HighRatingTotal

You might think 44/539 is a small number. But I don’t hand out top ratings lightly!

Complex Query: Initial Key Ordering

Now let’s try the second part of the prompt that introduces key aggregation:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– Totals for each initial key, ordered by initial key

And, uh…

2025 12 29 1619 InitialKey

This response feels like a placeholder. I repeated the same query multiple times, and each time I got the same result. I’ll revisit this later.

Complex Query: Decade Grouping

Finally, let’s try the last part of the initial prompt that introduces decade aggregation:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– Totals for each decade (eg 2000 to 2009, 2010 to 2019 etc)

Bedrock creates a new calculated column for this, using an interesting method to calculate decades that I hadn’t considered! For example, take 2005:

  • 2005 / 10 = 200.5
  • FLOOR(200.5) = 200
  • 200 * 10 = 2000

Much better than the CASE statement I was expecting:

SQL
SELECT 
  FLOOR("mtg-year" / 10) * 10 AS decade, 
  COUNT(*) AS total_tracks 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
  AND my_rating = (
    SELECT 
      MAX(my_rating) 
    FROM 
      public.itunes_data 
    WHERE 
      "mtg-publisher" = 'Anjunabeats'
  ) 
GROUP BY 
  FLOOR("mtg-year" / 10) * 10 
ORDER BY 
  decade;

Bedrock confirms what I already knew – that the 2000s were a great time and I miss them terribly:

2025 12 29 1620 BPMRange

Also, as in the first query, these results add up to 44.

Complex Query: Initial Key Ordering Retry

Let’s go back to that failing query from earlier. How about I just ask for the totals and drop the ordering requirement:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– Totals for each key

Bedrock apparently has no issues with this:

SQL
SELECT 
  "mtg-initialkey", 
  COUNT(*) AS "Totals" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
  AND "my_rating" = (
    SELECT 
      MAX("my_rating") 
    FROM 
      public.itunes_data 
    WHERE 
      "mtg-publisher" = 'Anjunabeats'
  ) 
GROUP BY 
  "mtg-initialkey";
2025 12 29 1621 Keys

But this doesn’t add up to 44! This time I was curious to see what data Bedrock was getting, so I added an ORDER BY clause to the query and ran it in Redshift:

2025 12 29 1625 Redshift

So the SQL is valid, and the data is correct and equals 44. The issue here is that Bedrock is summarising the results. In an attempt to stop this, I asked Bedrock to order the results by totals like I had just done:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– Totals for each key, ordered by totals

Bedrock’s SQL is fine again:

SQL
SELECT 
  "mtg-initialkey", 
  COUNT(*) AS "Totals" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
  AND "my_rating" = (
    SELECT 
      MAX("my_rating") 
    FROM 
      public.itunes_data 
    WHERE 
      "mtg-publisher" = 'Anjunabeats'
  ) 
GROUP BY 
  "mtg-initialkey" 
ORDER BY 
  "Totals" DESC;

But this response loses precision after the Gm and Bm keys. Bedrock correctly says 19 keys are in the full list, but is vague beyond this:

2025 12 29 1629 InitialKey

In one final attempt to get the kind of response I’m after, I tell Bedrock not to summarise the data:

Tell me about the tracks where the publisher is Anjunabeats. I want to know about the tracks with the highest rating. I want the following about the tracks meeting these criteria:

– Totals for each key, ordered by totals. do not summarise the data

Bedrock runs the same query as last time…

SQL
SELECT 
  "mtg-initialkey", 
  COUNT(*) AS "Totals" 
FROM 
  public.itunes_data 
WHERE 
  "mtg-publisher" = 'Anjunabeats' 
  AND "my_rating" = (
    SELECT 
      MAX("my_rating") 
    FROM 
      public.itunes_data 
    WHERE 
      "mtg-publisher" = 'Anjunabeats'
  ) 
GROUP BY 
  "mtg-initialkey" 
ORDER BY 
  "Totals" DESC;

…and kind of gives me what I want. Bedrock doesn’t give me all of the keys with 2 tracks and gives me none of the keys with 1 track:

2025 12 29 1630 KeyFInal

I decided that was far enough. This is now crossing into prompt engineering, and the whole point of all this is to test the knowledge base’s ability to use structured data. In that respect, these tests have been successful.

But could I have done things differently?

Future Improvements

I want to end this section by holding my hands up. While Bedrock struggled with some of the tasks I gave it, there were several ways I could have made the process easier for it. As this experience was mainly a proof-of-concept and a learning opportunity, I didn’t implement those measures here.

So instead of concluding with what Bedrock couldn’t achieve, I will outline how I’ll improve future Bedrock implementations as Project Wolfie develops. The following list is not exhaustive – there are definitely unknown unknowns here!

Improved Data Schema: The Parquet file containing my data was created ad hoc, resulting in an unrefined schema with duplicate data and unclear column names. Validation and normalisation processes were also minimal. The Wolfie Data Pipeline will generate a much-improved dataset, which will aid Bedrock’s understanding.

Supportive Descriptions: When creating Bedrock knowledge bases, table and column descriptions, usage notes and additional attributes can be included. These enhance SQL query generation by providing extra context and information about table and column structures. For example, I could have given mtg-publisher a description of ‘record label’ and that might have solved the Volume One issue.

Curated Queries: I can provide predefined examples of questions and answers for the knowledge base, where the questions are natural language queries and the answers are corresponding SQL queries. This gives Bedrock more context for generating SQL. For example, a possible solution to the Anjunabeats confusion could have been:

Plaintext
Q: Tell me about the tracks where the publisher is Anjunabeats.
A: SELECT * FROM public.itunes_data WHERE "mtg-publisher" = 'Anjunabeats'

All things to try out in future versions! Next, let’s talk about costs.

Costs Analysis

This section covers the costs incurred during one week of experimentation in eu-west-1. All figures shown in screenshots are actual charges as reported by AWS. Firstly I’ll examine Bedrock’s costs, followed by Redshift’s.

This account is within my AWS Organisation, and so has access to my Community Builder credits. Some costs will therefore appear as zero until I filter out these credits.

Bedrock Costs

Looking first at Bedrock, my December 2025 bill shows 26 GenerateSQL-StructuredRetrieve requests, totalling USD 0.05:

2025 12 30 20 51 11 CostUsageBill

At the billing level, Bedrock displays a total cost of zero. This indicates how AWS credits are shown, appearing as ‘No region’ credit lines. This information will be relevant shortly!

Now, let’s go to Cost Explorer and adjust the cost granularity. Here are the daily Bedrock expenses for my AWS data sandbox account:

2025 12 30 20 55 36 COstUsageServiceGraph

And this is a table showing the costs filtered by API:

2025 12 30 20 57 53 COstUsageAPITable

Minor rounding artefacts appear at this scale – I’m assuming the 25 December costs are USD 0.00999 and one of the other days is USD 2.00111 or something similar.

Overall, Bedrock costs were low, visible, and easy to reason about. But something is missing…

Redshift Costs

Despite Redshift being central to the architecture, no Redshift charges appear in the billing console during this period. Not even with the debit/credit method shown above. This raises an important question: how exactly does the free trial work?

Well, it turns out that this is by design:

Amazon Redshift Serverless offers a free trial. If you participate in the free trial, you can view the free trial credit balance in the Redshift console, and check free trial usage in the SYS_SERVERLESS_USAGE system view. Note that billing details for free trial usage does not appear in the billing console. You can only view usage in the billing console after the free trial ends.

Billing for Amazon Redshift Serverless

I am NOT a fan of this! I love Cost Explorer for its visibility; everyone with access can view, slice and aggregate the data, quickly identifying trends and hotspots. Not being able to do this with the Redshift Serverless trial feels like a misstep. Surely part of the trial involves understanding Redshift costs like and alongside other AWS services, in order to avoid a big financial shock when the trial ends! Having them separate isn’t great.

Anyway.

There are ways to monitor the costs of a Redshift Serverless trial, but they’re not as intuitive as Cost Explorer. The most obvious way to see how many credits have been used is through the Free Trial widget on the Redshift Serverless dashboard.

2025 12 30 21 00 11 RedshiftTrial

Redshift Serverless is billed using Redshift Processing Units (RPUs). An RPU represents a bundle of compute, memory, and networking capacity, and charges are primarily driven by:

  • The workgroup’s configured Base Capacity.
  • The duration this capacity remains active.

The widget shows USD 56.98 used – higher than I had expected! The billing page mentions SYS_SERVERLESS_USAGE so let’s see what that has to offer:

SQL
SELECT
  * 
FROM
  SYS_SERVERLESS_USAGE
2025 12 30 21 18 56 REdshiftAll

Of particular interest here is the charged_seconds column: the accumulated RPU seconds charged between the start_time and end_time. Handily, the Redshift docs include a query returning aggregated daily costs:

SQL
SELECT
  TRUNC(start_time) "Day",
  (
    sum(charged_seconds)/ 3600 :: DOUBLE PRECISION
  ) * 0.387 as cost_incurred 
FROM
  SYS_SERVERLESS_USAGE
GROUP BY
  1 
ORDER BY
  1
2025 12 30 21 17 26 REdshiftGrouping

That’s… actually more than the widget ($58.62), but I can understand the widget having some lag. So what’s driving these costs?

Redshift Cost Review

Firstly, my workgroup is massively overprovisioned, as the Base Capacity was using the default 128 RPU. Great for performance, but uses a ton of resources and is total overkill for my use case!

Fortunately, Base Capacity can be changed. In Considerations and limitations for Amazon Redshift Serverless capacity, AWS states that configurations with 4 base RPU support managed storage capacity of up to 32 TB. And I have… 2.7GB of total storage used.

I clearly don’t need 128 RPU, so I reduce my Base Capacity to 4 RPUs:

2025 12 30 21 47 37 Performance

While this change led to longer query execution times, expenses quickly stabilised and stopped rising.

Additionally, the Redshift Serverless usage shown is not limited to the Bedrock processes mentioned in this post. During the same time, I was also trying out different features in the Redshift environment, such as:

  • Executing queries manually using my IAM user to explore and test various features of Redshift Serverless.
  • Creating and testing two separate Bedrock knowledge bases (both visible in the Redshift console).
  • Performing ad-hoc exploratory analysis via the Redshift query editor.

Redshift monitors and reports on this activity in the console:

2025 12 30 21 30 03 Users2

My exploratory use of Redshift prolonged workgroup activity, consumed additional RPU and increased costs. As I reduced my exploratory use, the Redshift costs began to align more closely with my expectations.

Summary

In this post, I created a structured data knowledge base using Amazon Bedrock and tested it by allowing it to query a database directly.

Setup Thoughts

Firstly, I was impressed with the respective Redshift and Bedrock setup processes. Although there were some challenges, they primarily involved ensuring services communicated effectively and were resolved quickly. And while some default settings were more helpful than others, they at least provided a starting point for making informed configuration decisions.

Bedrock’s costing is transparent, so I could also make informed cost decisions. And while I’m a big fan of the Redshift Serverless free trial, I wish it was trackable within Cost Explorer. In the meantime, I’ll keep a close eye on SYS_SERVERLESS_USAGE!

Testing Thoughts

Testing the knowledge base was straightforward, and I quickly understood how Bedrock interacted with Redshift. Seeing the actual queries being executed not only helps optimise the knowledge base but also informs potential architectural changes to the database.

The results emphasise the importance of data structure and quality. I’ve worked with data for almost a decade now, and have seen many sales pitches claiming to remove the need for SQL, data modelling or normalisation. The reality is that, especially in the current AI era, well-structured and properly modelled data and an understanding of how to query it effectively remain crucial.

As I’ve shown here, without these data controls, an AI attempting to use such data is likely to produce incorrect, inconsistent or inaccurate outputs. While simple queries and explicit prompts can help mitigate these issues, it is more beneficial to start with clean, well-structured data.

A knowledge base that can access clean, normalised data stores lets users focus on interpreting answers rather than rephrasing questions. This will be a key consideration for the architecture of the Project Wolfie data pipelines.

Finally, I’ll leave you with an AWS demo video in which Lester Sim creates his own Bedrock structured data knowledge base:

Like this post? Click the button below for links to contact, socials, projects and sessions:
SharkLinkButton 1

Thanks for reading ~~^~~
Categories
Data & Analytics

Python Data Validation And Observability As Code With Pydantic

In this post, I use the Pydantic Python library to create data validation and observability processes for my Project Wolfie iTunes data.

Introduction

Data validation is a crucial component of any data project. It ensures that data is accurate, consistent and reliable. It verifies that data meets set criteria and rules to maintain its quality, and stops erroneous or unreliable information from entering downstream systems. I’ve written about it, scripted it and talked about it.

Validation will be a crucial aspect of Project Wolfie. It is an ongoing process that should occur from data ingestion to exposure, and should be automated wherever possible. Thankfully, most data processes within Project Wolfie are (and will be) built using Python, which provides several libraries to simplify data validation. These include Pandera, Great Expectations and the focus of this post – Pydantic (specifically, version 2).

Firstly, I’ll explore the purpose and benefits of Pydantic. Next, I’ll import some iTunes data and use it to explore key Pydantic validation concepts. Finally, I’ll explore how Pydantic handles observability and test its findings. The complete code will be in a GitHub repo.

Let’s begin!

Introducing Pydantic

This section introduces Pydantic and examines some of its benefits.

About Pydantic

Pydantic is an open-source data validation Python library. It uses established Python notation and constructs to define data structures, types and constraints. These can then validate the provided data, generating clear error messages when issues occur.

Pydantic is a widely used tool for managing application settings, validating API requests and responses, and streamlining data transfer between Python objects and formats like JSON. By integrating both existing and custom elements, it offers a powerful and Pythonic method for ensuring data quality and consistency within projects. This makes data handling in Python more reliable and reduces the likelihood of errors through its intuitive definition and validation processes.

Pydantic Benefits

Pydantic’s benefits are thoroughly documented, and the ones I want to highlight here are:

Intuitive: Pydantic’s use of type hints, functions and classes fits well with my current Python skill level, so I can focus on learning Pydantic without also having to explore unfamiliar Python concepts.

Fast: Pydantic’s core validation logic is written in Rust, which enables rapid development, testing, and validation. This speed has contributed towards…

Well-Supported: Pydantic has extensive community use and support from organisations like Anthropic, Netflix and OpenAI, as well as popular Python libraries like Airflow, FastAPI and LangChain. It also has extensive AWS Lambda support via user-configurable artefacts and the community-managed Powertools for AWS Lambda (Python)‘s Parser utility.

Preparation

Before I can start using Pydantic, I need some data. This section examines the data I am using and how I prepare it for Pydantic.

iTunes Data

Firstly, let’s extract some data from iTunes. I create iTunes Export files using the iTunes > Export Playlist command. Apple has documented this, but WikiHow’s documentation is more illustrative. The export file type choices are…interesting. The one closest to matching my needs is the txt format, although the files are technically tab-separated files (TSVs).

iTunes Exports contain many metadata columns. I’m not including them all here (after all, this is a Pydantic post not an iTunes one), but I will be using the following subset (using my existing metadata definitions):

Metadata TypeColumn NameData TypePurpose
TechnicalAlbumStringTrack key as Camelot Notation*
TechnicalLocationStringTrack file path
TechnicalTrack NumberIntegerTrack BPM*
DescriptiveArtistStringTrack artist(s)
DescriptiveGenreStringTrack genre
DescriptiveNameStringTrack name and mix
DescriptiveWorkStringPublishing record label
DescriptiveYearIntegerTrack release year
InteractionMy RatingIntegerTrack personal rating

Note that the starred Album and Track Number columns have purposes that differ from the column names. The reasons for this are…not ideal.

  • Track Number contains BPM data as, although iTunes does have a BPM column, it isn’t included in the exports. And the exports can’t be customised! To include BPMs in an export, I had to repurpose an existing column.

Great. But that’s not as bad as…

  • Album contains musical keys, as iTunes doesn’t even have a key column, despite MP3s having a native Initial Key metadata field! Approaches to dealing with this vary – I chose to use another donor column. I’ll explain Camelot Notations later on.

That’s enough about the iTunes data for now – I’ll go into more detail in future Project Wolfie posts. Now let’s focus on getting this data into memory for Python.

Data Capture

Next, let’s get the iTunes data into memory. Starting with a familiar library…

pandas

I’ll be using pandas to ingest the iTunes data. This is a well-established and widely supported module. It also has its own data validation functions and will assist with issues like handling spaces in column names.

While iTunes files aren’t CSVs, the pandas read_csv function can still read their data into a DataFrame. It needs some help though – the delimiter parameter must be \t to identify the tabs’ delimiting status.

So let’s read the iTunes metadata into memory and…

Python
df = pd.read_csv(csv_path, delimiter='\t')

>> UnicodeDecodeError: 'utf-8' codec can't decode byte 0xff in position 0: invalid start byte

Oh. pandas can’t read the file. The error says it’s trying the utf-8 codec, so the export must be using something else. Fortunately, there’s another Python library that can help!

charset_normalizer

charset_normalizer is an open-source encoding detector. It determines the encoding of a file or text and records the result. It’s related to the older chardet library but is faster, has a more permissive MIT license and supports more encodings.

Here, I’m using charset_normalizer.detect in a detect_file_encoding function to detect the export’s codec:

Python
def detect_file_encoding(file_path: Path) -> str:
    with open(file_path, 'rb') as file:
        raw_data = file.read()
        
    detection_result = charset_normalizer.detect(raw_data)
    return detection_result['encoding'] or 'utf-8'

In which:

  • I define a detect_file_encoding function that expects a filepath and returns a string.
  • detect_file_encoding opens the file, reads the data and stores it as raw_data.
  • charset_normalizer detects raw_data‘s codec and stores this as detection_result.
  • detect_file_encoding returns either the successfully detected codec, or the common utf-8 codec if the attempt fails.

I can then pass the export’s filepath to the detect_file_encoding function, capture the results as encoding and pass this as a parameter to pandas.read_csv:

Python
encoding = detect_file_encoding(csv_path)
    
df = pd.read_csv(csv_path, encoding=encoding, delimiter='\t')

>> Loaded 4407 rows

There’s one more action to take before moving on. Some columns contain spaces. This will become a problem as spaces are not allowed in Python identifiers!

As the data is now in a pandas DataFrame, I can use pandas.DataFrame.rename to remove these spaces:

Python
df = df.rename(columns={
        'Track Number': 'TrackNumber',
        'My Rating': 'MyRating'
    })

The metadata is now ready for Pydantic.

Installing Pydantic

Finally, let’s install Pydantic. This process is fully documented. My preferred method is via pip install in a local virtual environment:

Python
pip install pydantic

And then importing Pydantic into my script:

Python
import pydantic

Now I can start using Pydantic.

Pydantic Data Models

In this section, I tell Pydantic about my data model and the types of data it should expect for validation.

Introducing BaseModel

At the core of Pydantic is the BaseModel class – used for defining data models. Every Pydantic model inherits from it, and by doing so gains features like type enforcement, automatic data parsing and built-in validation.

By subclassing BaseModel, a schema for the data is defined using standard Python type hints. Pydantic uses these hints to validate and convert input data automatically.

Let’s explore BaseModel by creating a new Track class.

Creating A Track Class

Pydantic supports standard library types like string and integer. This reduces Pydantic’s learning curve and simplifies integration into existing Python processes.

Here are the very beginnings of my Track data model. I have a new Track class inheriting from Pydantic’s BaseModel, and a Name field with string data type:

Python
class Track(BaseModel):
    Name: str

Next, I add a Year field with integer data type:

Python
class Track(BaseModel):
    Name: str
    Year: int

And so on for each field I want to validate with Pydantic:

Python
class Track(BaseModel):
    Name: str
    Artist: str
    Album: str
    Work: str
    Genre: str
    TrackNumber: int
    Year: int
    MyRating: int
    Location: str

Now, if any field is missing or has the wrong type, Pydantic will raise a ValidationError. But there’s far more to Pydantic data types than this…

Defining Special Data Types

Where no standards exist or where validation rules are more complex to determine, Pydantic offers further type coverage. These include:

One of my Track fields will immediately benefit from this:

Python
class Track(BaseModel):
    Location: str

Currently, my Location field validation is highly permissive. It will accept any string. I can improve this using Pydantic’s FilePath data type:

Python
class Track(BaseModel):
    Location: FilePath

Now, Pydantic will check that the given location is a path that exists and links to a valid file. No custom code; no for loops – the FilePath type handles everything for me.

So I now have data type validation in my Pydantic data model. What else can I have?

Pydantic Built-In Validation

This section explores the native data validation features of Pydantic, including field annotation and constraints.

Introducing Field

In Pydantic models, data attributes are typically defined using Python type hints. The Field function enables further customisation like constraints, schema metadata and default values.

While type hints define what kind of data is allowed, Field defines how that data should behave, what happens if it’s missing and how it should be documented. It adds clarity to models and helps Pydantic enforce stricter rules.

Let’s run through some examples.

Custom Schema Metadata

One of the challenges in creating data pipelines is that the data fields can sometimes be unclear or difficult to explain. This can cause confusion and delay when building ETLs, examining repos and interacting with code.

Field helps here by adding custom fields to annotate data within Pydantic classes. Examples include description:

Python
class Track(BaseModel):
    Name: str = Field(
        description="Track's name and mix.")

And examples:

Python
class Track(BaseModel):
    Name: str = Field(
        description="Track's name and mix.",
        examples=["Track Title (Original Mix)", "Track Title (Extended Mix)"])

Using these throughout my Track class simplifies the code and reduces context switching:

Python
class Track(BaseModel):
    Name: str = Field(
        description="Track's name and mix.",
        examples=["Track Title (Original Mix)", "Track Title (Extended Mix)"])
    
    Artist: str = Field(
        description="The artist(s) of the track.",
        examples=["Above & Beyond", "Armin van Buuren"])
    
    Album: str = Field(
        description="Track's Camelot Notation indicating the key.",
        examples=["01A-Abm", "02B-GbM"])
    
    Work: str = Field(
        description="The record label that published the track.",
        examples=["Armada Music", "Anjunabeats"])
    
    Genre: str = Field(
        description="Track's musical genre.",
        examples=["Trance", "Progressive House"])
    
    TrackNumber: int = Field(
        description="Track's BPM (Beats Per Minute).",
        examples=[130, 140])
    
    Year: int = Field(
        description="Track's release year.",
        examples=[1998, 2004])
    
    MyRating: int = Field(
        description="Personal Rating.  Stars expressed as 0, 20, 40, 60, 80, or 100",
        examples=[60, 80])
    
    Location: FilePath = Field(
        description="Track's Location on the filesystem.",
        examples=[r"C:\Users\User\Music\iTunes\TranquilityBase-GettingAway-OriginalMix.mp3"])

This is especially useful for Album and TrackNumber given their unique properties.

Field Constraints

Field can also constrain the data that a class accepts. This includes string constraints:

  • max_length: Maximum length of the string.
  • min_length: Minimum length of the string.
  • pattern: A regular expression that the string must match.

and numeric constraints:

  • ge & le – greater than or equal to/less than or equal to
  • gt & lt – greater/less than
  • multiple_of – multiple of a given number

Constraints can also be combined as needed. For example, iTunes exports record MyRating values in increments of 20, where 1 star is 20 and 2 stars are 40, rising to the maximum 5 stars being 100.

I can express this within the Track class as:

Python
class Track(BaseModel):
    MyRating: int = Field(
        description="Personal Rating.  Stars expressed as 0, 20, 40, 60, 80, or 100",
        examples=[60, 80],
        ge=20,
        le=100,
        multiple_of=20)

Here, MyRating must be greater than or equal to 20 (ge=20), less than or equal to 100 (le=100), and must be a multiple of 20 (multiple_of=20).

I can also parameterise these constraints using variables instead of hard-coded values:

Python
ITUNES_RATING_RAW_LOWEST = 20
ITUNES_RATING_RAW_HIGHEST = 100

class Track(BaseModel):
    MyRating: int = Field(
        description="Personal Rating.  Stars expressed as 0, 20, 40, 60, 80, or 100",
        examples=[60, 80],
        ge=ITUNES_RATING_RAW_LOWEST,
        le=ITUNES_RATING_RAW_HIGHEST,
        multiple_of=20)

This property lets me use Pydantic with other Python libraries. Here, my Year validation checks for years greater than or equal to 1970 and less than or equal to the current year (using the datetime library):

Python
YEAR_EARLIEST = 1970
YEAR_CURRENT = datetime.datetime.now().year

class Track(BaseModel):
    Year: int = Field(
        description="Track's release year.",
        examples=[1998, 2004],
        ge=YEAR_EARLIEST,
        le=YEAR_CURRENT)

No track in the collection should exist beyond the current year – this constraint will now update itself as time passes.

Having applied other constraints, my Track class looks like this:

Python
class Track(BaseModel):
    """Pydantic model for validating iTunes track metadata."""
    
    Name: str = Field(
        description="Track's name and mix type.",
        examples=["Track Title (Original Mix)", "Track Title (Extended Mix)"])
    
    Artist: str = Field(
        description="The artist(s) of the track.",
        examples=["Above & Beyond", "Armin van Buuren"])
    
    Album: str = Field(
        description="Track's Camelot Notation indicating the key.",
        examples=["01A-Abm", "02B-GbM"])
    
    Work: str = Field(
        description="The record label that published the track.",
        examples=["Armada Music", "Anjunabeats"])
    
    Genre: str = Field(
        description="Track's musical genre.",
        examples=["Trance", "Progressive House"])
    
    TrackNumber: int = Field(
        description="Track's BPM (Beats Per Minute).",
        examples=[130, 140],
        ge=BPM_LOWEST,
        le=BPM_HIGHEST)
    
    Year: int = Field(
        description="Track's release year.",
        examples=[1998, 2004],
        ge=YEAR_EARLIEST,
        le=YEAR_CURRENT)
    
    MyRating: int = Field(
        description="Personal Rating. Stars expressed as 0, 20, 40, 60, 80, or 100",
        examples=[60, 80],
        ge=ITUNES_RATING_RAW_LOWEST,
        le=ITUNES_RATING_RAW_HIGHEST,
        multiple_of=20)
    
    Location: FilePath = Field(
        description="Track's Location on the filesystem.",
        examples=[r"C:\Users\User\Music\iTunes\AboveAndBeyond-AloneTonight-OriginalMix.mp3"])

This is already very helpful. Next, let’s examine my custom requirements.

Pydantic Custom Validation

This section discusses how to create custom data validation using Pydantic. I will outline what the requirements are, and then examine how these validations are defined and implemented.

Introducing Decorators

In Python, decorators modify or enhance the behaviour of functions or methods without changing their actual code. Decorators are usually written using the @ symbol followed by the decorator name, just above the function definition:

Python
@my_decorator
def my_function():
    ...

For example, consider this logger_decorator function:

Python
def logger_decorator(func):
    def wrapper():
        print(f"Running {func.__name__}...")
        func()  # Execute the supplied function
        print("Done!")
    return wrapper

This function takes another function (func) as an argument, printing a message before and after execution. If the logger_decorator function is then used as a decorator when running this greet function:

Python
@logger_decorator
def greet():
    print("Hello, world!")

greet()

Python will add the logging behaviour of logger_decorator without modifying greet:

Python
Running greet...
Hello, world!
Done!

Introducing Field Validators

In addition to the built-in data validation capabilities of Pydantic, custom validators with more specific rules can be defined for individual fields using Field Validators. These use the field_validator() decorator, and are declared as class methods within a class inheriting from Pydantic’s BaseModel.

Here’s a basic example using my Track model:

Python
class Track(BaseModel):
    Name: str = Field(
        description="Track's name and mix.",
        examples=["Track Title (Original Mix)", "Track Title (Extended Mix)"]
    )

    @field_validator("Name")
    @classmethod
    def validate_name(cls, value):
        # custom validation logic here
        return value

Where:

  • @field_validator("Name") tells Pydantic to use the function to validate the Name field.
  • @classmethod lets the validator access the Track class (cls).
  • The validator executes the validate_name function with the field value (in this case Name) as input, performs the checks and must either:
    • return the validated value, or
    • raise a ValueError or TypeError if validation fails.

Let’s see this in action.

Null Checks

Firstly, let’s perform a common data validation check by identifying empty fields. I have two variants of this – one for strings and another for numbers.

The first – validate_non_empty_string – uses pandas.isna to catch missing values and strip() to catch empty strings. This field validator applies to the Artist, Work and Genre columns:

Python
    @field_validator("Artist", "Work", "Genre")
    @classmethod
    def validate_non_empty_string(cls, value, info):
        """Validate that a string field is not empty."""
        if pd.isna(value) or str(value).strip() == "":
            raise ValueError(f"{info.field_name} must not be null or empty")
        return value

The second – validate_non_null_numeric – checks the TrackNumber, Year and MyRating numeric columns for empty values using pandas.isna:

Python
    @field_validator("TrackNumber", "Year", "MyRating", mode="before")
    @classmethod
    def validate_non_null_numeric(cls, value, info):
        """Validate that a numeric field is not null."""
        if pd.isna(value):
            raise ValueError(f"{info.field_name} must not be null")
        return value

Also, it uses Pydantic’s before validator (mode="before"), ensuring the data validation happens before Pydantic coerces types. This catches edge cases like "" or "NaN" before they become None or float("nan") values.

Character Check

Now let’s create a validator for something a little more challenging to define. All tracks in my collection follow a Track Name (Mix) schema. This can take many forms:

  • Original track: Getting Away (Original Mix)
  • Remixed track: Shapes (Oliver Smith Remix)
  • Updated remixed track: Distant Planet (Menno de Jong Interpretation) (2020 Remaster)
  • …and many more variants.

But generally, there should be at least one instance of text enclosed by parentheses. However, some tracks have no remixer and are released with just a title:

  • Getting Away
  • Shapes
  • Distant Planet

This not only looks untidy (eww!), but also breaks some of my downstream automation that expects the Track Name (Mix) schema. So any track without a remixer gets (Original Mix) added to the Name field upon download:

  • Getting Away (Original Mix)
  • Shapes (Original Mix)
  • Distant Planet (Original Mix)

Expressing this is possible with RegEx, but I can make a more straightforward and more understandable check with a field validator:

Python
    @field_validator("Name")
    @classmethod
    def validate_name(cls, value):
        if pd.isna(value) or str(value).strip() == "":
            raise ValueError("Name must not be null or empty")
        
        value_str = str(value)
        if '(' not in value_str:
            raise ValueError("Name must contain an opening parenthesis '('")
        if ')' not in value_str:
            raise ValueError("Name must contain a closing parenthesis ')'")
        return value

This validator checks that the value isn’t empty and then performs additional checks for parentheses. This could be one check, but having it as two checks improves log readability (insert foreshadowing – Ed). I could also have added Name to the validate_non_empty_string validation, but this way I have all my Name checks in the same place.

Parameterised Checks

Like constraints, field validators can also be parameterised. Let’s examine Album.

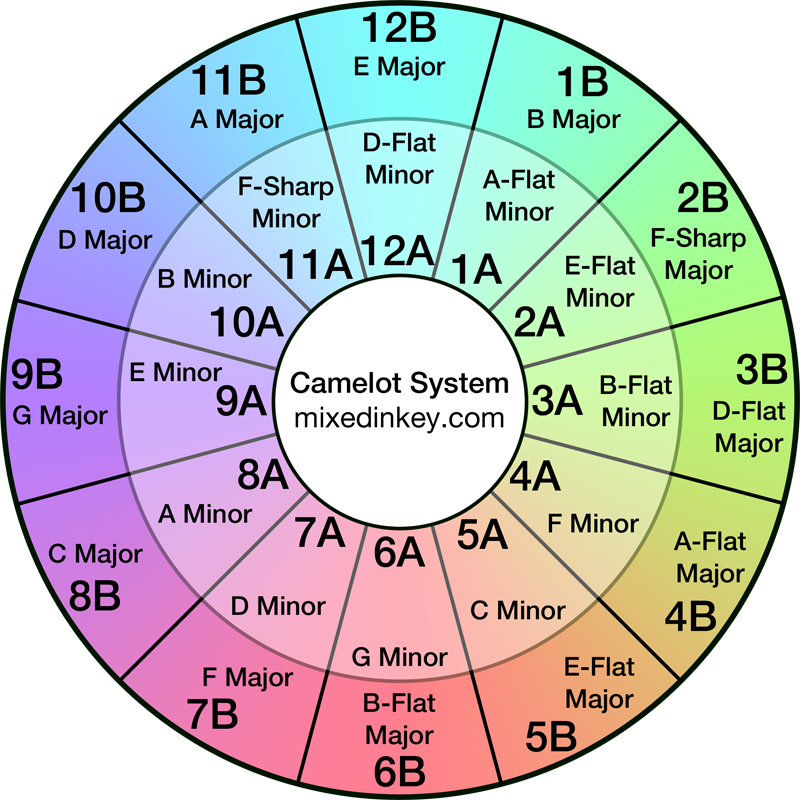
As iTunes exports can’t be customised, I use Album for a track’s Camelot Notation. These are based on the Camelot Wheel – MixedInKey‘s representation of the Circle Of Fifths. DJs generally favour Camelot Notation as it is simpler than traditional music notation for human understanding and application sorting.

Importantly, there are only twenty-four possible notations:

For example:

  • 1A (A-Flat Minor)
  • 6A (G Minor)
  • 6B (B-Flat Major)
  • 10A (B Minor)

So let’s capture these values in a CAMELOT_NOTATIONS list:

Python
CAMELOT_NOTATIONS = {
    '01A-Abm', '01B-BM', '02A-Ebm', '02B-GbM', '03A-Bbm', '03B-DbM',
    '04A-Fm', '04B-AbM', '05A-Cm', '05B-EbM', '06A-Gm', '06B-BbM',
    '07A-Dm', '07B-FM', '08A-Am', '08B-CM', '09A-Em', '09B-GM',
    '10A-Bm', '10B-DM', '11A-Gbm', '11B-AM', '12A-Dbm', '12B-EM'
}

(Note the leading zeros. Without them, iTunes sorts the Album column as (10, 11, 12, 1, 2, 3…) – you can imagine how I felt about that – Ed)

Next, I pass the CAMELOT_NOTATIONS list to an Album field validator that checks if the given value is in the list:

Python
    @field_validator("Album")
    @classmethod
    def validate_album(cls, value):
        if pd.isna(value) or str(value).strip() == "":
            raise ValueError("Album must not be null or empty")
        
        if str(value) not in CAMELOT_NOTATIONS:
            raise ValueError(f"Album must be a valid Camelot notation: {value} is not in the valid list")
        return value

Pydantic now fails any value not found in the CAMELOT_NOTATIONS list.

Now I have my validation needs fully covered. What observability does Pydantic give me over these data validation checks?

Pydantic Observability

In this section, I assess and adjust the default Pydantic observability abilities to ensure my data validation is accurately recorded.

Default Output

Pydantic automatically generates data validation error messages if validation fails. These detailed messages provide a structured overview of the issues encountered, including:

  • The index of the failing input (e.g., a DataFrame row number).
  • The model class where the error occurred.
  • The field name that failed validation.
  • A human-readable explanation of the issue.
  • The offending input value and its type.
  • A direct link to relevant documentation for further guidance.

Here’s an example of Pydantic’s output when a string field receives a NaN value:

Python
Row 2353: 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type

In this example:

  • Row 2353 indicates the problematic input row.
  • Track is the Pydantic model where validation failed.
  • Work is the failing field.
  • Pydantic detects that the input is nan (a float) and not a valid string.
  • Pydantic provides a URL to the string_type documentation.

Here’s another example, this time for a MyRating error:

Python
Row 3040: 1 validation error for Track
MyRating
  Value error, MyRating must not be null [type=value_error, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

In this case, a field validator raised a ValueError because MyRating must not be null.

Pydantic’s error reporting is clear and actionable, making it suitable for debugging and systemic data validation tasks. However, for larger datasets or more user-friendly outputs (such as reports or UI feedback), further customisation is helpful, such as…

Terminal Output Customisation

As good as Pydantic’s default output is, it’s not that human-readable. For example, in this Terminal output I have no idea which tracks are on rows 2353, 2495 and 3040:

Plaintext
Row 2353: 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type
    
Row 2495: 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type
    
Row 3040: 1 validation error for Track
MyRating
  Value error, MyRating must not be null [type=value_error, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

While I can find this out, it would be better to know at a glance. Fortunately, I can improve this when capturing the errors by appending the artist and name to each row of the errors object:

Python
except (ValidationError, ValueError) as e:
            artist = row['Artist'] if not pd.isna(row['Artist']) else "Unknown Artist"
            name = row['Name'] if not pd.isna(row['Name']) else "Unknown Name"
            errors.append((index, artist, name, str(e)))

Now, Artist and Name are added to each row:

Plaintext
Row 2353: Ben Stone - Mercure (Extended Mix): 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type
    
Row 2495: DJ Hell - My Definition Of House Music (Resistance D Remix): 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type
    
Row 3040: York - Reachers Of Civilisation (In Search Of Sunrise Mix): 1 validation error for Track
MyRating
  Value error, MyRating must not be null [type=value_error, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

This makes it far easier to find the problematic files in my collection. As long as there aren’t many findings…

Creating An Error File

There are three main problems with Pydantic printing all data validation errors in the Terminal:

  • They don’t persist outside of the Terminal session.
  • The Terminal isn’t that easy to read when it’s full of text.
  • The Terminal may run out of space if there are a large number of errors.

So let’s capture the errors in a file instead. This write_error_report function generates a text-based error report from validation failures, saving it in a logs subfolder adjacent to the input file:

Python
def write_error_report(
    csv_path: Path, 
    field_error_details: Dict[str, List[str]],  
    sorted_fields: List[str]
) -> Path:

    timestamp = datetime.now().strftime("%Y%m%d-%H%M%S")
    logs_dir = csv_path.parent / "logs"
    logs_dir.mkdir(exist_ok=True)
    
    error_output_path = logs_dir / f"{timestamp}-PydanticErrors-{csv_path.stem}.txt"
    
    with open(error_output_path, 'w', encoding='utf-8') as f:
        f.write(f"Validation Error Report - {timestamp}\n")
        f.write("=" * 80 + "\n")

        for field in sorted_fields:
            messages = field_error_details.get(field, [])
            if messages:
                f.write(f"\n{field} Errors ({len(messages)}):\n")
                f.write("-" * 80 + "\n")
                for message in messages:
                    f.write(message + "\n\n")
    
    return error_output_path

Firstly, it constructs a timestamped filename using the original file’s stem (e.g., 20250529-142304-PydanticErrors-data.txt) and the logs subfolder, creating the latter if it doesn’t exist:

Python
    timestamp = datetime.now().strftime("%Y%m%d-%H%M%S")
    logs_dir = csv_path.parent / "logs"
    logs_dir.mkdir(exist_ok=True)
    
    error_output_path = logs_dir / f"{timestamp}-PydanticErrors-{csv_path.stem}.txt"

Next, Python orders the errors by the sorted_fields input, displays error counts per field and formats each error message with clear section dividers. A structured report listing all validation errors by field is saved in the logs subfolder:

Python
    with open(error_output_path, 'w', encoding='utf-8') as f:
        f.write(f"Validation Error Report - {timestamp}\n")
        f.write("=" * 80 + "\n")

        for field in sorted_fields:
            messages = field_error_details.get(field, [])
            if messages:
                f.write(f"\n{field} Errors ({len(messages)}):\n")
                f.write("-" * 80 + "\n")
                for message in messages:
                    f.write(message + "\n\n")

Finally, the filesystem path of the generated report is returned:

Python
    return error_output_path

When executed, the Terminal tells me the error file path:

Plaintext
Detailed error log written to: 20250513-133743-PydanticErrors-iTunes-Elec-Dance-Club-Main.txt

And stores the findings in a local txt file, grouped by error type for simpler readability:

Plaintext
Validation Error Report - 20250513-133743
================================================================================

MyRating Errors (5):
--------------------------------------------------------------------------------
Row 3040: York - Reachers Of Civilisation (In Search Of Sunrise Mix): 1 validation error for Track
MyRating
  Value error, MyRating must not be null [type=value_error, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

Work Errors (22):
--------------------------------------------------------------------------------
Row 223: Dave Angel - Artech (Original Mix): 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type

Adding A Terminal Summary

Finally, I created a Terminal summary of Pydantic’s findings:

Python
print("\nValidation Summary:\n")
sorted_fields = sorted(Track.model_fields.keys())

for field in sorted_fields:
  count = error_analysis['counts'].get(field, 0)
  print(f"{field} findings: {count}")

This shows feedback after each execution:

Plaintext
Validation Summary:

Album findings: 0
Artist findings: 0
Genre findings: 0
Location findings: 0
MyRating findings: 5
Name findings: 1
TrackNumber findings: 0
Work findings: 22
Year findings: 0

Now, let’s ensure everything works properly!

Testing Pydantic

In this section, I test that my Pydantic data validation and observability processes are working correctly using iTunes export files and pytest unit tests.

Recent File Test

The first test used a recent export from the end of April 2025. Here is the Terminal output:

Plaintext
Processing file: iTunes-Elec-Dance-Club-Main-2025-04-28.txt
Reading iTunes-Elec-Dance-Club-Main-2025-04-28.txt with detected encoding UTF-16
Loaded 4407 rows
Validated 4379 rows
Found 28 errors!

Validation Summary for iTunes-Elec-Dance-Club-Main-2025-04-28.txt:
Album errors: 0
Artist errors: 0
Genre errors: 0
Location errors: 0
MyRating errors: 5
Name errors: 1
TrackNumber errors: 0
Work errors: 22
Year errors: 0

Detailed error log written to: 20250521-164324-PydanticErrors-iTunes-Elec-Dance-Club-Main-2025-04-28.txt

Good first impressions – the 4407 row count matches the export file, the summary is shown in the Terminal and an error log is created. So what’s in the log?

Firstly, five tracks have no MyRating values. For example:

Plaintext
MyRating Errors (5):
--------------------------------------------------------------------------------
Row 558: Reel People Feat Angela Johnson - Can't Stop (Michael Gray Instrumental Remix): 1 validation error for Track
MyRating
  Value error, MyRating must not be null [type=value_error, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

This is correct, as this export was created when I added some new tracks to my collection.

Next, one track has a Name issue:

Plaintext
Name Errors (1):
--------------------------------------------------------------------------------
Row 1292: The Prodigy - Firestarter (Original Mix}: 1 validation error for Track
Name
  Value error, Name must contain a closing parenthesis ')' [type=value_error, input_value='Firestarter (Original Mix}', input_type=str]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

This one confused me at first, until I looked at the error more closely and realised the closing parenthesis is wrong! } is used instead of )! This is why my validate_name field validator has separate checks for each character – it makes it easier to understand the results!

Finally, twenty-two tracks are missing record label metadata in Work:

Plaintext
Work Errors (22):
--------------------------------------------------------------------------------
Row 223: Dave Angel - Artech (Original Mix): 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type

This means some tracks are missing full metadata. This won’t break any downstream processes as I have no reliance on this field. That said, it’s good to know about this in case my future needs change.

Older File Test

The next test uses an older file from March 2025. Let’s see what the Terminal says this time…

Plaintext
Processing file: iTunes-AllTunesMaster-2025-03-01.txt      
Reading iTunes-AllTunesMaster-2025-03-01.txt with detected encoding UTF-16
Loaded 4381 rows
Validated 0 rows
Found 4381 errors!

Validation Summary for iTunes-AllTunesMaster-2025-03-01.txt:

Album errors: 0
Artist errors: 0
Genre errors: 0
Location errors: 4381
MyRating errors: 0
Name errors: 1
TrackNumber errors: 2
Work errors: 17
Year errors: 0
Detailed error log written to: 20250521-164322-PydanticErrors-iTunes-AllTunesMaster-2025-03-01.txt

There are fewer rows here – 4381 vs 4407. This is correct, as my collection was smaller in March. But no rows were validated successfully!

I don’t have to go far to find out why:

Plaintext
Location Errors (4381):
--------------------------------------------------------------------------------
Row 0: Ariel - A9 (Original Mix): 1 validation error for Track
Location
  Path does not point to a file [type=path_not_file, input_value='C:\\Users\\User\\Folder...riel-A9-OriginalMix.mp3', input_type=str]

All the location checks failed. But this is actually a successful test!

In the time between these two exports, I reorganised my music collection. As a result, the file paths in this export no longer exist. Remember – the Location field uses the FilePath data type, which checks that the given paths exist and link to valid files. And these don’t!

The Name results are the same as the first test. This has been around for a while apparently…

Plaintext
Name Errors (1):
--------------------------------------------------------------------------------
Row 1292: The Prodigy - Firestarter (Original Mix}: 1 validation error for Track
Name
  Value error, Name must contain a closing parenthesis ')' [type=value_error, input_value='Firestarter (Original Mix}', input_type=str]
    For further information visit https://errors.pydantic.dev/2.11/v/value_error

There are also TrackNumber errors in this export:

Plaintext
TrackNumber Errors (2):
--------------------------------------------------------------------------------
Row 485: Andrew Bayer Feat Alison May - Brick (Original Mix): 2 validation errors for Track
TrackNumber
  Input should be greater than or equal to 100 [type=greater_than_equal, input_value=90, input_type=int]
    For further information visit https://errors.pydantic.dev/2.11/v/greater_than_equal

Two tracks have BPM values lower than the set range. Both files were moved during my reorganisation, but were included in this export at the time and therefore fail this validation check.

Finally, the Work errors are the same as the first test (although more have crept in since!):

Plaintext
Work Errors (17):
--------------------------------------------------------------------------------
Row 223: Dave Angel - Artech (Original Mix): 1 validation error for Track
Work
  Input should be a valid string [type=string_type, input_value=nan, input_type=float]
    For further information visit https://errors.pydantic.dev/2.11/v/string_type

Ultimately, both tests match expectations!

Unit Tests With Amazon Q

Finally, I wanted to include some unit tests for this project. Unit testing is always a good idea, especially in this context where I can verify function outputs and error generation without needing to create numerous test files.

I figured this was a good opportunity to test Amazon Q Developer and see what it came up with. I gave it a fairly basic prompt, using the @workspace context to allow Q access to my project’s entire workspace as context for its responses:

Plaintext
@workspace write unit tests for this script using pytest

I tend to use pytest for my Python testing, as I find it simpler and more flexible than Python’s standard unittest library.

Q promptly provided several reasonable tests in response. This initiated a half-hour exchange between us focused on calibrating the existing tests and creating new ones. To be fair to Q, my initial prompt was quite basic and could have been much more detailed.

Amongst Q’s tests was this one testing an empty Artist field:

Python
    @patch('pathlib.Path.exists')
    def test_empty_artist(self, mock_exists):
        """Test that an empty artist fails validation."""
        # Mock file existence check
        mock_exists.return_value = True
        
        invalid_track_data = {
            "Name": "Test Track (Original Mix)",
            "Artist": "",  # Empty artist
            "Album": "01A-Abm",
            "Work": "Test Label",
            "Genre": "Trance",
            "TrackNumber": 130,
            "Year": 2020,
            "MyRating": 80,
            "Location": "C:\\Music\\test_track.mp3"
        }

This one, checking an invalid Camelot Notation:

Python
@patch('pathlib.Path.exists')
    def test_invalid_album_not_camelot(self, mock_exists):
        """Test that an invalid Camelot notation fails validation."""
        # Mock file existence check
        mock_exists.return_value = True
        
        invalid_track_data = {
            "Name": "Test Track (Original Mix)",
            "Artist": "Test Artist",
            "Album": "Invalid Key",  # Not a valid Camelot notation
            "Work": "Test Label",
            "Genre": "Trance",
            "TrackNumber": 130,
            "Year": 2020,
            "MyRating": 80,
            "Location": "C:\\Music\\test_track.mp3"
        }
        
        with pytest.raises(ValueError, match="Album must be a valid Camelot notation"):
            Track(**invalid_track_data)

And this one, checking what happens with an incomplete DataFrame:

Python
    @patch('wolfie_exportvalidator_itunes.detect_file_encoding')
    @patch('pandas.read_csv')
    def test_load_itunes_data_missing_columns(self, mock_read_csv, mock_detect_encoding):
        """Test loading iTunes data with missing columns."""
        # Setup mocks
        mock_detect_encoding.return_value = 'utf-8'
        mock_df = pd.DataFrame({
            'Name': ['Test Track (Original Mix)'],
            'Artist': ['Test Artist'],
            # Missing required columns
        })
        mock_read_csv.return_value = mock_df
        
        # Call function and verify it raises an error
        with pytest.raises(ValueError, match="Missing expected columns"):
            load_itunes_data(Path('dummy_path.txt'))

I’ll include the whole test suite in my GitHub repo. Let’s conclude with pytest‘s output:

Plaintext
collected 41 items                                                                                                                                        

tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_valid_track PASSED                                                                [  2%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_valid_track_boundary_values PASSED                                                [  4%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_name_no_parentheses PASSED                                                [  7%]
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_empty_name PASSED                                                                 [  9%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_empty_artist PASSED                                                               [ 12%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_empty_work PASSED                                                                 [ 14%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_empty_genre PASSED                                                                [ 17%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_album_not_camelot PASSED                                                  [ 19%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_valid_camelot_notations PASSED                                                    [ 21%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_bpm_range_high PASSED                                                     [ 24%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_bpm_range_low PASSED                                                      [ 26%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_year_range_early PASSED                                                   [ 29%]
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_year_range_future PASSED                                                  [ 31%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_rating_not_multiple PASSED                                                [ 34%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_rating_too_low PASSED                                                     [ 36%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_invalid_rating_too_high PASSED                                                    [ 39%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_null_track_number PASSED                                                          [ 41%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_null_year PASSED                                                                  [ 43%] 
tests/test_wolfie_exportvalidator_itunes.py::TestTrackModel::test_null_rating PASSED                                                                [ 46%]
tests/test_wolfie_exportvalidator_itunes.py::TestFileOperations::test_detect_file_encoding PASSED                                                   [ 48%] 
tests/test_wolfie_exportvalidator_itunes.py::TestFileOperations::test_detect_file_encoding_latin1 PASSED                                            [ 51%] 
tests/test_wolfie_exportvalidator_itunes.py::TestFileOperations::test_detect_file_encoding_no_result PASSED                                         [ 53%] 
tests/test_wolfie_exportvalidator_itunes.py::TestFileOperations::test_load_itunes_data_success PASSED                                               [ 56%]
tests/test_wolfie_exportvalidator_itunes.py::TestFileOperations::test_load_itunes_data_missing_columns PASSED                                       [ 58%] 
tests/test_wolfie_exportvalidator_itunes.py::TestFileOperations::test_load_itunes_data_empty_dataframe PASSED                                       [ 60%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_validate_tracks_all_valid PASSED                                                  [ 63%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_validate_tracks_with_errors PASSED                                                [ 65%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_duplicate_location PASSED                                                         [ 68%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_analyze_errors PASSED                                                             [ 70%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_analyze_errors_with_general_error PASSED                                          [ 73%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_write_error_report PASSED                                                         [ 75%]
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_process_file_with_errors PASSED                                                   [ 78%] 
tests/test_wolfie_exportvalidator_itunes.py::TestValidation::test_process_file_no_errors PASSED                                                     [ 80%]
tests/test_wolfie_exportvalidator_itunes.py::TestParamsData::test_bpm_range_valid PASSED                                                            [ 82%] 
tests/test_wolfie_exportvalidator_itunes.py::TestParamsData::test_year_range_valid PASSED                                                           [ 85%] 
tests/test_wolfie_exportvalidator_itunes.py::TestParamsData::test_rating_range_valid PASSED                                                         [ 87%] 
tests/test_wolfie_exportvalidator_itunes.py::TestParamsData::test_camelot_notations_valid PASSED                                                    [ 90%] 
tests/test_wolfie_exportvalidator_itunes.py::TestMain::test_main_with_files PASSED                                                                  [ 92%] 
tests/test_wolfie_exportvalidator_itunes.py::TestMain::test_main_no_files PASSED                                                                    [ 95%] 
tests/test_wolfie_exportvalidator_itunes.py::TestMain::test_main_with_exception PASSED                                                              [ 97%]
tests/test_wolfie_exportvalidator_itunes.py::TestMain::test_main_with_critical_exception PASSED                                                     [100%] 

=================================================================== 41 passed in 0.20s =================================================================== 

I had a very positive experience overall! Working with Amazon Q allowed me to write the tests more quickly than I could have done on my own. We would have been even faster if I had put more thought into my initial prompt. Additionally, since Q Developer offers a generous free tier, it didn’t cost me anything.

GitHub Repo

I have committed my Pydantic data validation script, test suite and documentation in the repo below:

GitHub-BannerSmall

Note that the parameters are decoupled from the Pydantic script. This will allow me to reuse some parameters across future validation scripts and has enabled me to exclude the system parameters from the repository.

Summery

In this post, I used the Pydantic Python library to create data validation and observability processes for my Project Wolfie iTunes data.

I found Pydantic very impressive! Its simplicity, functionality and interoperability make it an attractive addition to Python data pipelines, and its strong community support keeps Pydantic relevant and current. Additionally, Pydantic’s presence in FastAPI, PydanticAI and a managed AWS Lambda layer enables rapid integration and seamless deployment. I see many applications for it within Project Wolfie.

There’s lots more to Pydantic – this Pixegami video is a great walkthrough of Pydantic in action:

If this post has been useful then the button below has links for contact, socials, projects and sessions:

SharkLinkButton 1

Thanks for reading ~~^~~

Categories
Developing & Application Integration

Simplified Data Workflows With AWS Step Functions Variables

In this post, I use AWS Step Functions variables and JSONata to create a simplified API data capture workflow with Lambda and DynamoDB.

Introduction

I’ve become an AWS Step Functions convert in recent times. Back in 2020 when I first studied it for some AWS certifications, Step Functions defined workflows entirely in JSON, making it less approachable and often overlooked.

How times change! With 2021’s inclusion of a visual editor, Step Functions became far more accessible, helping it become a key tool in serverless application design. And in 2024 two major updates significantly enhanced Step Functions’ flexibility: JSONata support, which I recently explored, and built-in variables, which simplify state transitions and data management. This post focuses on the latter.

To demonstrate the power of Step Functions variables, I’ll walk through a practical example: fetching API data, verifying the response, and inserting it into DynamoDB. Firstly, I’ll examine the services and features I’ll use. Then I’ll create a state machine and examine each state’s use of variables. Finally, I’ll complete some test executions to ensure everything works as expected.

If a ‘simplified’ workflow seems hard to justify as a 20-minute read…that’s fair. But mastering Step Functions variables now can save hours of debugging and development in the long run! – Ed

Also, special thanks to AWS Community Builder Md. Mostafa Al Mahmud for generously providing AWS credits to support this and future posts!

Architecture

This section provides a top-level view of the architecture behind my simplified Step Functions variables workflow, highlighting the main AWS services involved in getting and processing API data. I’ll briefly cover the data being used, the role of Step Functions variables and the integration of DynamoDB within the workflow.

API Data

The data comes from a RESTful API that provides UK car details. The API needs both an authentication key and query parameters. Response data is provided in JSON.

The data used in this post is about my car. As some of it is sensitive, I will only use data that is already publicly available:

JSON
{
    "make": "FORD",
    "yearOfManufacture": 2014,
    "engineCapacity": 1242,
    "co2Emissions": 120,
    "fuelType": "PETROL",
    "markedForExport": false,
    "colour": "GREY",
}

There are several data types here. This will be important when writing to DynamoDB!

AWS Step Functions Variables

In my last post, I talked about JSONata in AWS Step Functions. This time let’s talk about Step Functions variables, which were introduced alongside JSONata in November 2024.

Step Functions variables offer a simple way to store and reuse data within a state machine, enabling dynamic workflows without complex transformations. They work well with both JSONata and JSONPath and are available at no extra cost in all AWS regions that support Step Functions.

Variables are set using Assign. They can be assigned static values for fixed values:

JSON
"Assign": {
    "productName": "product1",
    "count" : 42,
    "available" : true
}

As well as dynamic values for changing values. To dynamically set variables, Step Functions uses JSONata expressions within {% ... %}. The following example extracts productName and available from the state input using the JSONata $states reserved variable:

JSON
"Assign": {
    "product": "{% $states.input.productName %}",
    "available": "{% $states.input.available %}"
}

Variables are then referenced using dollar signs ($), e.g. $productName.

There’s tonnes more to this. For details on name syntax, ASL integration and creating JSONPath variables, check the Step Functions Developer Guide variables section. Additionally, watch AWS Principal Developer Advocate Eric Johnson‘s related video:

With Step Functions variables handling data transformation and persistence, the next step is storing processed data efficiently. This is where Amazon DynamoDB comes in.

Amazon DynamoDB

DynamoDB is a fully managed NoSQL database built for high performance and seamless scalability. Its flexible, schema-less design makes it perfect for storing and retrieving JSON-like data with minimal overhead.

DynamoDB can automatically scale to manage millions of requests per second while maintaining low latency. It integrates seamlessly with AWS services like Lambda and API Gateway, providing built-in security, automated backups, and global replication to ensure reliability at any scale.

Popular use cases include:

  • Serverless backends (paired with AWS Lambda/API Gateway) for API-driven apps.
  • Real-time workloads like user sessions, shopping carts, or live leaderboards.
  • High-velocity data streams from IoT devices or clickstream analytics.

Diagram

Finally, here is an architectural diagram of my simplified Step Functions variables workflow:

In which:

  1. The user triggers an AWS Step Functions state machine with a JSON key-value pair as input.
  2. A Lambda function is invoked with the input payload.
  3. The Lambda function sends a POST request to a third-party API.
  4. The API server responds with JSON data.
  5. The Lambda function assigns Step Functions variables to store API response values and enters a Choice state that checks the API response code.
  6. If the Choice state condition fails, SNS publishes a failure notification email.
  7. The state machine terminates with an ExecutionFailed status.
  8. If the Choice state condition passes, the processed API response data is written to a DynamoDB table.
  9. SNS publishes a success notification email.
  10. The state machine terminates with an ExecutionSucceeded status.

If an error occurs at any point in execution, SNS publishes a failure notification email and the state machine terminates with an ExecutionFailed status.

Resources

In this section, I create and configure my simplified Step Functions variables workflow resources, which are:

  • AWS Lambda function
  • AWS Step Functions Choice state
  • Amazon DynamoDB table
  • Amazon SNS topic

AWS Lambda

This section details how I created an AWS Lambda function to interact with a REST API. The function makes a secure POST request, manages potential errors and parses the response for use in downstream states. Additionally, I will discuss an issue I encountered while attempting to create variables from the function’s output using JSONata.

Lambda Function

First, I need to write a function. It’s nothing special – I have the API link and security key I need, and I just want to retrieve some data. So I decided to give Amazon Q Developer a try!

I used this prompt:

I have an HTTPS hyperlink for a REST API and an API key. I want to send a POST request to the API using the key. I have a USERID parameter that I will pass as JSON.

Please write a Python function for AWS Lambda with error handling. Please use security best practises and Pythonic standards.

Yes I do say Please in my prompts.

Amazon Q produced a decent script with:

  • API endpoint and key stored as environment variables.
  • Use of the requests module with a timeout to prevent indefinite hangs.
  • Error handling for request failures, validation errors, and unexpected issues.
  • A structured JSON response including the status code and parsed response.
Python
import json
import os
import logging
import requests
from typing import Dict, Any
from botocore.exceptions import ClientError

# Configure logging
logger = logging.getLogger()
logger.setLevel(logging.INFO)

def lambda_handler(event: Dict[str, Any], context: Any) -> Dict[str, Any]:
    """
    AWS Lambda function to make POST request to API endpoint
    Args:
        event: Lambda event object containing request data
        context: Lambda context object
    Returns:
        API response as dictionary
    """
    try:
        # Get API endpoint and key from environment variables
        api_endpoint = os.environ['API_ENDPOINT']
        api_key = os.environ['API_KEY']

        # Extract user ID from event
        user_id = event.get('userId')
        if not user_id:
            raise ValueError("userId is required in the request")

        # Set request headers
        headers = {
            'Content-Type': 'application/json',
            'x-api-key': api_key
        }

        # Prepare request payload
        payload = {
            'userId': user_id
        }

        # Make POST request
        response = requests.post(
            api_endpoint,
            headers=headers,
            json=payload,
            timeout=30  # Set timeout for the request
        )

        # Raise exception for bad status codes
        response.raise_for_status()

        return {
            'statusCode': response.status_code,
            'body': response.json()
        }

    except requests.exceptions.RequestException as e:
        logger.error(f"API request failed: {str(e)}")
        return {
            'statusCode': 500,
            'body': json.dumps({'error': 'Failed to make API request'})
        }

    except ValueError as e:
        logger.error(f"Validation error: {str(e)}")
        return {
            'statusCode': 400,
            'body': json.dumps({'error': str(e)})
        }

    except Exception as e:
        logger.error(f"Unexpected error: {str(e)}")
        return {
            'statusCode': 500,
            'body': json.dumps({'error': 'Internal server error'})
        }

It needed some tweaks for my purposes, but was still faster than typing it all out manually!

Step Functions Config

The Lambda: Invoke action defaults to using the state input as the payload, so "Payload": "{% $states.input %}" is scripted automatically:

JSON
    "Lambda Invoke": {
      "Type": "Task",
      "Resource": "arn:aws:states:::lambda:invoke",
      "Output": "{% $states.result.Payload %}",
      "Arguments": {
        "FunctionName": "[LAMBDA_ARN]:$LATEST",
        "Payload": "{% $states.input %}"
      },
      "Next": "Check API Status Code"
    }

This is going to be helpful in the next section!

Step Functions manages retries and error handling. If my Lambda function fails, it will retry up to three times with exponential backoff before sending a failure notification through SNS:

JSON
    "Lambda Invoke": {
      "Retry": [
        {
          "ErrorEquals": [
            "Lambda.ServiceException",
            "Lambda.AWSLambdaException",
            "Lambda.SdkClientException",
            "Lambda.TooManyRequestsException"
          ],
          "IntervalSeconds": 1,
          "MaxAttempts": 3,
          "BackoffRate": 2,
          "JitterStrategy": "FULL"
        }
      ],
      "Next": "Check API Status Code",
      "Catch": [
        {
          "ErrorEquals": [
            "States.ALL"
          ],
          "Next": "SNS Publish: Fail"
        }
      ]
    }

Next, let’s talk about the function’s outputs.

Outputs & JSONata Variables

The Lambda function returns a nested JSON structure. Here’s a redacted example of it:

JSON
{
  "output": {
    "ExecutedVersion": "$LATEST",
    "Payload": {
      "statusCode": 200,
      "body": {
        "make": "FORD",
        "yearOfManufacture": 2014,
        "engineCapacity": 1242,
        "co2Emissions": 120,
        "fuelType": "PETROL",
        "markedForExport": false,
        "colour": "GREY"
      }
    },
    "SdkHttpMetadata": {
      "AllHttpHeaders": {
        "REDACTED": "REDACTED"
      },
      "HttpHeaders": {
        "REDACTED": "REDACTED"
      },
      "HttpStatusCode": 200
    },
    "SdkResponseMetadata": {
      "REDACTED": "REDACTED"
    },
    "StatusCode": 200
  }
}

I mentioned earlier about Lambda: Invoke‘s default Payload setting. This default creates a {% $states.result.Payload %} JSONata expression output that I can use to assign variables for downstream states.

In this example, {% $states.result.Payload %} returns this:

JSON
{
  "Payload": {
      "statusCode": 200,
      "body": {
        "make": "FORD",
        "yearOfManufacture": 2014,
        "engineCapacity": 1242,
        "co2Emissions": 120,
        "fuelType": "PETROL",
        "markedForExport": false,
        "colour": "GREY"
      }
    }
}

Let’s make a variable for statusCode. In the response, statusCode is a property of Payload:

JSON
{
  "Payload": {
      "statusCode": 200
    }
}

In JSONata this is expressed as {% $states.result.Payload.statusCode %}. Then I can assign the JSONata expression to a statusCode variable via JSON. In the AWS console, I do this via:

JSON
{
  "statusCode": "{% $states.result.Payload.statusCode %}"
}

And in Step Functions ASL via:

JSON
"Assign": {"statusCode": "{% $states.result.Payload.statusCode %}"}

I can then call this variable using $statusCode. Here, this will return 200.

Next, let’s make a make variable. This is slightly more involved as make is a property of body, which is itself a property of Payload:

JSON
{
  "Payload": {
      "body": {
        "make": "FORD"
      }
    }
}

So this time I need:

JSON
CONSOLE:
"make": "{% $states.result.Payload.body.make%}"

ASL:
"Assign": {"make": "{% $states.result.Payload.body.make%}"}

And now $make will return "FORD".

So let’s do the other values:

JSON
"Assign": {
    "statusCode": "{% $states.result.Payload.statusCode %}",
    "make": "{% $states.result.Payload.body.make%}",
    "yearOfManufacture": "{% $string($states.result.Payload.body.yearOfManufacture) %}",
    "engineCapacity": "{% $string($states.result.Payload.body.engineCapacity) %}",
    "co2Emissions": "{% $string($states.result.Payload.body.co2Emissions) %}",
    "fuelType": "{% $states.result.Payload.body.fuelType %}",
    "markedForExport": "{% $states.result.Payload.body.markedForExport%}",
    "colour": "{% $states.result.Payload.body.colour%}"
}

Note that variables returning numbers from the response body like yearOfManufacture have an additional $string JSONata expression. I’ll explain the reason for this in the DynamoDB section.

Lambda Issues

When I first started using Step Functions variables, I used a different Lambda function for the API call and kept getting this error:

An error occurred.

The JSONata expression '$states.input.body.make' specified for the field 'Assign/make' returned nothing (undefined).

After getting myself confused, I checked the function’s return statement and found this:

Python
return {
    'statusCode': response.status_code,
    'body': response.text
}

Here, response.text returns the response body as a JSON-formatted string rather than as a nested dictionary:

Plaintext
{
  "statusCode": 200,
  "body": "{\"make\":\"FORD\",\"yearOfManufacture\":2014,\"engineCapacity\":1242,\"co2Emissions\":120,\"fuelType\":\"PETROL\",\"markedForExport\":false,\"colour\":\"GREY\"}"
}

That string isn’t compatible with dot notation. So while $states.input.body will match the whole body, $states.input.body.make can’t match anything because the string can’t be traversed. So nothing is returned, causing the error.

Using response.json() fixes this, as the response is now correctly structured for JSONata expressions:

Python
return {
    'statusCode': response.status_code,
    'body': response.json()
}

Choice State

The Choice state here is very similar to a previous one. This Choice state checks the Lambda function’s API response and routes accordingly.

Here, the Choice state uses the JSONata expression {% $statusCode = 200 %} to check the $statusCode variable value. By default, it will transition to the SNS Publish: Fail state. However, if $statusCode equals 200, then the Choice state will transition to the DynamoDB PutItem state instead:

JSON
    "Check API Status Code": {
      "Type": "Choice",
      "Choices": [
        {
          "Next": "DynamoDB PutItem",
          "Condition": "{% $statusCode = 200 %}"
        }
      ],
      "Default": "SNS Publish: Fail"
    }

This step prevents silent failures by ensuring unsuccessful API responses trigger an SNS notification instead of proceeding to DynamoDB. It also helps maintain data integrity by isolating success and failure paths, and ensuring only valid responses are saved in DynamoDB.

So now I’ve captured the data and confirmed its integrity. Next, let’s store it somewhere!

Amazon DynamoDB

It’s time to think about storing the API data. Enter DynamoDB! This section covers creating a table, writing data and integrating DynamoDB with AWS Step Functions and JSONata. I’ll share key lessons learned, especially about handling data types correctly.

Let’s start by creating a table.

Creating A Table

Before inserting data into DynamoDB, I need to create a table. Since DynamoDB is a schemaless database, all that is required to create a new table is a table name and a primary key. Naming the table is straightforward, so let’s focus on the key.

DynamoDB has two types of key:

  • Partition key (required): Part of the table’s primary key. It’s a hash value that is used to retrieve items from the table and allocate data across hosts for scalability and availability.
  • Sort key (optional): The second part of a table’s primary key. The sort key enables sorting or searching among all items sharing the same partition key.

Let’s look at an example using a Login table. In this table, the user ID serves as the partition key, while the login date acts as the sort key. This structure enables efficient lookups and sorting, allowing quick retrieval of a user’s login history while minimizing operational overhead.

To use a physical analogy, consider the DynamoDB table as a filing cabinet, the Partition key as a drawer, and the Sort key as a folder. If I wanted to retrieve User 123‘s logins for 2025, I would:

  • Access the Logins filing cabinet (DynamoDB table).
  • Find User 123’s drawer (Partition Key).
  • Get User 123’s 2025 folder (Sort Key).

DynamoDB provides many features beyond those discussed here. For the latest features, please refer to the Amazon DynamoDB Developer Guide.

Writing Data

So now I have a table, how do I put data in it?

DynamoDB offers several ways to write data, and a common one is PutItem. This lets me insert or replace an item in my table. Here’s a basic example of adding a login event to a UserLogins table:

JSON
{
    "TableName": "UserLogins",
    "Item": {
        "UserID": { "S": "123" },
        "LoginDate": { "S": "2025-02-25T12:00:00Z" },
        "Device": { "S": "Laptop" }
    }
}

Here:

  • TableName specifies the name of the DynamoDB table where the item will be stored.
  • Item represents the data being inserted into the table. It contains key-value pairs, where the attributes (e.g. UserID) are mapped to their corresponding data types (e.g. "S") and values (e.g. "123").
  • UserID is an attribute in the item being inserted.
  • "S" is a data type descriptor, ensuring that DynamoDB knows how to store and index it.
  • "123" is the value assigned to the UserID attribute.

While DynamoDB is NoSQL, it still enforces strict data types and naming rules to ensure consistency. These are detailed in the DynamoDB Developer Guide, but here’s a quick rundown of supported data types as of March 2025:

  • S – String
  • N – Number
  • B – Binary
  • BOOL – Boolean
  • NULL – Null
  • M – Map
  • L – List
  • SS – String Set
  • NS – Number Set
  • BS – Binary Set

Step Functions Config

So how do I apply this to Step Functions? Well, remember when I set variables in the output of the Lambda function? Step Functions lets me reference those variables here.

Here’s how I store a make attribute in DynamoDB, using my $make variable in a JSONata expression:

JSON
{
    "TableName": "REDACTED",
    "Item": {
        "make": { "S": "{% $make %}" }
    }
}

This is equivalent to:

JSON
{
    "TableName": "REDACTED",
    "Item": {
        "make": { "S": "FORD" }
    }
}

Using JSONata, I can dynamically inject values during execution instead of hardcoding them.

Now let’s add a yearOfManufacture attribute:

JSON
{
    "TableName": "REDACTED",
    "Item": {
        "make": { "S": "{% $make %}" },
        "yearOfManufacture": { "N": "{% $yearOfManufacture %}" }
    }
}

This pattern continues for my other attributes:

JSON
{
  "TableName": "REDACTED",
  "Item": {
    "make": {
      "S": "{% $make %}"
    },
    "yearOfManufacture": {
      "N": "{% $yearOfManufacture%}"
    },
    "engineCapacity": {
      "N": "{% $engineCapacity %}"
    },
    "co2Emissions": {
      "N": "{% $co2Emissions%}"
    },
    "fuelType": {
      "S": "{% $fuelType %}"
    },
    "markedForExport": {
      "BOOL": "{% $markedForExport %}"
    },
    "colour": {
      "S": "{% $colour %}"
    }
  }
}

All this is then passed as an Argument to the DynamoDB: PutItem action in the state machine’s ASL:

JSON
    "DynamoDB PutItem": {
      "Type": "Task",
      "Resource": "arn:aws:states:::dynamodb:putItem",
      "Arguments": {
        "TableName": "REDACTED",
        "Item": {
          "make": {
            "S": "{% $make %}"
          },
          "yearOfManufacture": {
            "N": "{% $yearOfManufacture%}"
          },
          "engineCapacity": {
            "N": "{% $engineCapacity %}"
          },
          "co2Emissions": {
            "N": "{% $co2Emissions%}"
          },
          "fuelType": {
            "S": "{% $fuelType %}"
          },
          "markedForExport": {
            "BOOL": "{% $markedForExport %}"
          },
          "colour": {
            "S": "{% $colour %}"
          }
        }
      }

Finally, DynamoDB:PutAction gets the same error handling as Lambda:Invoke.

So I got all this working first time, right? Well…

DynamoDB Issues

During my first attempts, I got this error:

An error occurred while executing the state 'DynamoDB PutItem'.

The Parameters '{"TableName":"REDACTED","Item":{"make":{"S":"FORD"},"yearOfManufacture":{"N":2014}}}' could not be used to start the Task:

[The value for the field 'N' must be a STRING]

Ok. Not the first time I’ve seen data type problems. I’ll just change the yearOfManufacture data type to "S"(string) and try again…

An error occurred while executing the state 'DynamoDB PutItem'.

The Parameters '{"TableName":"REDACTED","Item":{"make":{"S":"FORD"},"yearOfManufacture":{"S":2014}}}' could not be used to start the Task:

[The value for the field 'S' must be a STRING]

DynamoDB rejected both approaches (╯°□°)╯︵ ┻━┻

The issue wasn’t the data type, but how it was formatted. DynamoDB treats numbers as strings in its JSON-like structure, so even when using numbers they must be wrapped in quotes.

In the case of yearOfManufacture, where I was providing 2014:

Plaintext
"yearOfManufacture": {"N": 2014}

DynamoDB needed "2014":

Plaintext
"yearOfManufacture": {"N": "2014"}

Thankfully, JSONata came to the rescue again! Remember the $string function from the Lambda section? Well, $string casts the given argument to a string!

So this:

JSON
"yearOfManufacture": "{% $states.result.Payload.body.yearOfManufacture %}"

> 2014

Becomes this:

JSON
"yearOfManufacture": "{% $string($states.result.Payload.body.yearOfManufacture) %}"

> "2014"

This solved the problem with no Lambda function changes or additional states!

Amazon SNS

After successfully writing data to DynamoDB, I want to include a confirmation step by sending a notification through Amazon SNS.

While this approach is not recommended for high-volume use cases because of potential costs and notification fatigue, it can be helpful for testing, monitoring, and debugging. Additionally, it offers an opportunity to reuse variables from previous states and dynamically format a message using JSONata.

The goal is to send an email notification like this:

A 2014 GREY FORD has been added to DynamoDB on (current date and time)

To do this, I’ll use:

  • $yearOfManufacture for the vehicle’s year (2014)
  • $colour for the vehicle’s colour (GREY)
  • $make for the manufacturer (FORD)

Plus the JSONata $now() function for the current date and time. This generates a UTC timestamp in ISO 8601-compatible format and returns it as a string. E.g. "2025-02-25T19:12:59.152Z"

So the code will look something like:

A $yearOfManufacture $colour $make has been added to DynamoDB on $now()

Which translates to this JSONata expression:

Plaintext
{% 'A ' & $yearOfManufacture & ' ' & $colour & ' ' & $make & ' has been added to DynamoDB on ' & $now() %}

Let’s analyse each part of the JSONata expression to understand how it builds the final message:

Plaintext
{%

  'A '
& 
  $yearOfManufacture 
& 
  ' ' 
& 
  $colour 
& 
  ' ' 
& 
  $make 
& 
  ' has been added to DynamoDB on ' 
& 
  $now() 
  
%}"

Each part of this expression plays a specific role:

  • ‘A ‘ | ‘ has been added to DynamoDB on ‘: Static strings & spaces.
  • $yearOfManufacture | $colour | $make: Dynamic values.
  • $now(): JSONata function.
  • ‘ ‘: Static spaces to separate JSONata variable outputs.

The static spaces are important! Without them, I’d get this:

2014GREYFORD

Instead of the expected:

2014 GREY FORD

This JSONata expression is passed as the Message argument in the SNS:Publish action, ensuring the notification contains the correctly formatted message:

JSON
"Message": "{% 'A ' & $yearOfManufacture & ' ' & $colour & ' ' & $make & ' has been added to DynamoDB on ' & $now() %}"

Finally, to integrate this with Step Functions it is included in the SNS Publish: Success task ASL:

JSON
"SNS Publish: Success": {
    "Type": "Task",
    "Resource": "arn:aws:states:::sns:publish",
    "Arguments": {
      "Message": "{% 'A ' & $yearOfManufacture & ' ' & $colour & ' ' & $make & ' has been added to DynamoDB on ' & $now() %}",
      "TopicArn": "arn:aws:sns:REDACTED:success-stepfunction"
}

Final Workflow

Finally, let’s see what the workflows look like. Here’s the workflow graph:

stepfunctions graph

And here’s the workflow ASL on GitHub.

Testing

In this section, I run some test executions against my simplified Step Functions workflow and check the variables. I’ll test four requests – two valid and two invalid.

Valid Request: Ford

Firstly, what happens when a valid API request is made and everything works as expected?

The Step Functions execution succeeds:

stepfunctions graph testsuccess

Each state completes successfully:

2025 02 26 StateViewSuccess

My DynamoDB table now contains one item:

2025 02 26 DyDBTable1

I receive a confirmation email from SNS:

2025 02 26 SNSSuccessFord

If I send the same request again, the existing DynamoDB item is overwritten because the primary key remains the same.

Valid Request: Audi

Next, what happens if I make a valid request for a different car? The steps repeat as above, and my DynamoDB table now has two items:

2025 02 26 DyDBTable2

And I get a different email:

2025 02 26 SNSSuccessAudi

Invalid Request

Next, what happens if the car in my request doesn’t exist? Well, it does fail, but in an unexpected way:

stepfunctions graphfail

The API returns an error response:

JSON
"Payload": {
      "statusCode": 500,
      "body": "{\"error\": \"API request failed: 400 Client Error: Bad Request for url"}"
    }

I’d expected the response to be passed to the Choice state, which would then notice the 500 status code and start the Fail process. But this happened instead:

2025 02 26 StateViewFail

The failure occurs at the assignment of the Lambda action variable! It attempts to assign a yearOfManufacture value from the API response body to a variable, but since there is no response body the assignment fails:

JSON
{
  "cause": "An error occurred while executing the state 'Lambda Invoke' (entered at the event id #2). The JSONata expression '$states.result.Payload.body.yearOfManufacture ' specified for the field 'Assign/yearOfManufacture ' returned nothing (undefined).",
  "error": "States.QueryEvaluationError",
  "location": "Assign/registrationNumber",
  "state": "Lambda Invoke"
}

I also get an email, but this one is less fancy as it just dumps the whole output:

2025 02 26 SNSFail

So I still get my Fail outcome – just not in the expected way. Despite this, the Choice state remains valuable for preventing invalid data from entering DynamoDB.

No Request

Finally, what happens if no data is passed to the state machine at all?

Actually, this situation is very similar to the invalid request! There’s a different error message in the log:

JSON
"Payload": {
      "statusCode": 400,
      "body": "{\"error\": \"Registration number not provided\"}"
    }

But otherwise it’s the same events and outcome. The Lambda variable assignment fails, triggering an SNS email and an ExecutionFailed result.

Cost Analysis

This section examines the costs of my simplified Step Functions variables workflow. This section is brief since all services used in this workflow fall within the AWS Free Tier! For transparency, I’ll include my billing metrics for the month. These are account-wide, and I’m still nowhere near paying AWS anything!

DynamoDB:

$0.1415 per million read request units (EU (Ireland))30.5 ReadRequestUnits
$0.705 per million write request units (EU (Ireland))13 WriteRequestUnits

Lambda:

AWS Lambda – Compute Free Tier – 400,000 GB-Seconds – EU (Ireland)76.219 Second
AWS Lambda – Requests Free Tier – 1,000,000 Requests – EU (Ireland)110 Request

SNS:

First 1,000 Amazon SNS Email/Email-JSON Notifications per month are free19 Notifications
First 1,000,000 Amazon SNS API Requests per month are free289 Requests

Step Functions:

$0 for first 4,000 state transitions431 StateTransitions

This experiment demonstrates how cost-effective Step Functions can be. As long as my usage remains within the Free Tier, I pay nothing! If my workflow grows, I’ll monitor costs and optimise accordingly.

Summary

In this post, I used AWS Step Functions variables and JSONata to create a simplified API data capture workflow with Lambda and DynamoDB.

With a background in SQL and Python, I’m no stranger to variables, and I love that they’re now a native part of Step Functions. AWS keeps enhancing Step Functions every few months, making it more powerful and versatile. The introduction of variables unlocks new possibilities for data manipulation, serverless applications and event-driven workflows, and I’m excited to explore them further in the coming months!

For a visual walkthrough of Step Functions variables and JSONata, check out this Serverless Office Hours episode with AWS Principal Developer Advocates Eric Johnson and Julian Wood:

If this post has been useful then the button below has links for contact, socials, projects and sessions:

SharkLinkButton 1

Thanks for reading ~~^~~