Categories
Data & Analytics

Building An AWS Garmin Data Pipeline For My Charity Marathon

I’m running the Chester Marathon for charity to support Pendleside Hospice! In this post, I build an AWS data pipeline to analyse my Garmin training data.

Introduction

Outside of my AWS and community work, I have several hobbies – one of which is running. I was a big running fan in the 2010s, and after a few years away I got back into it in 2025. I’ve had a pretty decent 18 months with it, and this summer I decided to check off one of my bucket list items by running a marathon for charity.

A side effect of my marathon training has been an influx of training data. While I already have access to platforms like Garmin Connect and FetchEveryone to analyse this data, neither platform quite gives me the full picture I want. My choices were to either pay Garmin for enhanced features or build an AWS Garmin data pipeline. And I’m not one to turn down a good data project!

Firstly, I’ll cover how the data is generated and collected. Then I’ll walk through the three-account AWS architecture that turns the raw files into data a Bedrock agent can analyse. Finally, I’ll cover what that agent actually found after I pointed it at my training data.

Future posts will examine the backend behind each pipeline stage. This one’s about the shape of the whole pipeline and the race it was built for. Let’s begin by looking at my chosen charity.

The Charity

Pendleside Hospice is a registered charity based in Burnley. Founded in 1988, they provide palliative and end-of-life care for people across Burnley, Pendle and Rossendale. They originally focused on cancer care, but now support people with a wider range of life-limiting conditions, including dementia, respiratory and neurological illnesses.

Pendleside have cared for a good friend of mine. Martine Hamer worked alongside her husband Russell at his Burnley salon. Russell’s been cutting my hair for over two decades, and Martine was the one who mixed the bleach, ran the hairdryers and occasionally talked me into a spray tan. After her short battle with breast cancer, she died in Pendleside’s care in February 2010, aged just 35.

MartineHamer

Pendleside cares for over 1,700 people every year across a 10-bed inpatient unit, a Hospice at Home service, day therapy and bereavement support for families and children. They also run a Meals on Wheels service and a Health, Wellbeing & Rehabilitation programme that offers services such as physiotherapy and counselling.

Operating Pendleside requires over £4.5 million a year. An NHS grant covers around 20% of that, leaving over £3.5 million to be raised each year locally through events, their charity shops and donations.

I’ve fundraised for Pendleside before, doing the 2010 Bupa Manchester 10k for them. But there was always something else in the back of my mind…

The Marathon

I’ve thought about running a marathon for charity several times over the years, but never felt right doing it when I was frequently running a couple of them a year. After all, if I was doing that many, where was the challenge? Having had an extended break and several life changes, 2026 feels like the ideal time to give it a go.

While this is my first charity marathon and my first one for a while, it’s not my first marathon. That honour falls to the wet, windy 2012 Manchester Marathon, which still lives in infamy in the minds of those who took part.

Amazingly, I came back for more after this! In the following years, I ran various marathons, including locally in Manchester and in the capital, through vineyards at the Marathon du Médoc and around a running track at the Groundhog Marathon.

MBNA Chester Marathon 5983006 121918 Finish 600

This came to a stop, like many things, during the 2020 pandemic. Running then took a back seat for a few years until I got back into it in 2025 after joining the Steamhaus Vitality scheme. Fast forward 18 months, and I find myself with an entry for the 2026 Chester Marathon and the opportunity to finally fundraise for Pendleside.

I’ve done Chester twice before, in 2013 and 2019. There are a few reasons for choosing it for my 14th marathon:

  • Chester is a lovely city, and the route is fantastic and well supported.
  • The Active Leisure team is a great event organiser with over a decade of experience.
  • The last running event I did pre-pandemic was the 2020 Chester 10k. So spiritually, this feels like I’m picking up where I left off.

If you’d like to support Pendleside Hospice, you can do so through my JustGiving page.

Data Collection

In this section, I’ll explain where the Garmin data in the AWS pipeline comes from: what captures it, what’s actually captured and the format it arrives in.

Device

My current watch is a Garmin Forerunner 745, a mid-range running and triathlon watch that sits between the Forerunner 645 and the Forerunner 945. It tracks everything I need for marathon training: GPS position, heart rate, pace and cadence. It also has a pulse oximeter for blood oxygen, a barometric altimeter and onboard training load and recovery metrics.

Upon completion, activities are uploaded to Garmin Connect via my phone’s Bluetooth.

Garmin Connect

Garmin Connect is the companion platform for data collected by Garmin devices. Activity, health and training data are automatically uploaded here after device syncing. Garmin then turns this data into various reports, visuals and feedback. These can range from the pace and heart rate zones of individual activities to aggregated training loads and historical mileage.

Garmin Connect hero image 1480x975

Crucially for this project, it also lets me download the data in various formats, including the raw FIT files that everything else in this pipeline depends on.

FIT Files

Flexible and Interoperable Data Transfer (FIT) is the file format Garmin devices use to record and share activity data.

Rather than storing one big block of numbers, a FIT file is built from streams of timestamped messages. These capture the same GPS, heart rate and cadence data as the watch itself, plus other data like power and speed, all streamed as the activity happens rather than saved as a single summary.

It’s compact and self-describing by design, making it ideal for Garmin Connect and other training platforms like Strava, TrainingPeaks and FetchEveryone.

Architecture

This section examines the multi-account architecture of the AWS Garmin FIT data pipeline. I discuss the concept of a multi-account strategy and its benefits, then examine each account’s role in the data pipeline.

Multi-Account

Before getting into what each account actually does, it’s worth explaining why this pipeline is split across multiple accounts in the first place.

Multi-Account Strategy

A multi-account strategy is the practice of splitting workloads, environments and admin boundaries across multiple AWS accounts. Each account has a specific, well-defined role, rather than relying on IAM policies or resource tagging for separation inside a single account.

Where a single account relies on carefully maintained policies to keep teams, systems and environments separate, a multi-account strategy makes that separation structural. Each account becomes its own hard boundary instead of a policy-enforced one.

The strategy typically extends beyond individual workloads to environments, products and business areas, and is usually managed centrally through AWS Organizations.

But why bother? What benefits does a multi-account setup offer?

Multi-Account Benefits

AWS has a white paper on this – Organizing Your AWS Environment Using Multiple Accounts. And while it’s aimed at enterprise customers, many of the benefits it covers apply just as well to my multi-account AWS Garmin data pipeline architecture.

Data Access Controls: I’ve worked with data for many years, and ensuring the right data is in the right place and accessible to the right people is a common challenge. AWS accounts are ideal boundaries to resolve this, offering strict access controls and enforcing one-way data flow at the account level. This means, for example, that a Lakehouse process can never overwrite raw data in the Data Lake, and an AI process can only read Lakehouse data that’s been cleansed and curated.

Blast Radius Limitation: Things break, and things fail. When that happens and everything lives in the same account, it can be disastrous. A multi-account setup has inherent boundaries that limit the scope of adverse events such as misconfigurations, compromised credentials or bad deployments.

Grouping By Purpose: Splitting workloads into separate accounts means I can manage them on their own terms without creating unnecessary or unintended dependencies. This separation also ringfences each account’s use of services, quotas and billing, making scaling up far simpler.

Pipeline Accounts

This section reviews each AWS account of the Garmin data pipeline. First is the Data Lake account, where raw data lands and is stored. Next is the Lakehouse account, which cleanses and curates the data. Finally is the AIML account, which analyses the curated data for insights.

Data Lake Account

This account is a landing zone. Its main job is to capture and store raw data and grant read-only cross-account access to it.

It currently holds two S3 buckets: one for sensitive data and a general-purpose one for everything else. Data here is version-controlled, immutable and easy to locate and back up. Data is currently added manually, but over time this will expand to include ingestion scripts that pull data from third parties, as well as automated pushes from agents and IoT sensors.

Lakehouse Account

This account transforms and serves data. It owns the ELT pipeline, the transformed data storage, the Glue Data Catalog and the Athena workgroup. The Lakehouse has Cleansed, Curated and Semantic layers, with further separation for sensitive and general data classifications.

While the Lakehouse account can access both Data Lake buckets, access is scoped per process rather than granted fully. The AWS Garmin data pipeline’s ELT processes can only access the general bucket, as they don’t need anything from the sensitive one. The AIML account’s access works on the same principle of least privilege, using a separate cross-account role scoped to a single Glue database, S3 prefix and Athena workgroup.

AIML Account

This account consumes data from the Lakehouse account for GenAI processes. It owns a Bedrock agent, two Lambda functions and its own S3 buckets for query results and generated output.

The AIML account queries data in the Lakehouse account through its Glue Data Catalog. It has no access to the Data Lake account and cannot read data that has not already passed through the Cleansed and Curated Lakehouse layers. This ensures the agent uses only validated, trusted data.

Processes

This section covers what actually happens at each stage of my AWS Garmin data pipeline: the triggers, the hand-offs and the grants the accounts use to interact with each other.

There are three AWS accounts in the Garmin data pipeline, each of which owns separate processes:

CharityBlog AWSAccounts.drawio
  • Data landing and storage in the Data Lake account.
  • Data cleansing and curation in the Lakehouse account.
  • Analytics and report generation in the AIML account.

Data Lake Account

data lake storage account architecture dark

Garmin data as FIT files enters the raw-general S3 bucket by manual upload. The account then answers read requests from the Lakehouse’s Cleansed ELT Lambda, granted via bucket policy. There is no processing, no deletion and no outbound calls initiated from this account.

Lakehouse Account

lakehouse account architecture

The Lakehouse account owns two distinct processes:

  • The Cleansed process, which converts the raw FIT files into readable Parquet data.
  • The Curated process, which validates the data and derives new columns to add value.

Cleansed Process

garmin cleansed pipeline stepfunctions graph

An EventBridge Scheduler runs a cron trigger every day at 06:00 UTC, which starts a Step Function. In the first step of this execution, an S3 List step reads the contents of the Garmin folder in the Data Lake account’s raw-general S3 bucket.

Next, the Cleansed Filter Lambda checks each FIT object against those already processed and passes along the unprocessed ones. Then a Map state fans out across these objects, running the Cleansed ELT Lambda once per object with a maximum concurrency of ten.

Each ELT invocation pulls its FIT file directly from the Data Lake account, using bucket-policy-granted access on the Lambda’s execution role. It then decompresses the file and parses the FIT binary with garmin-fit-sdk.

From there, it converts FIT epoch timestamps into standard datetimes and semicircle coordinates into decimal-degree latitude and longitude, then writes the results as Parquet files to the Cleansed bucket. 21 tables are written per activity, with partitions and table schemas registered or updated in the Glue Data Catalog.

Curated Process

garmin curated pipeline stepfunctions graph

When the Cleansed Step Functions execution succeeds, an EventBridge Rule triggers a second state machine for the Curate process.

In the first step of this execution, a Curated Filter Lambda identifies activities that have not yet been promoted by checking whether curated output already exists. Then a Choice state checks if everything is up to date. If it is, no further action is taken. If not, a Map state fans out across the unprocessed files, invoking the Curated Promote Lambda for each activity with a maximum concurrency of ten.

Each Curated Promote Lambda invocation reads its assigned Cleansed Parquet file for all 21 tables and computes derived features on the records table: elapsed seconds, cumulative distance, grade percentage, pace (min/km) and heart-rate zone. It then validates every table row against a corresponding Pydantic schema and writes valid rows to the Curated bucket. The Curated tables are registered in a separate Glue database.

Reliability & Access

Idempotency is handled at multiple points in both processes:

  • The Cleansed Filter Lambda won’t include a file in the Map state if its output already exists.
  • Cleansed ELT Lambda invocations perform their own HeadObject check before writing, in case two invocations race each other.
  • Curated Filter and Promote Lambdas apply the same output-exists pattern against the Curated bucket.

Additionally, CloudWatch alarms trigger if any Lambda invocation errors out.

Once the Curated tables are registered, the AIML account can query them via Athena. A cross-account GarminDataCrossAccountReadRole IAM role is assumable by the AIML account’s Garmin Agent Lambda, and grants the following:

  • Read access to the Curated Glue database.
  • Read access to the S3 prefix where those tables live.
  • Use of a dedicated garmin-agent-queries Athena workgroup with an enforced output location.

Results land in a separate athena-results S3 bucket in the Lakehouse account, kept apart from the process’s own working buckets.

AIML Account

aiml account garmin agent architecture

Two separate flows run here. In the interactive flow, a user prompt is sent to the marathon-training-analyst Bedrock Agent, running on Claude Sonnet. The agent interprets it and calls one of six endpoints in the query Lambda’s action group depending on the prompt, covering topics such as training summaries, activity details, heart rate trends and pace trends.

The Query Lambda then assumes GarminDataCrossAccountReadRole in the Lakehouse account via AWS STS and runs an Athena query against the Curated Glue database, scoped to the garmin-agent-queries Athena workgroup. It converts the raw metrics (m/s to min/km pace, metres to km, seconds to H:MM:SS) and returns structured results to the agent, which formats a natural-language response.

In the batch flow, the Orchestrator Lambda calls the same agent with a comprehensive analysis prompt that explores topics such as volume progression, pace trends and race predictions. It collects the agent’s streamed multi-step reasoning and query results, combines them into a Markdown document, and writes the finished output to the genai-results bucket where it’s picked up for personal use.

AIML Agent Prompt

For completeness, I wanted to briefly discuss the marathon-training-analyst agent’s prompt. I won’t include the full prompt here for two reasons:

  • It’s been superseded by a newer version, which I’ll discuss later.
  • The prompt is over 220 words long, so focused sections will be easier to follow than the whole.

So here is an abridged version of what the agent gets when the batch flow runs. I’ve removed some of each section’s bullets – the remaining text is unaltered:

“You are an expert marathon running coach and sports data analyst. You have access to a runner’s Garmin training data and your job is to analyse their marathon preparation.

When analysing training data:

  • Calculate and interpret weekly mileage progression, noting appropriate buildup and recovery weeks
  • Identify injury risk factors: sudden volume spikes (>10% week-over-week), insufficient rest days
  • Provide race day predictions using established methods (Jack Daniels formula, pace-based estimates)

When producing output:

  • Lead with key insights, support with specific numbers from the data
  • Use markdown formatting with headers, bullet points, and emphasis
  • Include specific dates, distances (in km), paces (min/km), and heart rates where relevant

Always query the data before making claims. Do not hallucinate metrics — use only what the data shows.
Garmin speeds are in m/s — convert to min/km for display (pace = 1000/60 / speed_m_s).
Distances in the data are in metres — convert to kilometres for display.”

Isn’t This All Overkill?

A fair question to end on. And yes – this would be total overkill if all I was planning to do with this was the Garmin analysis.

But each of these accounts has more work ahead of it. There will be new ingestion processes in the Data Lake account, new databases in the Lakehouse account and new agents in the AIML account. Indeed, this exact framework will now be receiving Project Wolfie data in the coming months!

The intention behind this architecture is to build something I can use long-term. While it may seem like a lot of work and resources for such a small project, the more time I spend on it now, the more likely it is to support my future requirements.

And that’s the AWS Garmin data pipeline! Three accounts and a lot of careful plumbing, taking raw FIT files and transforming them into queryable data. So what did those 28 weeks of training data actually say?

Tests & Insights

In this section, I’ll go through what the Bedrock agent found when it analysed my Curated dataset generated by my AWS Garmin data pipeline, covering 28 weeks and 66 running activities totalling 573 km.

A brief caveat. These findings are from a version of the agent that has since had some tweaks and changes. These findings remain valid, and I’ll explore the agent’s changes in future posts.

Let’s start with pace trends. This is how pace and heart rate interact across different types of runs. This is important because pace alone isn’t the whole story.

Running at a certain speed with a low heart rate is a very different signal from running at the same speed with a high one, and comparing the two over time is one of the clearest ways to see whether training effort is being optimally controlled. Two of the most suitable run types for this analysis are easy runs and quality sessions.

Easy runs are deliberately slow, low-effort miles that build an aerobic engine without piling on fatigue. The goal here isn’t speed – it’s staying comfortable enough to hold a conversation. The heart rate range that keeps a run ‘easy’ is often called Zone 2, calculated in my case via Heart Rate Reserve rather than straight % max, at roughly 60-70% of HRR. For me, this currently falls somewhere between 145 and 165 BPM.

Quality sessions are structured, harder efforts such as tempo runs or threshold work. These target a specific pace range to build speed and the ability to sustain effort under fatigue.

Pace Findings

The Bedrock agent reported that the easy runs were suitably paced. The bulk of the shorter runs fell in the 5:15-5:35/km range at 145-165 BPM, comfortably within the Zone 2 window. For example:

  • On 17 January, I ran 6.85 km at 5:19 pace and 147 BPM.
  • 08 May: 5.7 km at 5:33 pace and 149 BPM.
  • 17 June: 5.6 km at 5:31 pace and 147 BPM.

Across the 28 weeks, easy days stayed easy – exactly what they’re supposed to be.

Pace Concerns

Bedrock flagged some inconsistencies across quality sessions. Four key tempo efforts sat in a tight 10-second pace band (4:46/km-4:56/km), but their average heart rates ranged from 161-177 BPM. This is a 16 BPM spread for nearly identical effort outputs.

The agent saw that spike as either a sudden loss of aerobic fitness or poor effort control. In reality, that spread was driven mostly by this summer’s heatwaves, during which thermal stress artificially elevated my heart rate.

This highlights a gap in my initial dataset. Because FIT files don’t record ambient weather, Bedrock was analysing telemetry with insufficient context. Ingesting weather API data into the pipeline could resolve this in future analysis.

Volume Progression

Next, volume progression: the increasing weekly mileage a training plan builds toward race day. This is the main way to build endurance…and also a frequent cause of injury! Push the weekly total up too slowly, and marathon day will arrive without a sufficient endurance base. Push it too fast, and the body doesn’t have time to adapt to the added load.

Volume Findings

The Bedrock agent reported that my Garmin dataset shows textbook periodisation. A gradual climb with deliberate peaks and recovery weeks placed where they were needed. The buildup from 16.94 km in the week of 1 February to 37.63 km in the week of 27 April took 12 weeks, which is an acceptable progression.

Recovery weeks were also well-scheduled. The week of 4 May dropped to 27.8 km (-26%) straight after the 37.63 km peak, and the week of 1 June dropped again to 25.35 km (-40%) after a second peak of 41.93 km. That second recovery week came right before one of the training block’s biggest pushes: 47.13 km in the week of 8 June, a 12.4% rise from the 25 May peak.

Volume Concerns

For volume progression, a commonly cited guardrail is the 10% rule: don’t increase weekly mileage by more than about 10% from one week to the next. The analysis found that two weeks broke this rule.

The week of 27 April saw a 66% jump from 22.66 km to 37.63 km. The week of 8 June went further, up 86% from the previous week’s 25.35 km to 47.13 km. Both are the kind of single-week spike that usually precedes an injury. The recovery weeks before each spike mitigated some of the risk, but it’s not something to make a habit of!

Race Prediction

Bedrock modelled my estimated marathon time three separate ways:

Method 1: Training Pace Analysis

This method works backwards from recent hard efforts. Firstly, identify the pace I can hold at lactate threshold. Then apply the well-established rule that marathon pace is roughly 8-10% slower than threshold pace, since race effort must be sustained for hours rather than minutes.

Recent quality sessions:

  • 30 April: 8.18 km at 4:54/km, 170 BPM (threshold)
  • 17 May: 22.54 km at 5:06/km, 169 BPM (marathon pace simulation)
  • 11 July: 9.84 km at 4:56/km, 177 BPM (near-threshold)

Bedrock estimate: These paces suggest:

  • Threshold pace: ~4:54-4:56/km
  • Marathon pace (8-10% slower than threshold): 5:18-5:26/km
  • Predicted finish: 3:43-3:49

Method 2: Heart Rate Efficiency Model

This method uses heart rate rather than pace as the anchor: it looks at what percentage of max heart rate can be sustained over a race-length effort, then finds the pace that sits in that same effort zone across the full marathon distance.

I can currently sustain 5:04/km at 170 BPM for 32.22 km. Given:

  • Max HR appears to be 193-196 BPM.
  • 170 BPM = ~87-88% max HR (solid marathon effort zone).
  • Cardiac drift is minimal on long runs.

Conservative marathon pace: 5:20-5:25/km at ~170 BPM.

Predicted finish: 3:45-3:49

Method 3: Jack Daniels VDOT

VDOT is a single number that Jack Daniels’ running formula uses to represent overall running fitness. It combines aerobic capacity (VO2max) with running economy (how efficiently oxygen is used) into one score derived from an actual race performance. That score is then used to predict equivalent times at other distances.

The 22.54 km at 5:06/km (1:54:59) suggests a VDOT of approximately 39-41.

  • VDOT 40: Predicted finish = 3:49:45
  • VDOT 41: Predicted finish = 3:45:00

Consensus Prediction

All things considered, Bedrock currently estimates my finish time at 3:45-3:49 (5:18-5:26/km), basing this on:

  • Peak long run of 32.22 km demonstrating distance readiness.
  • Easy runs were reliably held within the Zone 2 range, indicating well-controlled training intensity.
  • Recent quality work (11 July at 4:56/km) showing retained speed.
  • Total volume of 573 km over 28 weeks is solid marathon preparation.
  • Long runs executed at appropriate aerobic effort.

Personally, this feels optimistic. I was targeting closer to four hours, and my Garmin currently estimates a marathon time of 3:57. But this isn’t a short race – minutes of drift in estimates are common in endurance events like the marathon.

Bedrock sensibly includes caveats in its analysis. The race outcome heavily depends on factors including:

  • Weather conditions: Heat, rain and wind all significantly impact performance.
  • Pacing discipline: Going too fast in the first half will burn energy needed for the second half.
  • Nutrition and hydration: Strategy in the week of the event and on the day matters just as much as fuelling during the race itself.
  • Taper quality: Tapering too soon or too late can affect marathon readiness.

Summary

This project started as a way to make additional use of my Garmin training data, and became a three-account AWS data pipeline: raw FIT files landing in the Data Lake account, being cleansed and curated in the Lakehouse account and then handed to a Bedrock agent in the AIML account for analysis. Along the way, that agent told me things about my training I hadn’t noticed myself, some encouraging, some…not!

This is very much in the early days of the project, and there’s still plenty to work on. The agent needs more testing and refinement to improve analysis consistency, the code needs a proper review, and Data Lake FIT uploads are still something I do by hand rather than automatically. Future posts will get into all of that.

This project’s brought together a personal hobby and a professional one, and it’s been genuinely satisfying to build. I’ll keep tinkering with it between now and October, race day permitting.

If you’d like to support Pendleside Hospice, you can do so through my JustGiving page.

Like this post? Click the button below for links to contact, socials, projects and sessions:
SharkLinkButton 1

Thanks for reading ~~^~~
Categories
Developing & Application Integration

Low-Code S3 Key Validation With AWS Step Functions & JSONata

In this post, I use JSONata to add low-code S3 object key validation to an AWS Step Functions state machine.

Introduction

In 2024, I worked a lot with AWS Step Functions. I built several for different tasks, wrote multiple blog posts about them and talked about them a fair bit. So when AWS introduced JSONata support for Step Functions last year, I was very interested. Although I had no prior JSONata experience, I heard positive feedback and made a mental note to explore its use cases.

Well, there’s no time like the present! And as I was starting to create the first Project Wolfie resources I realised some of my requirements were a perfect fit.

Firstly, I will examine what JSONata is, how it works and why it’s useful. Next, I will outline my architecture and create some low-code S3 key validation JSONata expressions. Finally, I’ll test these expressions and review their outputs.

JSONata & AWS

This section introduces JSONata and examines its syntax and benefits.

Introducing JSONata

JSONata is a lightweight query and transformation language for JSON, developed by Andrew Coleman in 2016. Specifically inspired by XPath and SQL, it enables sophisticated queries using a compact and intuitive notation.

JSONata provides built-in operators and functions for efficiently extracting and transforming data into any JSON structure. It also supports user-defined functions, allowing for advanced expressions that enhance the querying of dynamic JSON data.

For a visual introduction, check out this JSONata overview:

JSONata Syntax Essentials

JSONata has a simple and expressive syntax. Its path-based approach lets developers easily navigate nested structures. It combines functional programming with dot notation for navigation, brackets for filtering and pipeline operators for chaining.

JSONata operations include transformations like:

  • Arithmetic ($price * 1.2)
  • Conditional Logic ($price > 100 ? 'expensive' : 'affordable').
  • Filtering ($orders[status = 'shipped'])
  • String Operations ($firstName & ' ' & $lastName)

The JSONata site includes full documentation and a JSONata Exerciser for experimenting.

JSONata In AWS Step Functions

JSONata was introduced to AWS Step Functions in November 2024. Using JSONata in Step Functions requires setting the QueryLanguage field to JSONata in the state machine definition. This action replaces the traditional JSONPath fields with two JSONata fields:

  • Arguments: Used to customise data sent to state actions.
  • Output: Used to transform results into custom state output.

Additionally, the Assign field sets variables that can be stored and reused across the workflow.

In AWS Step Functions, JSONata expressions are enclosed in {% %} delimiters but otherwise follow standard JSONata syntax. They access data using the $states reserved variable with the following structures:

  • State input is accessed using $states.input
  • Context information is accessed using $states.context
  • Task results (if successful) are accessed using $states.result
  • Error outputs (if existing) are accessed using $states.errorOutput

Step Functions includes standard JSONata functions as well as AWS-specific additions like $partition, $range, $hash, $random, and $uuid. Some functions, such as $eval, are not supported.

Here are some JSONata examples from the AWS Step Functions Developer Guide:

Plaintext
{% $states.input.title %}

{% $current_price <= $states.input.desired_priced %}

{% $parse($states.input.json_string) %}

Talking more about this subject is AWS Principle Developer Advocate Eric Johnson:

JSONata Benefits

So why is JSONata in AWS a big deal?

Low Maintenance: JSONata use removes the need for Lambda runtime updates, dependency management and security patching. JSONata expressions are self-contained and version-free, reducing debugging and testing effort.

Simpler Development Workflow: JSONata’s standardised syntax removes decisions about languages, runtimes and tooling. This improves consistency, simplifies collaboration and speeds up development.

Releases Capacity: JSONata use reduces reliance on AWS Lambda, freeing up Lambda concurrency slots for more complex tasks. This minimises throttling risks and can lower Lambda costs.

Faster Execution: JSONata runs inside AWS services, avoiding cold starts, IAM role checks and network latency. Most JSONata transformations are complete in milliseconds, making it ideal for high-throughput APIs and real-time systems.

Architecture

This section explains the key features and events used in my low-code S3 validation architecture with JSONata.

Object Created Event

My process starts when an S3 object is created. For this post, I’m using Amazon EventBridge‘s sample S3 Object Created event:

JSON
{
  "version": "0",
  "id": "17793124-05d4-b198-2fde-7ededc63b103",
  "detail-type": "Object Created",
  "source": "aws.s3",
  "account": "123456789012",
  "time": "2021-11-12T00:00:00Z",
  "region": "ca-central-1",
  "resources": ["arn:aws:s3:::example-bucket"],
  "detail": {
    "version": "0",
    "bucket": {
      "name": "example-bucket"
    },
    "object": {
      "key": "example-key",
      "size": 5,
      "etag": "b1946ac92492d2347c6235b4d2611184",
      "version-id": "IYV3p45BT0ac8hjHg1houSdS1a.Mro8e",
      "sequencer": "00617F08299329D189"
    },
    "request-id": "N4N7GDK58NMKJ12R",
    "requester": "123456789012",
    "source-ip-address": "1.2.3.4",
    "reason": "PutObject"
  }
}

Here, the highlighted key field is vital as it identifies the uploaded object. This field will be used in the validation processes.

Choice State

In AWS Step Functions, Choice states introduce conditional logic to a state machine. They assess conditions and guide execution accordingly, allowing workflows to branch dynamically based on input data. When used with JSONata, a Choice state must contain the following fields:

  • Condition field – a JSONata expression that evaluates to true/false.
  • Next field – a value that must match a state name in the state machine.

For example, this Choice state checks if a variable foo equals 1:

Plaintext
{"Condition": "{% $foo = 1 %}",  "Next": "NumericMatchState"}

If $foo = 1, the condition is true and the workflow transitions to a NumericMatchState state.

Architecture Diagram

Now let’s put this all together into an architecture diagram:

Here,

  1. A file is uploaded to an Amazon S3 Bucket.
  2. S3 creates an Object Created event.
  3. Amazon EventBridge matches the event record to an event rule.
  4. Eventbridge executes the AWS Step Functions state machine and passes the event to it as JSON input.
  5. The state machine transitions through the various choice states.
  6. The state machine transitions to the fail state if any choice state criteria are not met.
  7. The state machine transitions to the success state if all choice state criteria are met.

Expression Creation

In this section, I create JSONata expressions to perform low-code S3 validation. For clarity, I’ll use this sample S3 event including an object key which closely resembles my actual S3 path:

JSON
{
  "version": "0",
  ...
  "detail": {
    "version": "0",
    "bucket": {
      "name": "data-lakehouse-raw"
    },
    "object": {
      "key": "iTunes/iTunes-AllTunes-2025-02-01.txt",
      "size": 5,
      ...
    },
    "request-id": "N4N7GDK58NMKJ12R",
    "requester": "123456789012",
    "source-ip-address": "1.2.3.4",
    "reason": "PutObject"
  }
}

S3 Key TXT Suffix Check

This JSONata expression checks if the S3 object key ends with txt:

Plaintext
{% $lowercase($split($split($states.input.detail.object.key, '/')[-1], '.')[-1]) = 'txt' %}

For better readability:

Plaintext
{% 
  $lowercase(
    $split(
      $split($states.input.detail.object.key, '/')[-1], 
    '.')[-1]
  ) = 'txt' 
%}

Let’s walk through this step by step:

1. Accessing The S3 Object Key

Extract the key from the event using $states.input:

Plaintext
$states.input.detail.object.key

➡ Output: "iTunes/iTunes-AllTunes-2025-02-01.txt"

2. Splitting By / To Extract The Filename

Break the key into an array with %split using / as the delimiter:

Plaintext
$split($states.input.detail.object.key, '/')

➡ Output: ["iTunes", "iTunes-AllTunes-2025-02-01.txt"]

Now, retrieve the array’s last element (the object name) using [-1]:

Plaintext
$split(...)[-1]

➡ Output: "iTunes-AllTunes-2025-02-01.txt"

3. Splitting By . To Extract The File Suffix

Break the filename with $split again, using . as the delimiter:

Plaintext
$split($split(...)[-1], '.')

➡ Output: ["iTunes-AllTunes-2025-02-01", "txt"]

Now, retrieve the last element (the suffix) using [-1]:

Plaintext
$split($split(...)[-1], '.')[-1]

➡ Output: "txt"

4. Converting To Lowercase For Case-Insensitive Matching

Use $lowercase to convert the suffix to lowercase:

Plaintext
$lowercase($split(...)[-1], '.')[-1])

➡ Output: "txt"

The $lowercase function ensures consistency, as files with TXT, Txt, or tXt extensions will still match correctly. Here, there is no change as txt is already lowercase.

5. Comparing Against 'txt'

Finally, compare the result to 'txt':

Plaintext
$lowercase($split(...)[-1], '.')[-1]) = 'txt'

➡ Output: true ✅

This means that files ending in .txt pass validation, while others fail.

S3 Key iTunes String Check

This JSONata expression checks if the S3 object key contains iTunes.

Plaintext
{% $contains($split($states.input.detail.object.key, '/')[-1], 'iTunes') %}

For better readability:

Plaintext
{% 
  $contains(
    $split(
      $states.input.detail.object.key, '/')[-1],
    'iTunes'
  ) 
%}

I’m not using $lowercase this time, as iTunes is the correct spelling.

1. Extract The Filename

This is unchanged from the last expression:

Plaintext
$split($states.input.detail.object.key, '/')[-1]

➡ Output: "iTunes-AllTunes-2025-02-01.txt"

2. Check If The String Contains 'iTunes'

The $contains function checks if the string contains the specified substring. It returns true if the substring exists; otherwise, it returns false.

Plaintext
$contains($split(...)[-1], 'iTunes')

➡ Output: true ✅ if 'iTunes' appears anywhere in the filename.

So:

  • ✅ "iTunes-AllTunes-2025-02-01.txt" → true
  • ❌ "itunes-AllTunes-2025-02-01.txt" → false (case-sensitive)

S3 Key Date Check

This JSONata expression checks if the S3 object key contains a date with format YYYY-MM-DD.

Plaintext
{% $exists($match($split($states.input.detail.object.key, '/')[-1], /\d{4}-\d{2}-\d{2}/)) %}

For better readability:

Plaintext
$exists(
  $match(
    $split($states.input.detail.object.key, '/')[-1], 
    /\d{4}-\d{2}-\d{2}/
  )
)

1. Extract The Filename

This is unchanged from the first expression:

Plaintext
$split($states.input.detail.object.key, '/')[-1]

➡ Output: "iTunes-AllTunes-2025-02-01.txt"

2. Apply The Regex Match

The $match function applies the substring to the provided regular expression (regex). If found, an array of objects is returned containing the following fields:

  • match – the substring that was matched by the regex.
  • index – the offset (starting at zero) within the substring.
  • groups – if the regex contains capturing groups (parentheses), this contains an array of strings representing each captured group.

In this JSONata expression:

Plaintext
$match(..., /\d{4}-\d{2}-\d{2}/)

The regex looks for:

  • \d{4} → Four digits (year)
  • - → Hyphen separator
  • \d{2} → Two digits (month)
  • - → Another hyphen
  • \d{2} → Two digits (day)

➡ Output:

JSON
{
  "match": "2025-02-01",
  "index": 16,
  "groups": []
}

3. Convert To Boolean With $exists

I can’t use the $match output yet as the Choice state needs a boolean output. Enter $exists. This function returns true for a successful match; otherwise, it returns false.

Plaintext
$exists($match(..., /\d{4}-\d{2}-\d{2}/))

➡ Output: true ✅ if a date is found.

Here, $exists returns true as a date is present. However, note that JSONata lacks built-in functions to validate dates. For example:

  • "2025-02-01" → true (valid date)
  • "2025-02-31" → true (invalid date but still matches format)

An AWS Lambda function would be needed for strict date validation.

Combining JSONata Expressions

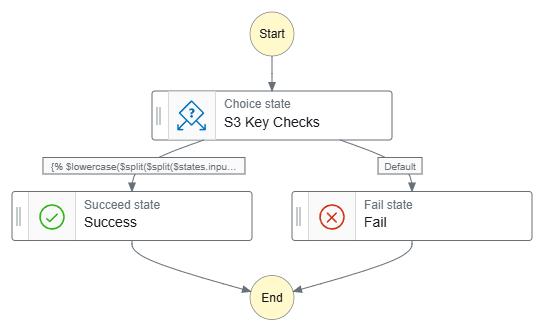
Although I’ve created separate Choice states for each JSONata expression in this section, I will add that all the expressions can be combined into a single Choice state using and:

Plaintext
{% $lowercase($split($split($states.input.detail.object.key, '/')[-1], '.')[-1]) = 'txt' and $contains($split($states.input.detail.object.key, '/')[-1], 'iTunes') and $exists($match($split($states.input.detail.object.key, '/')[-1], /\\d{4}-\\d{2}-\\d{2}/)) %}

For better readability:

Plaintext
{% 
  $lowercase(
    $split(
      $split(
        $states.input.detail.object.key, '/')[-1], '.')[-1]) = 'txt' 
and 
  $contains(
    $split(
      $states.input.detail.object.key, '/')[-1], 'iTunes') 
and 
  $exists(
    $match(
      $split(
        $states.input.detail.object.key, '/')[-1], /\\d{4}-\\d{2}-\\d{2}/)) 
%}

When deciding whether to do this, consider these benefits:

  • Simplified Structure: Reducing the number of states can make the state machine easier to understand and maintain visually. Instead of multiple branching paths, all logic is in one centralised Choice state.
  • Cost Optimisation: AWS Step Functions Standard Workflows pricing is based on the number of state transitions. Combining multiple Choice states into one reduces transitions, potentially lowering costs for high-volume workflows.
  • Minimises Transition Latency: Each state transition adds a slight delay. By managing all logic within a single Choice state, the workflow runs more efficiently due to the reduced transitions.

Against these tradeoffs:

  • Added Complexity: A complex Choice state with many conditions can be difficult to read, debug, and modify. It may require deeply nested logic, which makes future updates challenging.
  • Limited Observability: If multiple conditions are combined into one state, debugging failures becomes more difficult as it is unclear which condition caused an unexpected transition.
  • Potential Scaling Difficulty: As the workflow evolves, adding more conditions to a single Choice state can become unmanageable. Ultimately, this situation may require breaking it up.

Final Workflows

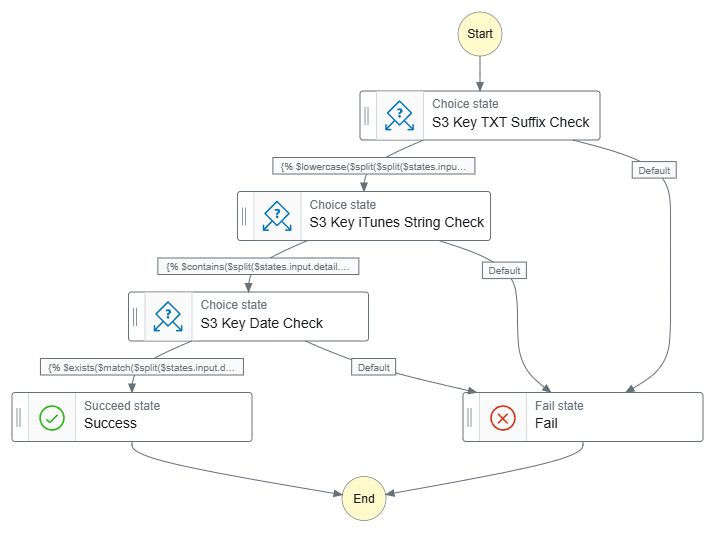
Finally, let’s see what the workflows look like. Firstly, this workflow has separate Choice states for each JSONata expression:

stepfunctions graph Data Ingestion iTunes

Data-Ingestion-iTunes ASL on GitHub.

Next, this workflow has one Choice state for all JSONata expressions:

stepfunctions graph Data Ingestion iTunes all

Data-Ingestion-iTunes-All ASL on GitHub.

Testing

To ensure my low-code JSONata expressions work as expected, I ran several tests against different S3 object keys. These tests validate:

  • File Suffix (.txt)
  • Key Content (iTunes)
  • Date Format (YYYY-MM-DD)

Suffix Validation Tests

Test CaseS3 KeyExpectedActual
✅ Valid Suffix (.txt)"iTunes/iTunes-2025-02-01.txt"Proceed to iTunes Check✅ Success → Next: iTunes String Check
❌ Invalid Suffix (.csv)"iTunes/iTunes-2025-02-01.csv"Fail (No further checks)❌ Failure → No further checks
❌ Missing Suffix"iTunes/iTunes-2025-02-01"Fail (No further checks)❌ Failure → No further checks

Key Content Validation Tests

Test CaseS3 KeyExpectedActual
✅ Valid “iTunes” Key"iTunes/iTunes-2025-02-01.txt"Proceed to Date Check✅ Success → Next: Date Check
❌ Incorrect Case (itunes instead of iTunes)"iTunes/itunes-2025-02-01.txt"Fail (No further checks)❌ Failure → No further checks
❌ Missing Key String""Fail (No further checks)❌ Failure → No further checks

Date Format Validation Tests

Test CaseS3 KeyExpectedActual
✅ Correct Date Format (YYYY-MM-DD)"iTunes/iTunes-2025-02-01.txt"Success (Validation complete)✅ Success → Validation complete!
❌ Incorrect Date Format (Missing Day)"iTunes/iTunes-2025-02.txt"Fail (No further checks)❌ Failure → No further checks
❌ Missing Date"iTunes/iTunes.txt"Fail (No further checks)❌ Failure → No further checks

Edge Case: Impossible Date

Test CaseS3 KeyExpectedActual
⚠️ Impossible Date (2025-02-31)"iTunes/iTunes-2025-02-31.txt"Fail (Ideally)❌ Unexpected Success (JSONata does not validate real-world dates)

These tests confirm that JSONata expressions can effectively validate S3 object keys based on file suffixes, key contents and date formats. However, while JSONata can check formatting (YYYY-MM-DD) it does not validate real-world dates. If strict date validation is needed then an AWS Lambda function would be required.

Summary

In this post, I used JSONata to add low-code S3 object key validation to an AWS Step Functions state machine. This approach simplifies the validation process and reduces the reliance on more complex Lambda functions.

My first impressions of JSONata are very good! It’s already reduced both the number and size of Project Wolfie’s Lambda functions, and there’s still lots of JSONata to explore. In the meantime, these further videos by Eric Johnson explore more advanced JSONata Step Function applications:

If this post has been useful then the button below has links for contact, socials, projects and sessions:

SharkLinkButton 1

Thanks for reading ~~^~~
Categories
Developing & Application Integration

Event-Based Cost Control In AWS Glue: Build

In this post, I build my event-based AWS Glue automated cost control process using serverless managed services.

Introduction

Last time, I examined some unexpected AWS Glue costs and designed an event-based cost control process architecture. I also wrote this user story:

As an AWS account owner, I want Glue interactive sessions to stop automatically after a chosen duration so that I don’t accidentally generate unexpected and avoidable costs.

Here, I’m going to build my event-based Glue cost control process using these AWS services:

  • SNS
  • CloudTrail
  • Step Functions
  • EventBridge
  • CloudWatch

The order is based on dependencies, which I will explain shortly. Some of these resources already exist, so let’s start by reviewing those.

Existing Resources

I have two existing SNS topics that this process will use. These are general-purpose topics used for all my Step Functions notifications. They are:

  • failure-stepfunction
  • success-stepfunction

Both topics are largely alike, with the main difference being the distinct subaddressing in their respective email endpoints.

CloudTrail

Let’s start by examining an AWS Glue CreateSession CloudTrail event record. I haven’t included a full Glue CreateSession CloudTrail event record here because:

  • They’re around 90 lines long. Each.
  • They contain sensitive data.

The AWS documentation covers CloudTrail record contents in full for those curious.

Here’s part of a Glue CreateSession CloudTrail event record. This one shows session glue-studio-datapreview-e09f88a9-4d7f-4e64-95f2-e435fbd1963a:

JSON
{
    "eventSource": "glue.amazonaws.com",
    "eventName": "CreateSession",
    "requestParameters": {
        "id": "glue-studio-datapreview-e09f88a9-4d7f-4e64-95f2-e435fbd1963a",
        "command": {
            "name": "glueetl",
            "pythonVersion": "3"
        },
        "idleTimeout": 30,
        "maxCapacity": 2,
        "glueVersion": "4.0",
        "requestOrigin": "GlueStudioDataPreview"
    },
}

Here, requestParameters contains the new session’s details including its ID:

JSON
{
    "eventSource": "glue.amazonaws.com",
    "eventName": "CreateSession",
    "requestParameters": {
        "id": "glue-studio-datapreview-e09f88a9-4d7f-4e64-95f2-e435fbd1963a",
        "command": {
            "name": "glueetl",
            "pythonVersion": "3"
        },
        "idleTimeout": 30,
        "maxCapacity": 2,
        "glueVersion": "4.0",
        "requestOrigin": "GlueStudioDataPreview"
    },
}

This is the Glue Interactive Session’s unique identifier. I’ll be using this in my event-based Glue cost control build shortly. For now, understand that:

  • The Glue Interactive Session’s ID is found in the event record’s requestParameters object.
  • The requestParameters object is in turn found in the event record’s details object.

This is represented as:

JSON
detail.requestParameters.id

I’m going to pass this ID to a Step Functions state machine later. Speaking of which…

Step Functions

In this section, I start creating my event-based Glue cost control build automation. This consists of two components:

  • An event router – built with an EventBridge rule.
  • A service orchestrator – built with a Step Functions state machine.

Since the state machine will be the EventBridge rule’s target, I must create the state machine first.

State Machine Actions

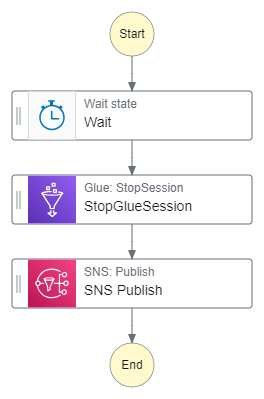
The state machine’s architecture was covered in my previous post. As a reminder, when given a Glue SessionID the state machine must:

  • Wait for a set period.
  • Stop the Glue session.
  • Trigger a confirmation email.

So let’s run through each step, starting with how the Glue SessionID is acquired.

Getting Glue Session ID

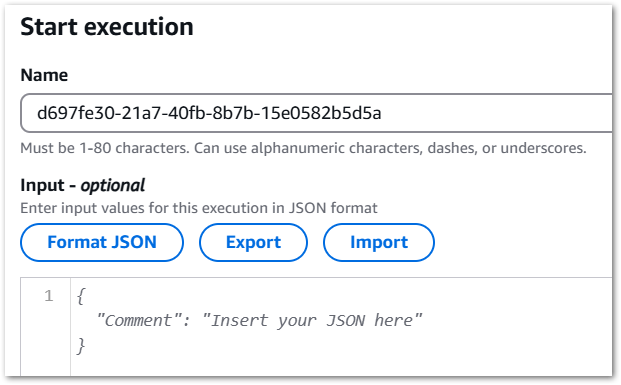
When executing a Step Functions state machine, an optional JSON input can be specified. There are several ways to supply this input:

2024 12 14 StateMachineInputJSON

For my event-based Glue cost control build, a typical JSON input will be:

JSON
{
  "session_id": "glue-studio-datapreview-123-456-789"
}

This can then be used in the other states as "$.session_id"

The state machine must then enter a wait state.

Wait

Step Functions has a built-in Wait state for handling delays. I want a thirty-second delay. This is configurable both in Workflow Studio and Amazon States Language (ASL):

JSON
    "Wait": {
      "Type": "Wait",
      "Seconds": 30,
      "Next": "StopGlueSession"
    },

The state machine must then stop the Glue session.

Glue: Stop Session

To understand what’s needed here, let’s review the Glue StopSession API reference. ID is the only required parameter, which comes from the earlier JSON input.

This is represented in ASL as:

JSON
{
  "Id.$": "$.session_id"
}

Now, as discussed previously, this action can fail. In the example below, a Glue StopSession request fails because the session is still being provisioned. Since nothing has started, there is nothing to stop:

JSON
{
  "cause": "Session is in PROVISIONING status (Service: Glue, Status Code: 400, Request ID: null)",
  "error": "Glue.IllegalSessionStateException",
  "resource": "stopSession",
  "resourceType": "aws-sdk:glue"
}

To that end, I’ve added retry parameters. Upon error, StopGlueSession will retry three times, with a ten-second delay between attempts. If the third retry fails, then the state machine’s error handling will be invoked.

This is the state’s ASL:

JSON
    "StopGlueSession": {
      "Type": "Task",
      "Resource": "arn:aws:states:::aws-sdk:glue:stopSession",
      "Parameters": {
        "Id.$": "$.session_id"
      },
      "Next": "SNS Publish",
      "Retry": [
        {
          "ErrorEquals": [
            "States.ALL"
          ],
          "IntervalSeconds": 10,
          "MaxAttempts": 3
        }
      ]
    },

Where:

  • "Id.$": "$.session_id" is the Glue SessionID from the JSON input.
  • "ErrorEquals": ["States.ALL"] captures all errors.
  • "IntervalSeconds": 10, "MaxAttempts": 3 sets the retry parameters.

Finally, the state machine must trigger a confirmation email.

SNS: Publish

I usually avoid state machine success notifications to avoid alarm fatigue, but I decided to include them here for two reasons:

  • I can check the state machine is working without accessing AWS.
  • I can see excessive activity without viewing logs.

Here, I publish a message to my existing success-stepfunction SNS topic using SNS’s optimised integration:

JSON
"SNS Publish": {
      "Type": "Task",
      "Resource": "arn:aws:states:::sns:publish",
      "Parameters": {
        "TopicArn": "arn:aws:sns:eu-west-1:[REDACTED]:success-stepfunction",
        "Message.$": "States.Format('Hi! AWS Step Functions has stopped this Glue session for you: {}', $)"
      },
      "End": true
    }

I customised the Message.$ parameter using the States.Format intrinsic function:

  • The string starting with 'Hi!... is the message I want SNS to use.
  • {} is a placeholder for the value I want to insert.
  • $ is the state machine data to insert into {}

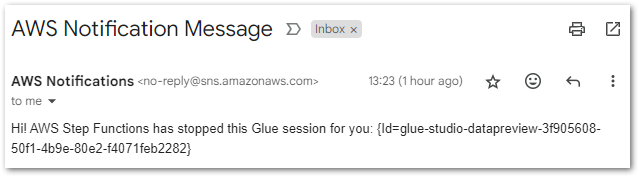
This produces a better email notification for the user:

Hi! AWS Step Functions has stopped this Glue session for you: {Id=glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282}

Finally, "End": true stops the state machine.

Final Workflow

The state machine is now as follows:

stepfunctions graph

With this auto-generated ASL:

JSON
{
  "StartAt": "Wait",
  "States": {
    "Wait": {
      "Type": "Wait",
      "Seconds": 30,
      "Next": "StopGlueSession"
    },
    "StopGlueSession": {
      "Type": "Task",
      "Resource": "arn:aws:states:::aws-sdk:glue:stopSession",
      "Parameters": {
        "Id.$": "$.session_id"
      },
      "Next": "SNS Publish",
      "Retry": [
        {
          "ErrorEquals": [
            "States.ALL"
          ],
          "IntervalSeconds": 10,
          "MaxAttempts": 3
        }
      ]
    },
    "SNS Publish": {
      "Type": "Task",
      "Resource": "arn:aws:states:::sns:publish",
      "Parameters": {
        "TopicArn": "arn:aws:sns:eu-west-1:[REDACTED]:success-stepfunction",
        "Message.$": "States.Format('Hi! AWS Step Functions has stopped this Glue session for you: {}', $)"
      },
      "End": true
    }
  },
  "Comment": "When given a Glue SessionID start a wait, stop the session and send an SNS message."
}

There’s one more aspect to sort out. What happens if the state machine fails?

Error Logging

Firstly, let’s examine the state of events if the state machine fails:

  • A Glue session must have started.
  • An Eventbridge Rule must have sent the event to Step Functions.
  • One of the state machine states must have failed.

Unless the failing state is SNS:Publish, then there is an active Glue session still incurring costs. Therefore, triggering an alarm is much more appropriate than a notification. Alarm creation requires sending the state machine logs to CloudWatch.

By default, new state machines do not enable logging due to storage expenses. However, in this case, the log storage cost will be significantly lower than that of an unattended Glue Session. So I activate the logging for my state machine.

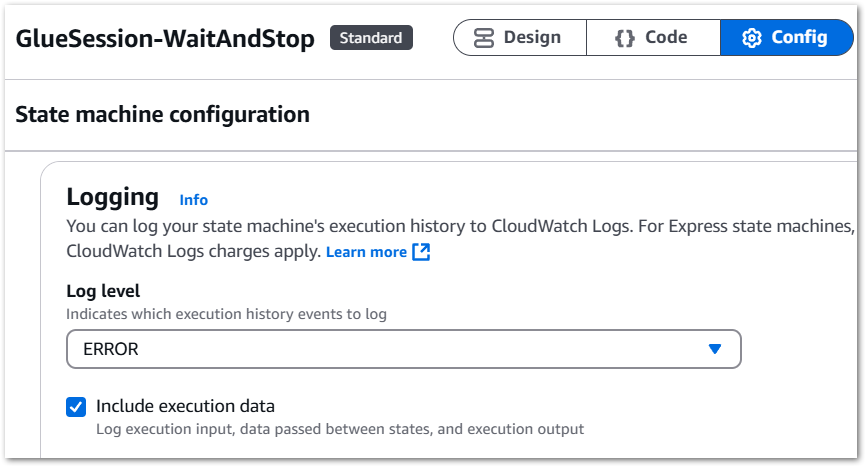
Step Functions log levels range from ALL to ERROR to FATAL to OFF, which are explained in the AWS documentation. As I’m only interested in failures, I select ERROR and include the execution data. This consists of execution input, data passed between states and execution output:

2024 12 14 StateMachineLogging

Next, I create a new CloudWatch log group called /aws/vendedlogs/states/GlueSession-WaitAndStop-Logs. This will form the basis of my failure alerting.

CloudWatch

Here, I configure the CloudWatch resources for my event-based Glue cost control build.

Log Groups & Metrics

The previously configured GlueSession-WaitAndStop-Logs group receives all the Step Functions state machine’s ERROR events. In most cases, these are Glue.IllegalSessionStateException events:

JSON
{
    "id": "7",
    "type": "TaskFailed",
    "details": {
        "cause": "Session is in PROVISIONING status (Service: Glue, Status Code: 400, Request ID: b1baaf14-ae89-4106-a286-87cf5445de6c)",
        "error": "Glue.IllegalSessionStateException",
        "resource": "stopSession",
        "resourceType": "aws-sdk:glue"
    },

Note the TaskFailed event type – it indicates the failure of a single state, not the entire state machine. Thus, I don’t need alerts for those events.

However, there are also ExecutionFailed events like these:

JSON
{
    "id": "5",
    "type": "ExecutionFailed",
    "details": {
        "cause": "An error occurred while executing the state 'StopGlueSession' (entered at the event id #4). The JSONPath '$.session_id' specified for the field 'Id.$' could not be found in the input '{\n  \"sessionId\": \"\"\n}'",
        "error": "States.Runtime"
    },

I definitely want to know about these! ExecutionFailed means the entire state machine failed, and there’s probably a Glue Session still running!

These events are captured as ExecutionsFailed CloudWatch metrics. Keep in mind that the AWS Step Functions console automatically publishes various metrics irrespective of logging configurations, including ExecutionFailed. However, in my experience, having both the metrics and failure logs centralised in CloudWatch simplifies troubleshooting.

Next, let’s use these metrics to create an alarm.

Alarm

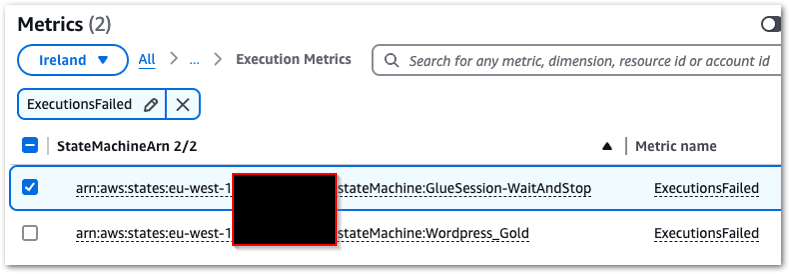
Creating a CloudWatch alarm begins with selecting the ExecutionsFailed metric from States > Execution Metrics

2024 12 13 CWMetrics

This alarm will have a static value threshold with a value greater than zero, which is checked every minute. When the alarm’s state is In Alarm, an email notification will be sent to my failure-stepfunction SNS topic.

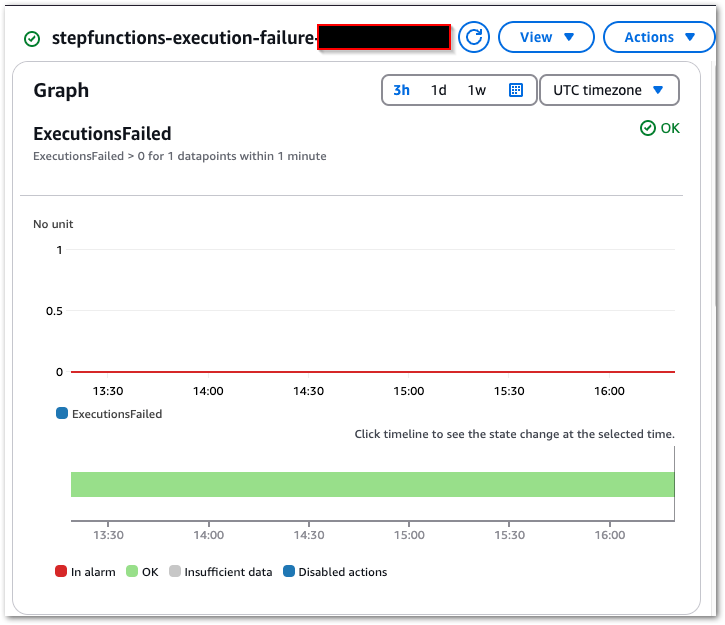
Finally, CloudWatch creates a new alarm graph:

2024 12 13 CWAlarm

So that’s everything state machine needs. Next, how do I pass the Glue SessionID to it?

EventBridge

In this section, I create the EventBridge Rule responsible for handling my event-based Glue cost control build’s events.

EventBridge Rule Anatomy

EventBridge Rules specify the criteria for routing events from an event bus to designated targets like Lambda functions, Step Functions and SQS queues. They use event patterns to filter incoming events and identify targets to route to, enabling event-driven and event-based workflows without custom processing logic.

Creating an EventBridge Rule involves three steps:

  • Define rule detail
  • Build event pattern
  • Select target

Define Rule Detail

Besides the name and description, this section is mainly concerned with:

  • Event Bus: The event bus to monitor for events. Default is fine.
  • Rule Type: EventBridge’s rule type. This can either match an event pattern or operate on a schedule (this is different from EventBridge Scheduler – Ed).

Next, let’s discuss event patterns!

Build Event Pattern

Firstly, event patterns are a very expansive topic, so please refer to the EventBridge user guide afterwards for definitions and examples.

Event patterns act as filters, defining how EventBridge identifies whether to send an event to a target. The EventBridge console provides options for sample events and testing patterns.

As a reminder, this is part of a typical CreateSession event record from which I want to capture ID:

JSON
"eventSource": "glue.amazonaws.com",
"eventName": "CreateSession",
"requestParameters": {
  "id": "glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282",
  "role": "arn:aws:iam::[REDACTED]:role/service-role/AWSGlueServiceRole-wordpress_bronze",
        "command": {
            "name": "glueetl",
            "pythonVersion": "3"
        },
        "idleTimeout": 30
....

EventBridge currently has three pattern creation methods:

  • Schema: Using either manual entry or the schema registry.
  • Pattern Form: Using pre-defined EventBridge templates.
  • Custom Pattern: Using a manual JSON editor.

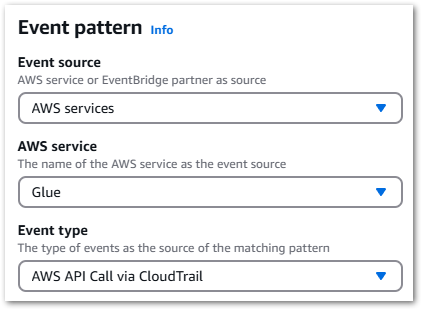
Pattern Form offers a series of dropdowns that quickly construct the desired pattern:

2024 12 28 EventBridgeEventPattern

Selecting AWS Services > Glue > AWS API Call via CloudTrail creates this event pattern:

JSON
{
  "source": ["aws.glue"],
  "detail-type": ["AWS API Call via CloudTrail"],
  "detail": {
    "eventSource": ["glue.amazonaws.com"]
  }
}

This will send all Glue events to the target, so it could use some refinement. An eventName can be added to the pattern either by manual editing or via the Specific Operation(s) setting.

The updated pattern will now only send Glue CreateSession events:

JSON
{
  "source": ["aws.glue"],
  "detail-type": ["AWS API Call via CloudTrail"],
  "detail": {
    "eventSource": ["glue.amazonaws.com"],
    "eventName": ["CreateSession"]
  }
}

Select Target

Finally, I must select the EventBridge Rule’s target – my state machine. This is why I created the state machine first; for it to be an EventBridge target it must first exist.

At this point, I could pass the whole event to the state machine. However, the state machine had no way to parse the SessionID from the event. While JSONata could now meet this requirement, it wasn’t a Step Functions feature back in June.

Luckily, EventBridge offers relevant settings here. One of these – an Input Transformer – can customise an event’s text before EventBridge sends it to the rule’s target. Input Transformers consist of an Input Path and Input Template.

An Input Path uses a JSON path and key-value pairs to reference items in events and store them as variables. For instance, capturing ID from this event:

JSON
"eventSource": "glue.amazonaws.com",
"eventName": "CreateSession",
"requestParameters": {
  "id": "glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282",
  "role": "arn:aws:iam::[REDACTED]:role/service-role/AWSGlueServiceRole-wordpress_bronze",
        "command": {
            "name": "glueetl",
            "pythonVersion": "3"
        },
        "idleTimeout": 30
....

Requires this Input Path:

JSON
{
  "id": "$.detail.requestParameters.id"
}

In which:

  1. $.detail accesses the detail object of the CloudTrail event record.
  2. $.detail.requestParameters accesses the requestParameters object within detail.
  3. Finally, $.detail.requestParameters.id accesses the id value within requestParameters.

This is passed to an Input Template, mapping the path’s output to a templated key-value pair. This is then passed to the rule target verbatim, replacing placeholders with the Input Path values.

So this template:

JSON
{
  "session_id": "<id>"
}

Produces a JSON object comprising a "session_id": string and the Input Path’s Glue SessionID value:

JSON
{
  "session_id": "glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282"
}

This will be passed as the JSON input when executing the state machine.

That’s everything done now. So let’s see if it works!

Testing

This section tests my event-based Glue cost control build.

In the following tests, a Glue Interactive Session was started with the build fully active and was observed in the AWS console. AWS assigned the SessionID glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282.

EventBridge Rule

Expectation: When a Glue CreateSession CloudTrail event record is created:

  • EventBridge matches the CloudTrail event record to my EventBridge Rule.
  • The EventBridge Rule triggers and defines a session_id variable.
  • The EventBridge Rule executes my target state machine with session_id JSON input.

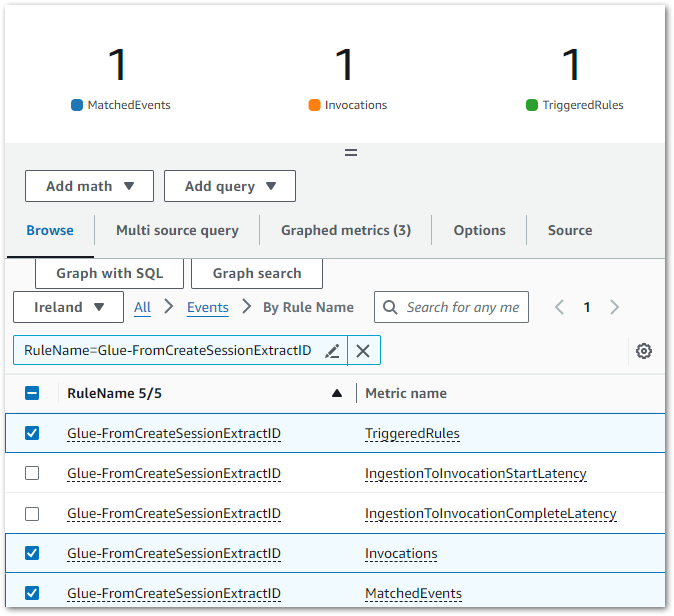
Result: CloudWatch indicates EventBridge matched the CloudTrail Event Record to my EventBridge Rule’s Event Pattern, executing the intended actions:

2024 06 11 EventBridgeCWGraph

The EventBridge Rule’s extracts the glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282 SessionID from the CloudTrail Event Record and adds it as a JSON input when executing the targeted GlueSession-WaitAndStop state machine.

Step Functions State Machine

Expectation: When a Glue CreateSession CloudTrail event record is created:

  • State machine is executed with session_id JSON input.
  • Glue StopSession API is called after 30 seconds.
  • If the first StopSession API call fails, a retry occurs after ten seconds.
  • A confirmation email is sent to the user.

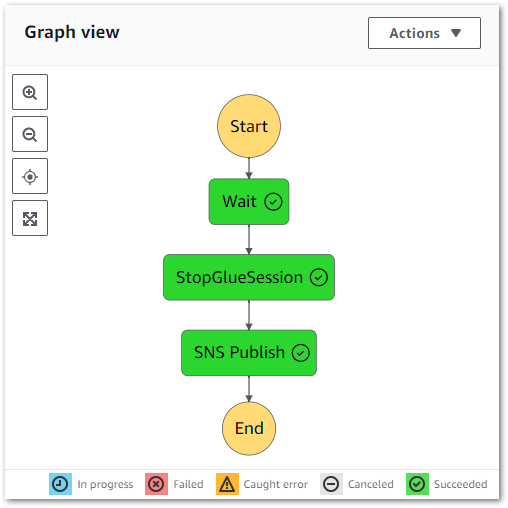
Result: State machine executes successfully:

2024 06 11 StepFGraph

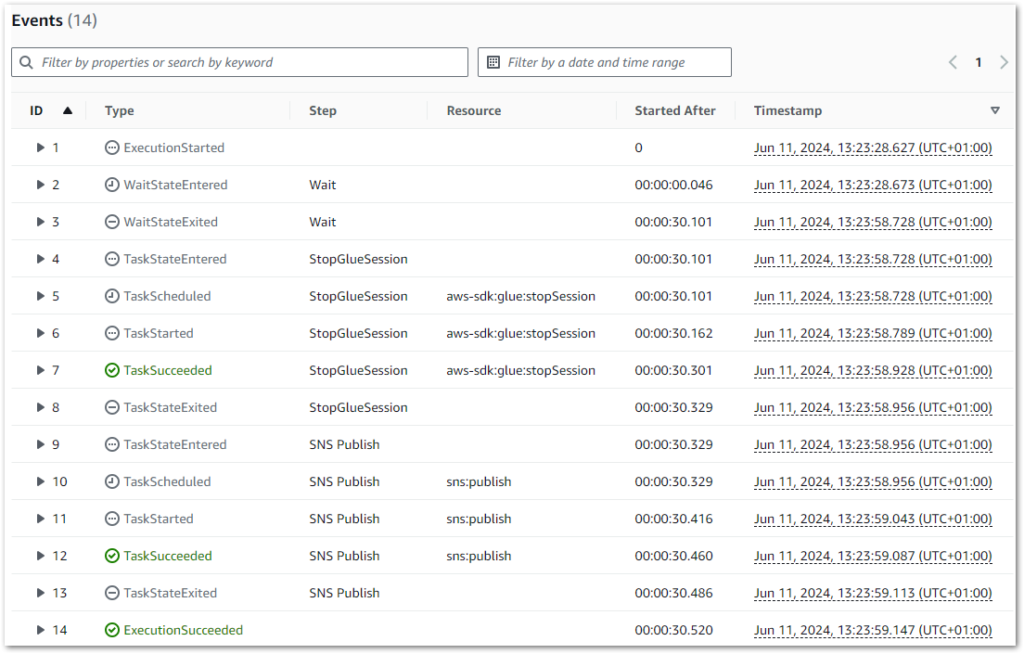
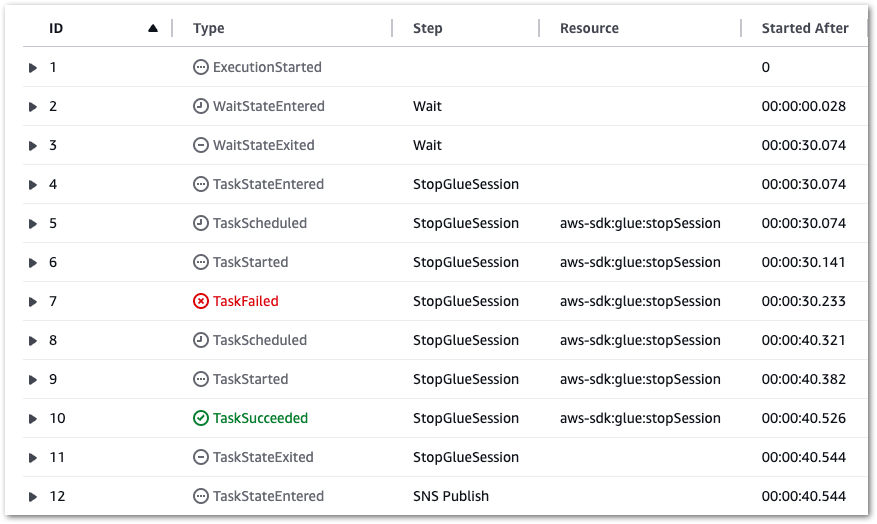
The state machine logs also correctly show a thirty-second wait between rows 2 and 3 (the start and end of the Wait state):

2024 06 11 StepFExec

Additionally, if a Glue.IllegalSessionStateException error occurs, a retry occurs after ten seconds (see rows 7 and 8):

2024 12 13 SFRetry

Finally, SNS sends the correct email to the user:

2024 06 11 GmailNotif

The failure alarm is tested later.

Glue Session

Expectation: When an Interactive Session starts while the EventBridge Rule is enabled, it is automatically stopped thirty seconds after becoming active.

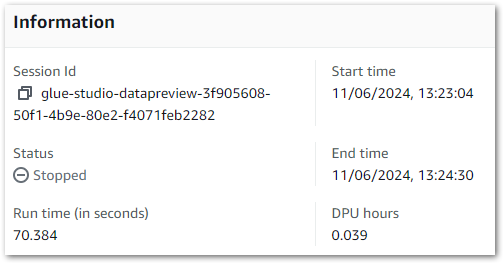
Result: This session runs for seventy seconds. Although this exceeds thirty seconds, keep in mind that the session needs to be provisioned before it can be stopped.

2024 06 11 GlueSessionConsole

These results can also be verified using the Glue Get-Session AWS CLI command:

Bash
[cloudshell-user@ip-[REDACTED] ~]$ aws glue get-session --id glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282

{
    "Session": {
        "Id": "glue-studio-datapreview-3f905608-50f1-4b9e-80e2-f4071feb2282",
        "CreatedOn": "2024-06-11T12:23:04.586000+00:00",
        "Status": "STOPPED",
        
	[REDACTED]
	
        "WorkerType": "G.1X",
        "CompletedOn": "2024-06-11T12:24:30.210000+00:00",
        "ExecutionTime": 70.384,
        "DPUSeconds": 140.768,
        "IdleTimeout": 30
    }
}
(END)

CloudWatch Alarm

The CloudWatch Alarm was tested by briefly changing the Step Function state machine’s IAM policy to deny the StopSession action and then starting a new Interactive Session, forcing the desired failure without altering the cost control process itself.

Expectation: If the state machine fails, then a CloudWatch Alert is sent to the user.

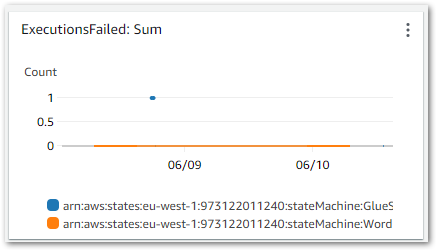
Result: Upon the state machine’s failure, an ExecutionsFailed metric is emitted to CloudWatch, shown in this chart:

2024 06 11 CloudWatchMetric

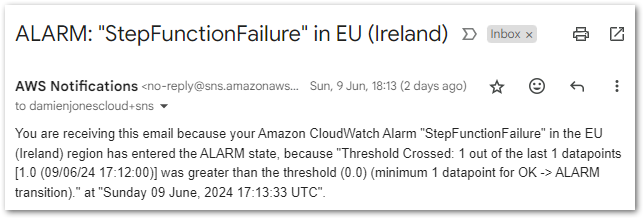
This triggers the CloudWatch Alarm when its Sum > 0 threshold condition is met, changing the alarm’s state to In Alarm and sending an email notification using my failure-stepfunction SNS topic:

2024 06 11 CloudWatchAlerting

And with that, all tests are successful. Now let’s look at the costs.

Cost Analysis

This section analyses the costs of my event-based Glue cost control build. There are two aspects to this:

  • Cost Expenditure: How much is the cost control process costing me to run?
  • Cost Savings: How much money am I saving on the stopped Glue Sessions?

Because the biggest test of all is whether this build satisfies the user story. Does it prevent unexpected and avoidable costs?

Cost Expenditure

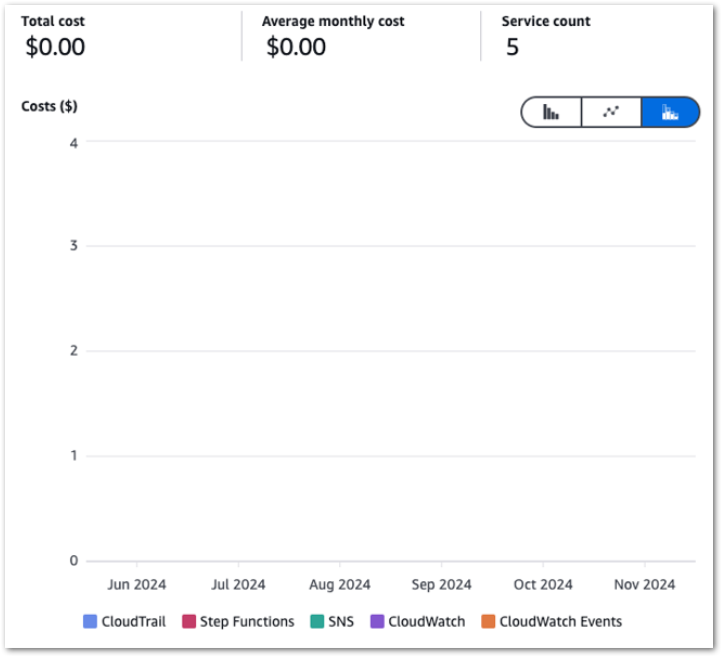
Firstly, let’s examine my event-based Glue cost control build costs between June 2024 and November 2024:

2024 12 13 CostsZero

So I guess this kinda makes my point. Zero cost doesn’t mean zero usage though, so let’s check the bills for that period.

Caveat: I didn’t tag any of my resources (yes ok I know), so this usage is for the entire account.

CloudTrail & CloudWatch Usage

CloudTrail FreeEventsRecorded:

Service Period Metric Quantity
CloudTrail 2024-06 FreeEventsRecorded 33,217
CloudTrail 2024-07 FreeEventsRecorded 28,993
CloudTrail 2024-08 FreeEventsRecorded 40,682
CloudTrail 2024-09 FreeEventsRecorded 29,891
CloudTrail 2024-10 FreeEventsRecorded 36,208
CloudTrail 2024-11 FreeEventsRecorded 28,630

CloudWatch Alarms:

Service Period Metric Quantity
CloudWatch 2024-06 Alarms 0.919
CloudWatch 2024-07 Alarms 2
CloudWatch 2024-08 Alarms 2.126
CloudWatch 2024-09 Alarms 2
CloudWatch 2024-10 Alarms 2
CloudWatch 2024-11 Alarms 2

CloudWatch Metrics:

Service Period Metric Quantity
CloudWatch 2024-06 Metrics 5.29
CloudWatch 2024-07 Metrics 0.372
CloudWatch 2024-08 Metrics 4.766
CloudWatch 2024-09 Metrics 0.003
CloudWatch 2024-10 Metrics 4.003
CloudWatch 2024-11 Metrics 4.626

CloudWatch Requests:

Service Period Metric Quantity
CloudWatch 2024-06 Requests 696
CloudWatch 2024-07 Requests 15
CloudWatch 2024-08 Requests 230
CloudWatch 2024-09 Requests 0
CloudWatch 2024-10 Requests 181
CloudWatch 2024-11 Requests 122

EventBridge, SNS & Step Functions Usage

EventBridge EventsInvocation:

Service Period Metric Quantity
EventBridge 2024-06 EventsInvocation 30
EventBridge 2024-07 EventsInvocation 31
EventBridge 2024-08 EventsInvocation 31
EventBridge 2024-09 EventsInvocation 30
EventBridge 2024-10 EventsInvocation 31
EventBridge 2024-11 EventsInvocation 30

SNS NotificationDeliveryAttempts-SMTP:

Service Period Metric Quantity
SNS 2024-06 NotificationDeliveryAttempts-SMTP 52
SNS 2024-07 NotificationDeliveryAttempts-SMTP 29
SNS 2024-08 NotificationDeliveryAttempts-SMTP 85
SNS 2024-09 NotificationDeliveryAttempts-SMTP 2
SNS 2024-10 NotificationDeliveryAttempts-SMTP 58
SNS 2024-11 NotificationDeliveryAttempts-SMTP 11

SNS Requests:

Service Period Metric Quantity
SNS 2024-06 Requests-Tier1 315
SNS 2024-07 Requests-Tier1 542
SNS 2024-08 Requests-Tier1 553
SNS 2024-09 Requests-Tier1 325
SNS 2024-10 Requests-Tier1 366
SNS 2024-11 Requests-Tier1 299

Step Functions StateTransition:

Service Period Metric Quantity
Step Functions 2024-06 StateTransition 388
Step Functions 2024-07 StateTransition 180
Step Functions 2024-08 StateTransition 566
Step Functions 2024-09 StateTransition 300
Step Functions 2024-10 StateTransition 616
Step Functions 2024-11 StateTransition 362

All within free tier. So how did Glue fare?

Cost Savings

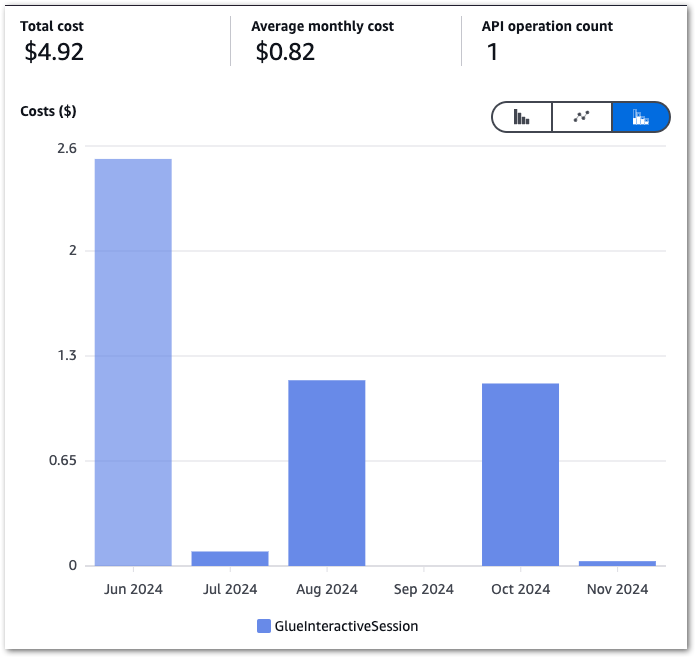
Next, let’s pull my InteractiveSessions costs between June 2024 and November 2024:

2024 12 13 CostsGlue

The high June costs kickstarted this process, and there’s a massive difference between June and the others! September isn’t a mistake – I was kinda busy.

Glue Costs

Here are the actual costs:

Service Period Metric Quantity Cost $
Glue 2024-06 InteractiveSessions 5.731 DPU-Hour 2.52
Glue 2024-07 InteractiveSessions 0.197 DPU-Hour 0.09
Glue 2024-08 InteractiveSessions 2.615 DPU-Hour 1.15
Glue 2024-09 InteractiveSessions 0.000 DPU-Hour 0.00
Glue 2024-10 InteractiveSessions 2.567 DPU-Hour 1.13
Glue 2024-11 InteractiveSessions 0.079 DPU-Hour 0.03
TOTAL 4.92

While these aren’t exactly huge sums, there are two items to consider here:

Glue Estimated Savings

Finally, what saving does this represent? While I can’t get a value from AWS Billing, I can reasonably estimate one. Firstly, using the AWS Calculator for Glue I calculated the cost of an Interactive Session that times out:

2 DPUs x 0.50 hours x 0.44 USD per DPU-Hour = 0.44 USD

https://calculator.aws/#/createCalculator/Glue

Next, I went back through my records and found how many sessions had been stopped each month:

Period Stops
2024-06 11
2024-07 5
2024-08 61
2024-09 0
2024-10 53
2024-11 2

Caveat: To be fair to AWS, some sessions were created while I was working on a Glue ETL job with automation enabled. So, while the automation was continually stopping sessions, I was constantly starting new ones. Thus, Glue isn’t the money pit I perhaps make out, and I’m not that careless with leaving them on!

By multiplying the number of stopped sessions by 0.44, I can determine each month’s potential cost, then subtract the actual cost to find the estimated savings:

Period Stops Potential Cost $ Actual Cost $ Est. Saving $
2024-06 11 4.84 2.52 2.32
2024-07 5 2.20 0.09 2.11
2024-08 61 26.84 1.15 25.69
2024-09 0 0.00 0.00 0.00
2024-10 53 23.32 1.13 22.19
2024-11 2 0.88 0.03 0.85
TOTAL 132 58.08 4.92 53.16

Almost $55! Even if I reduce that by 50% based on the caveat, that’s still around a $25 saving. And with no setup costs!

Summary

In this post, I built my event-based AWS Glue automated cost control process using serverless managed services.

I’m pleased with the outcome! My generally busy Summer and Autumn inadvertently tested this process for six months, and it’s been fine throughout! I may soon extend the state machine’s waiting duration, which only needs a parameter change for one state.

The great thing about this process is that it isn’t limited to Glue; EventBridge can use nearly all AWS services as event sources. I’m seriously impressed with EventBridge. It’s poked me about Glacier restores, scheduled my ETLs and now is also saving me a few quid!

If this post has been useful then the button below has links for contact, socials, projects and sessions:

SharkLinkButton 1

Thanks for reading ~~^~~